API Content Preview

Latest objects from all public post types.

Article

Sam Altman says we need another Renaissance. But we really need another Industrial Revolution.

Originally published in Fortune.

Sam Altman doesn’t understand history. His mistake is going to punish the world.

That’s the depressing takeaway from the OpenAI’s CEO’s September 23rd speech to the United Nations. He came out swinging, saying that “we,” as in humanity, “have a choice in front of us.” AI, he said, “can either be more like a new Renaissance of creativity and discovery, or more like a new Industrial Revolution of upheaval and disarray.” He ended by calling for international “cooperation” and “standards.” In short, an AI regulatory regime that brings us to the promised land of another Renaissance instead of the chaos of another Industrial Revolution.

But that’s backward. The Renaissance, for all its artistic beauty, was not a time of meaningful economic, social, and political progress. Humanity’s material condition did not meaningfully improve, nor did democracy advance apace. When Thomas Hobbes described life in the state of nature “as poor, nasty, brutish and short,” he may as well have been talking about post-Renaissance existence, as well. An English builder’s day wage bought less food in 1600 than it had in 1475. The magnificent art didn’t do much material good for those who mixed the plaster.

Don’t get me wrong: The Renaissance wasn’t a failure. Michelangelo’s David and the Sistine Chapel ceiling are treasures that all of humanity should appreciate. So are Leonardo da Vinci’s notebooks, filled with flying machines, batlike wings worked by a pilot pumping pedals. But frescos don’t put shoes on a poor child’s cold feet and sketches of flying machines didn’t put Orville Wright in the sky. True progress didn’t happen until—you guessed it—the Industrial Revolution.

What Mr. Altman describes as “upheaval and disarray” was, in fact, the beginning of the greatest and most sustained improvement in humanity’s material condition. Around 1800, one English child in three died before age 5; today it is about one in 200. Before the Industrial Revolution, only a relative handful of people had ever seen Michelangelo’s David. But in 1857, a full-size cast of the David went on view at London’s new South Kensington Museum, which soon lit its galleries with gas so working people could see it after their shifts. Life expectancy has doubled, giving us the miracle of great grandparents meeting their great grandchildren.

Why did the Industrial Revolution succeed far more than the Renaissance? The answer comes down to one word: Power.

For all its flowering of original thought and creativity, the Renaissance was ultimately a time of patronage, and the patrons both held the power and used it to enrich their own palaces and places of worship. What did they do to improve the plight of the great mass of people? Not much. But the Industrial Revolution shifted power to the masses, with democracy, individual rights, and the freedom to innovate. That era’s patrons, like Andrew Carnegie, still get the headlines. But it was everyday innovators like Wilbur and Orville Wright who showed that the masses really move humanity forward.

And that’s why Mr. Altman’s misunderstanding is so concerning. If adopted, his argument will hold humanity back. The regulatory regime that he hinted at in his United Nations speech, and that he and other AI company CEOs have called for in recent weeks, threatens the return of the Renaissance-style patronage. Despite their claims to the contrary, it will cement the power of existing companies—like Mr. Altman’s own—and give new and untold power to armies of bureaucrats. Davos Man will do just fine, because Davos Men will still be in charge. But what about the rest of us, the regular humans, who stand to gain the most from the cures and creations that AI could bring?

With artificial intelligence, we don’t need another Renaissance patronage story. Modern-day courtiers and princes–to say nothing of bureaucrats–should not be the ones deciding what gets made and who gets to see it. We need another Industrial Revolution diffusion story, with everyday people using technology to drive rapid and radical improvements in daily life. That’s the only way living standards have ever improved, and the past 200 years are the proof. Leonardo da Vince drew the flying machine at a prince’s court. But it took two bicycle mechanics in Dayton to build it 400 years later.

Sam Altman needs to learn his history, because he’s demanding a future that works first and foremost for elites like him.

Custom Fields

authors
hook
If adopted, his argument will hold humanity back. The regulatory regime that he hinted at in his United Nations speech, and that he and other AI company CEOs have called for in recent weeks, threatens the return of the Renaissance-style patronage.
category
Op-eds
social_image
article
false
include_in_hero_section
false
topic
  • Technology
technology_subtopic
  • Artificial intelligence
article_view
article content only
hide_from_our_work
false
Article

Data Centers Power Everything You Do Online

Bottom Line

Data centers are the physical backbone of the digital economy. Every email, card payment, weather forecast, video call, and AI query runs on computers housed in them. Hospitals, banks, schools, and governments depend on them every day. States that welcome data centers can attract billions in investment, put downward pressure on electricity prices, and fund schools and public safety, while protecting ratepayers and local water.

Core Rule: Make sure whoever causes extra costs pays for them, build more capacity, and judge each project by its full economic value.

Why Data Centers Matter

  1. Fewer sepsis deaths. Johns Hopkins used AI to catch sepsis hours earlier than traditional methods, making patients 20% less likely to die.
  2. Faster wildfire response. AI-equipped cameras in Cal Fire dispatch centers have spotted fires before 911 calls did more than 30% of the time, speeding up response time before the fires spread further.
  3. Good jobs at high wages. Since 2023, the US has added more than 750,000 AI-related jobs, with a median advertised salary of about $180,000, more than double the median across all job postings.
  4. Historic investment. A Brookings study estimates that the United States could invest $10.3 trillion in AI infrastructure between 2025 and 2032, one of the largest bets on a single industry in American history.

Common Concerns — And What Actually Happens

Data Centers Can Pay for Grid Upgrades and Reduce Electricity Bills

  • Concern: More electricity demand must mean higher prices.
  • In practice: A 2025 Berkeley Lab and Brattle Group analysis found that state-level load growth has generally put downward pressure on retail electricity prices by spreading fixed grid costs across more sales. Indiana Michigan Power, Entergy Mississippi, and Georgia Power have all requested residential rate reductions because of data center investments.,, Where supply is scarce or the grid needs major upgrades, costs can rise.
  • Takeaway: Public policy should protect ratepayers while also meeting growing demand with more supply.

AI Is Not Creating a National Water Crisis

  • Concern: Data centers use substantial water for cooling, especially in hot or water-stressed areas.
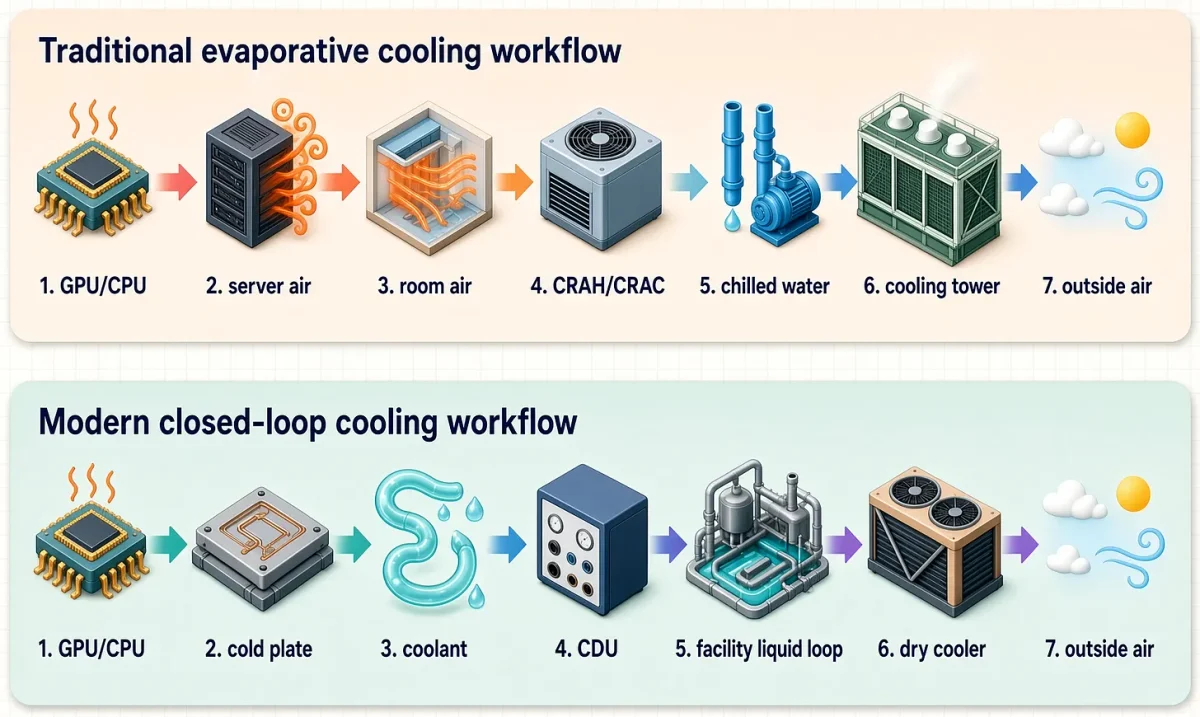
  • In practice: Water use varies enormously by location and cooling technology. Air cooling, closed-loop systems, reclaimed water, and liquid cooling can sharply reduce a facility’s footprint. The key distinction, informed by Berkeley Lab’s national assessment, is local versus national: a large facility can matter to one watershed or exist in a community with plenty of water resources. Furthermore, concerns from communities are incentivizing innovation in cooling technology – one developer has increased water efficiency by 52 percent in the last five years.
  • Takeaway: Treat water as a siting and engineering question, not a national generalization.

More AI Doesn’t Mean Electricity Use Has to Skyrocket

  • Concern: If computing grows rapidly, electricity use must grow at the same rate.
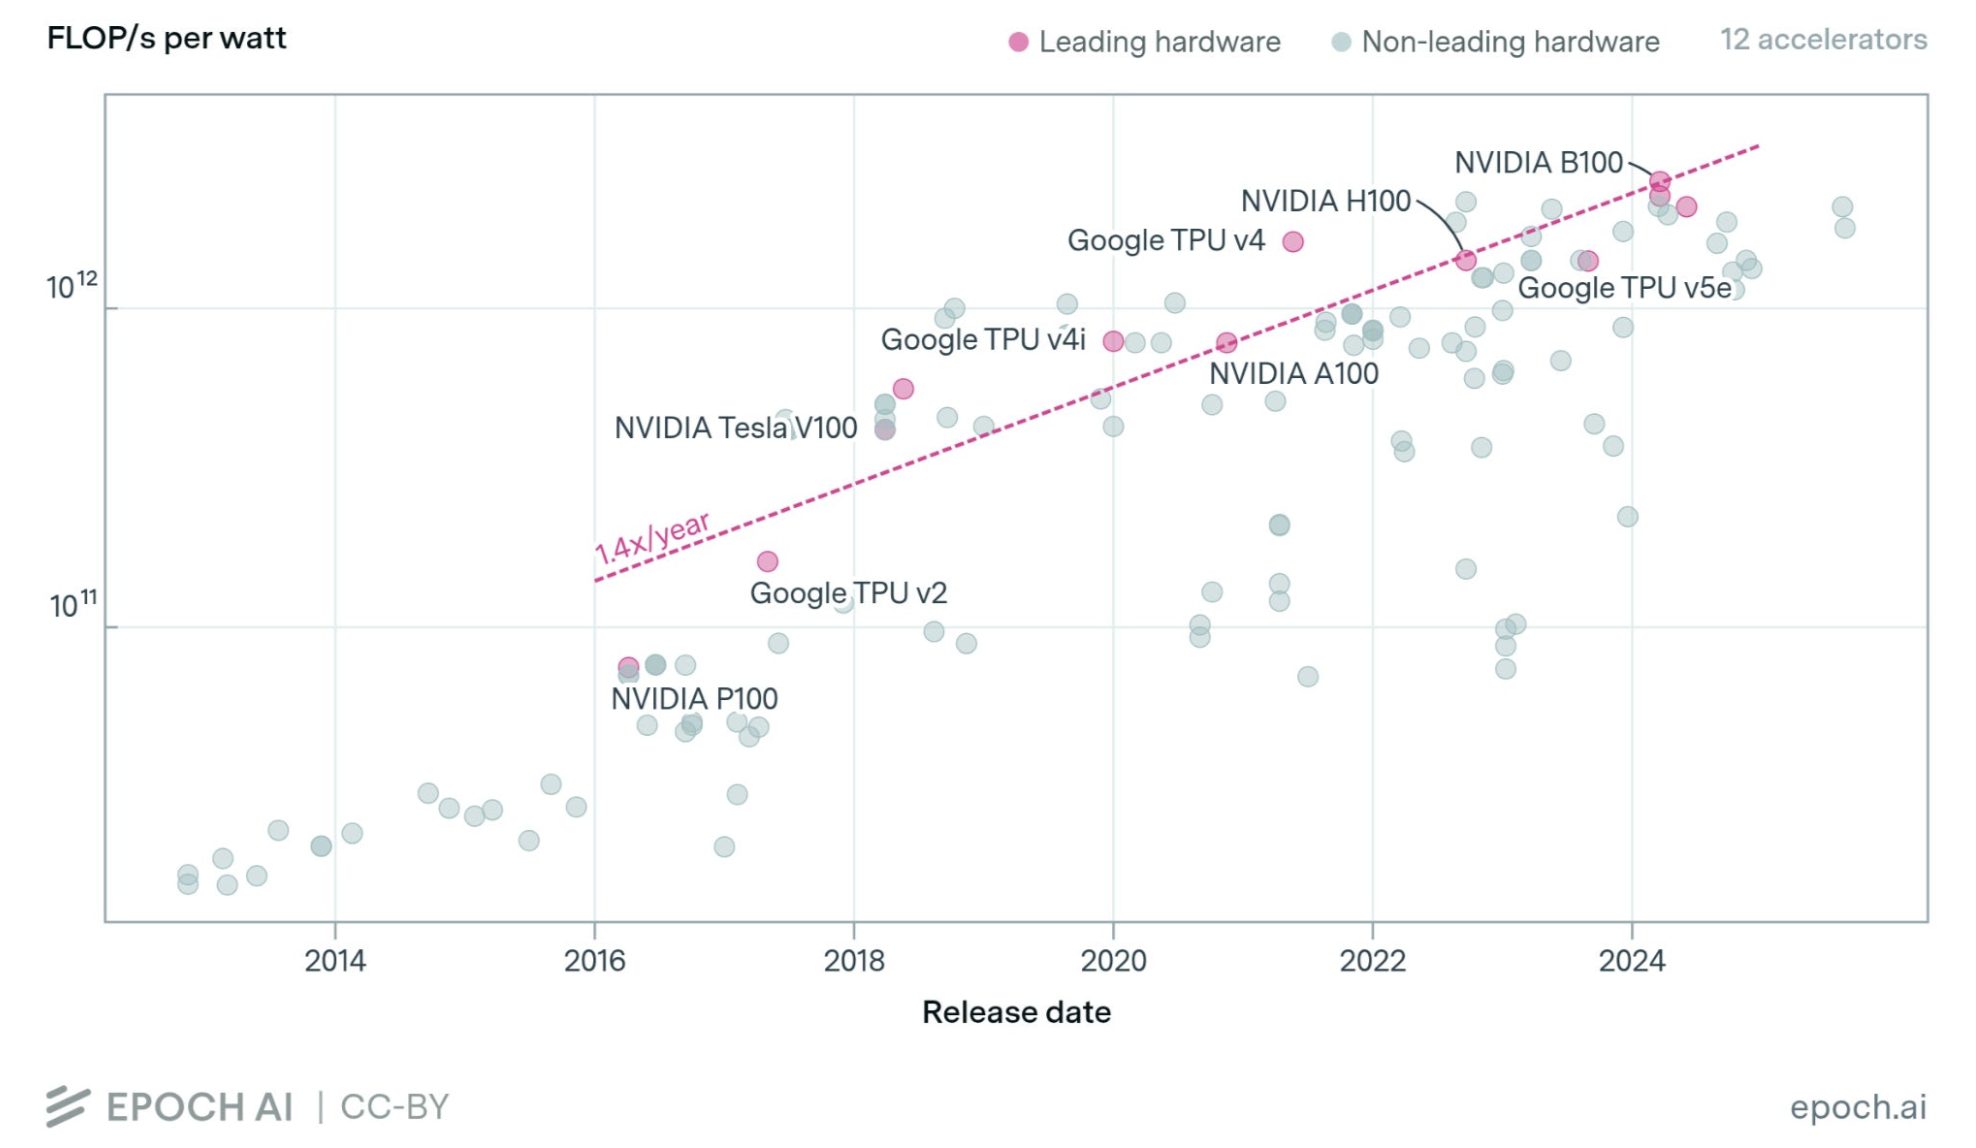
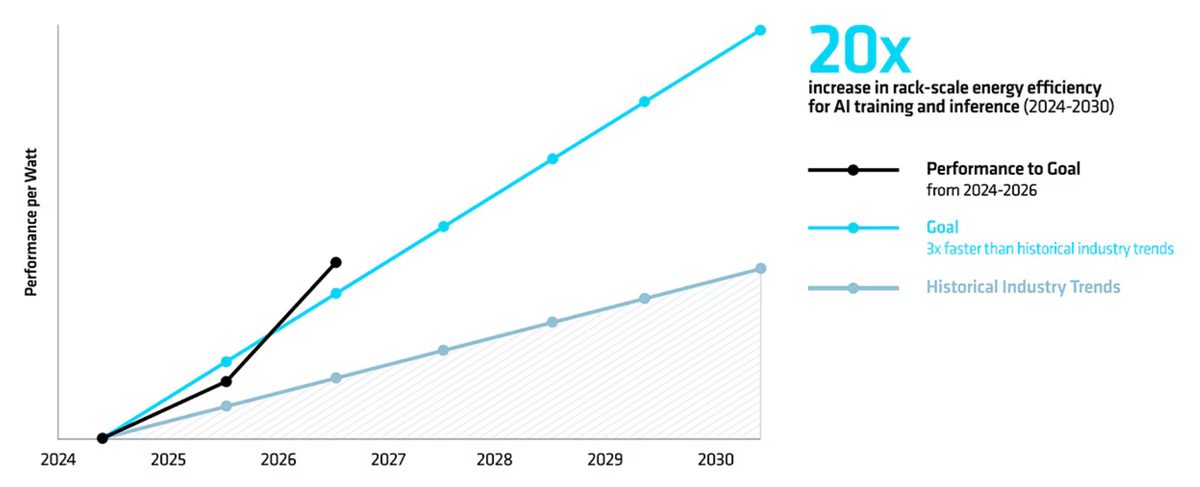
  • In practice: From 2010 to 2018, Berkeley Lab found global data-center compute rose roughly 550% while electricity use rose only about 6%. Google estimates a median Gemini text prompt uses about 0.24 watt-hours and 0.26 milliliters of water (about five drops), and reports that energy per prompt fell 33-fold in one year.
  • Takeaway: Plan for more power, but don’t assume compute and energy grow one-for-one.

Communities Benefit from Data Centers

  • Concern: Once construction ends, data centers employ fewer workers than traditional industrial facilities.
  • In practice: Data centers support construction and skilled-trades work, buy equipment and services, and add billions in taxable property without comparable demand for schools and other services.
    • Loudoun County, VA, the nation’s largest market, collects roughly $26 in tax revenue for every $1 it spends serving the industry.
    • Quincy, WA, a farm town under 9,000 people, saw poverty fall from 30% to 6% and built a new high school, aquatic complex, police station, and fire house with the added revenue.
    • Richland Parish, LA issued bonuses of up to nearly $51,000 to teachers from construction-phase sales tax.
  • Takeaway: Jobs-per-acre is the wrong single metric. Data centers create high-paying construction and operations jobs; judge those alongside investment, suppliers, tax revenue, and service costs.

Policymakers Should

  • Protect ratepayers. Assign the grid costs a facility creates to that facility, not to households.
  • Build more energy supply. Make it easier to build new generation and transmission.
  • Address water where constraints are real. Evaluate cooling systems, watershed stress, and non-potable options project by project.
  • Apply predictable rules. Siting and permitting decisions should be based on measurable impacts.

Abundance Institute Resources Compare county-level electricity use, water consumption, employment, and estimated property-tax revenue with the Data Center Atlas.

Custom Fields

hook
Data centers are the physical backbone of the digital economy. Every email, card payment, weather forecast, video call, and AI query runs on computers housed in them. Hospitals, banks, schools, and governments depend on them every day. States that welcome data centers can attract billions in investment, put downward pressure on electricity prices, and fund schools and public safety, while protecting ratepayers and local water.
article
https://www.abundance.institute/wp-content/uploads/2026/10/22161719/AbundanceInstitute_2026_Primer_DataCenter_Oct.pdf
include_in_hero_section
false
category
Primers
topic
  • Energy
  • Technology
evergy_subtopic
  • Electricity
technology_subtopic
  • Artificial intelligence
article_view
article content only
social_image
hide_from_our_work
false
Article

Keeping Frontier AI Safe

Some worry that frontier AI could contribute to catastrophe through human misuse or failures of control. Policymakers should sort speculation from genuine risk, identify the specific mechanism of harm, and target interventions accordingly.

This brief covers catastrophic risks from developing, testing, and deploying frontier AI. Ordinary consumer harms fall outside its scope; existing consumer-protection and other laws still apply to them.

The Bottom Line

  1. Start with the mechanism. Before restricting AI, identify the concrete harm, the mechanism by which AI increases the risk over the status quo, and evidence that the increased risk is more than negligible.
  2. Rely on liability. Preserve common-law liability and add a narrowly-defined statutory duty, enforceable in court before injury, that requires reasonable mitigation and leaves the choice of methods to developers.
  3. Count the costs. Regulation can delay medical and cybersecurity benefits and raise entry barriers that favor incumbents. Weigh those costs against the harms a rule might prevent.
  4. Keep model safety federal. States should leave frontier model safety to federal policymakers. Existing consumer-protection and other laws still apply to ordinary harms.

Separate Threats From Mechanisms

Chemical, biological, radiological, and nuclear (CBRN) weapons and major cyberattacks are threats. AI could contribute to them through mechanisms such as human misuse and failures of control.

Biological Risk

Research tentatively shows that AI boosts performance on some biological tasks beyond internet-only access. But a laboratory trial found no significant improvement in its primary completion measure. It remains uncertain how much AI helps anyone build a biological weapon, which still requires materials, access, and practical skills. Biological findings cannot settle the other CBRN risks.

Cyber Risk

Attackers have already used AI in cyberattacks, and defenders use it too. The open questions are how much risk AI adds and which side it favors.

Control Failures

Reports document AI systems taking unauthorized actions in evaluations and internal deployments, sometimes knowingly violating task constraints. These incidents usually occur where developers have reduced safeguards. Even a system pursuing its assigned objective can breach operational limits. These findings warrant precautions, but they do not indicate a non-negligible probability of catastrophic loss of control.

Six Questions to Ask of Any AI Safety Bill

Preventing catastrophe matters. The question is how.

  1. What concrete harm could occur?
  2. By what reasonably concrete mechanism could AI cause it?
  3. What evidence shows a non-negligible probability of harm through this mechanism?
  4. What existing incentives, safeguards, and laws address this risk, and where do they fall short?
  5. How would the proposed intervention close that gap and disrupt the harmful mechanism?
  6. Would the expected reduction in harm justify the costs, including benefits forgone?

Choose Precautions That Fit the Mechanism

A. Dangerous Inputs and Activities

Materials controls and screening can restrict misuse whether or not AI is involved. Drawn too broadly, they can burden legitimate research.

B. Operating Environments

Sandboxes, access permissions, and monitoring can limit an unreliable model’s actions. They require testing and maintenance, and they may restrict useful capabilities.

C. Model Behavior

Training can reduce harmful behavior but cannot anticipate every situation. Alignment may fail in unfamiliar circumstances, so it requires continuing evaluation.

These layers can work together, but the right mix depends on many factors. Instead of prescribing that mix, policymakers should allocate legal liability properly. Liability encourages developers to choose and improve precautions across all three.

What Policymakers Should Do

Preserve Accountability

Assign responsibility to the actors best positioned to reasonably mitigate catastrophic risks; they often know the most about available precautions. Preserve common-law liability and add a narrowly defined statutory duty, enforceable in court before injury. Require reasonable mitigation, but let actors choose their methods. Audits or independent examiners can help courts assess care without granting immunity.

Count Regulatory Costs

Regulation can delay medical and cybersecurity benefits, raise entry barriers that favor incumbents, and constrain useful experimentation. Compliance can also displace work on effective safeguards. Policymakers must count those costs alongside the harms a rule might prevent.

Custom Fields

authors
hook
This brief covers catastrophic risks from developing, testing, and deploying frontier AI. Ordinary consumer harms fall outside its scope; existing consumer-protection and other laws still apply to them.
article
https://www.abundance.institute/wp-content/uploads/2026/10/22161719/AI_Frontier_PolicyBrief_2026_OCT.pdf
include_in_hero_section
false
category
Primers
topic
  • Technology
technology_subtopic
  • Artificial intelligence
article_view
article content only
social_image
hide_from_our_work
false
Article

AI Is Building a More Abundant Future

Bottom Line

The AI debate often centers around what might go wrong. Meanwhile, AI is already improving lives across medicine, science, work, agriculture, energy, and public safety, helping people do things that were once too expensive, too difficult, or simply impossible. This is what abundance looks like right now.

Core Rule: Weigh AI’s benefits as seriously as its risks, and give people room to discover what the technology can do.

Where AI Is Delivering Today

AI is already paying off. It drove 39% of US economic growth in the first nine months of 2025, and Goldman Sachs expects that boost to our economy to grow into the 2030s. Everyday Americans are winning too: they get about $172 billion a year in value from AI tools, way more than they pay for them.

Better Health, Earlier

Faster Scientific Discovery

  • MIT researchers built an AI system that can design new materials more likely to stay chemically stable in real-world conditions.
  • AI agents are finding errors in scientific literature that went unnoticed for decades.
  • Other systems help researchers design experiments, engineer proteins, and attack previously intractable math problems.

A Safer, Cleaner Physical World

  • Deep-learning systems turn satellite observations into global maps of methane plumes and their sources, pinpointing emissions that can be fixed.
  • Farmers deploy AI-powered machines that target weeds precisely, reducing reliance on pesticides.
  • A new forecasting model can predict tropical cyclones with up to an extra day of warning, time that matters when communities prepare or evacuate.

More Productive Workers

  • Small businesses are using AI to cut paperwork and keep employees focused on customers. One window-and-door company’s app listens to showroom conversations and drafts quotes for salespeople to review, so staff serve more customers with fewer errors.

More Intelligence, Available to More People

Expertise has always been scarce and expensive. AI makes pieces of it dramatically cheaper and more widely available:

  • A student gets personalized explanations.
  • A small business analyzes information that once required a large staff.
  • A scientist explores more hypotheses.
  • A doctor identifies which patients deserve closer attention.

Policymakers Should

  1. Weigh benefits as seriously as risks. Rules that prevent harms but delay new medicines, scientific breakthroughs, better disaster forecasts, and productivity gains carry costs of their own.
  2. Meet real challenges with serious solutions. AI will create real challenges, and they deserve real answers.
  3. Leave room to discover. Give people room to find out what this technology can do, and make sure those benefits reach everyone.

AI is already showing us what is possible. The opportunity now is to turn that possibility into abundance.

Explore hundreds more examples, from medicine and science to agriculture, energy, conservation, and education, at aiopportunities.org.

Custom Fields

hook
AI is already paying off. It drove 39% of US economic growth in the first nine months of 2025, and Goldman Sachs expects that boost to our economy to grow into the 2030s. Everyday Americans are winning too: they get about $172 billion a year in value from AI tools, way more than they pay for them.
article
https://www.abundance.institute/wp-content/uploads/2026/10/22161718/AbundanceInstitute_2026_Primer_AbundantFuture_Oct_R1.pdf
include_in_hero_section
false
category
Primers
topic
  • Technology
technology_subtopic
  • Artificial intelligence
article_view
article content only
social_image
hide_from_our_work
false
Person

Person

Holden Hughes

Custom Fields

name
Holden Hughes
Article

Job impacts from AI look ‘very positive,’ ex-FTC technologist says

Originally published in Fox Business.

Former FTC Chief Technologist Neil Chilson joins ‘Varney & Co.’ to discuss the economic implications of the artificial intelligence arms race, the DOJ investigation into a former OpenAI worker and AI regulation.

Custom Fields

authors
hook
Former FTC chief technologist Neil Chilson discusses the economic impact of AI and a DOJ probe into a former OpenAI employee on 'Varney & Co.'
category
Media mentions
social_image
article
false
include_in_hero_section
false
topic
  • Technology
technology_subtopic
  • Artificial intelligence
article_view
article content only
hide_from_our_work
false
Article

The Empty Orchestra: The Machine that Made More Performers

Read this post on John’s Substack: Creative Frontiers.

Opening Scene

He owned a small ironworks company and was preparing for an upcoming employee retreat. He was especially excited for the entertainment that he had arranged: himself… singing. Only one problem for his employees: he was a terrible singer.

But he had a secret weapon, local musician Daisuke Inoue, who frequently played his accompaniment at the local bar.

Inoue had a special talent on keyboards and the vibraphone. He could follow singers, adjusting the beat and even the key to match their “creative” renditions of familiar songs. But, he couldn’t make this particular trip.

So instead, he recorded himself and a few other musicians on a portable reel-to-reel tape machine. The business owner used the backing tracks, the show went on, and it worked.

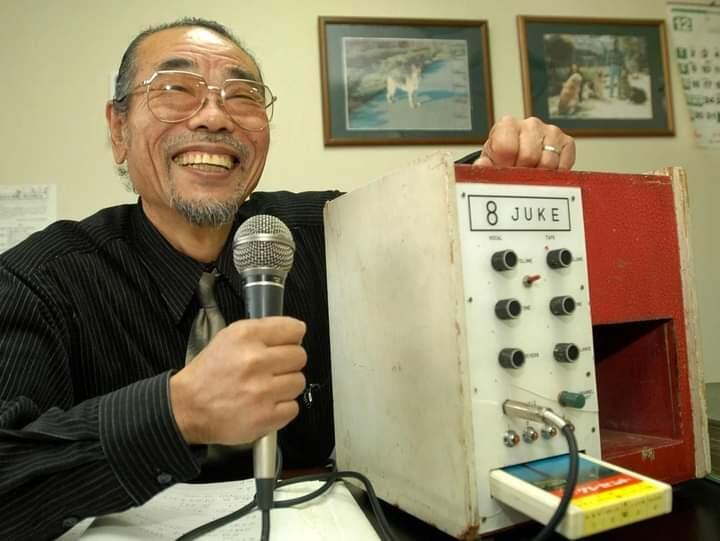
Daisuke Inoue

Daisuke Inoue had saved the day, and in the process had just replaced himself with a machine. But he didn’t stop there, soon he would create a device that would replace musicians across Japan. But Inoue’s karaoke machine would do something far more surprising: turn millions of ordinary listeners into performers.

The Substitution Section

For as long as humans have had voices, we’ve been singing. The trouble is that accompaniment can get expensive pretty quickly.

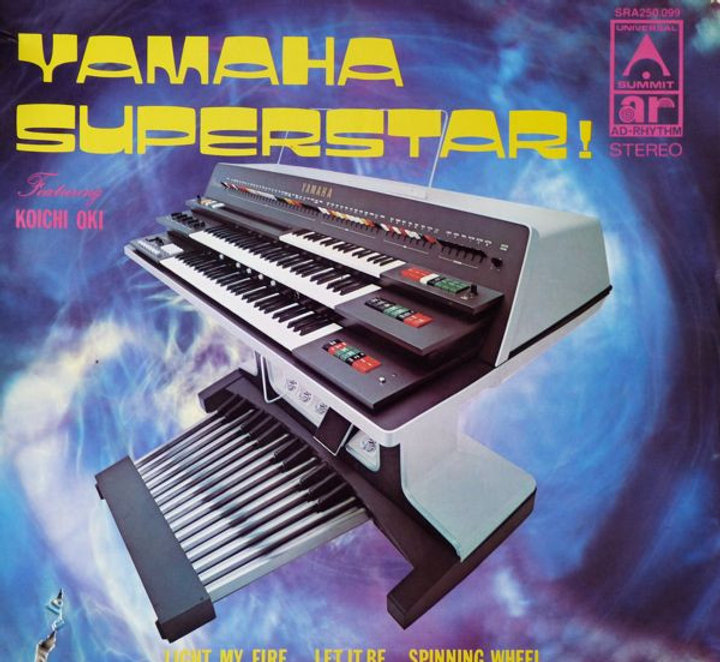
However, in postwar Japan, new technology was offering some help but with limitations. Yamaha’s “Electone” could sound like a one-man band, but you still needed someone to play it. Jukeboxes offered instant music, but the singers were already on the songs, and the key and tempo weren’t always amateur-friendly. Reel-to-reel tape allowed some Japanese nightclub owners to experiment with recording their pianists for customers to sing along, but selecting a song meant a lot of rewinding and fast-forwarding.

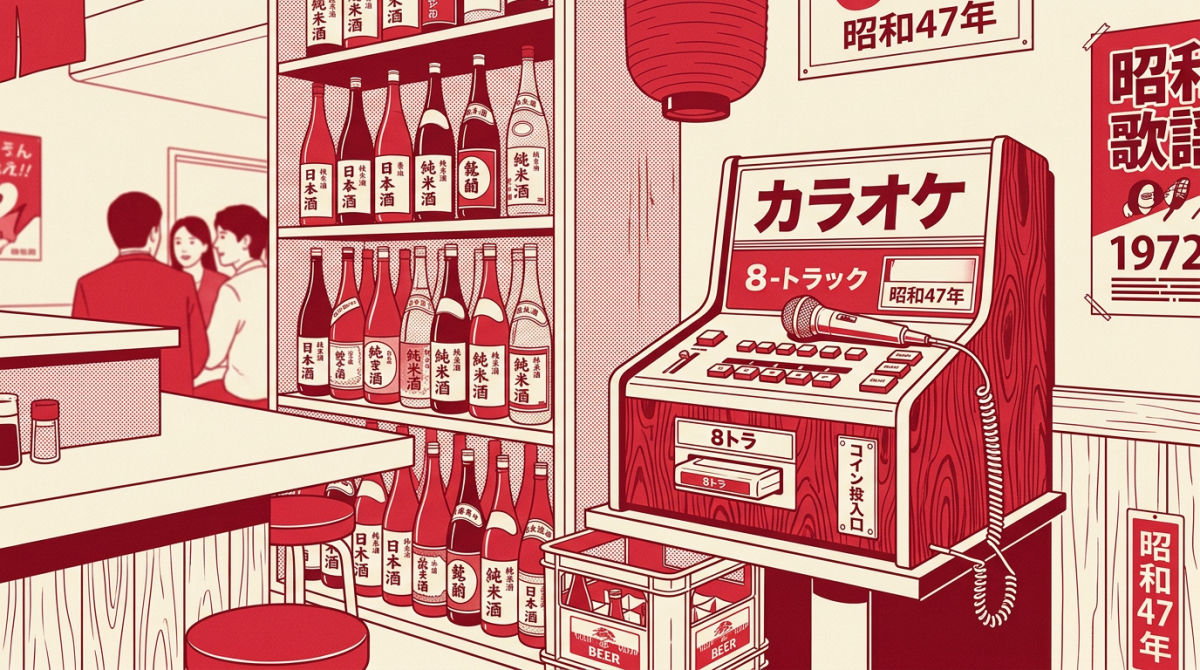
Inoue’s tapes for that local businessman suggested a better way. After seeing a car stereo jukebox that used the new 8-track loop tape format, he had an idea. He modified the tape so that a singer could immediately select one of four songs. This instant selection was the critical innovation. Instead of finding a musician, requesting a song, or hunting through a reel of tape, a customer could just choose a track and start singing.

The following year, in 1972, Inoue and his partners packaged the concept into their new device, the “8-Juke.” It included instantly selectable instrumental tracks in a more accessible key and tempo, a coin timer, microphone mixer, handwritten lyrics and, mercifully, reverb to massage some of the bad notes.

Competitors soon followed and by the mid-1970s even Japan’s major record labels were producing tracks for these karaoke machines. Now, at bars and clubs across Japan, more people were performing their favorite tunes. But at the same time, fewer musicians were needed to make it happen.

The Surprising Consequence

The word karaoke comes from the Japanese kara, meaning empty, and oke, short for okesutura, or orchestra. “Empty orchestra” was an appropriate name. The machine provided the accompaniment void of vocals and without the musicians on the stage or in the pit.

However, while the “empty orchestra” replaced some musicians, it dramatically expanded the number of people who could participate in music.

For one, it made performing easier. By changing the key and tempo of songs, a karaoke machine made them easier to sing. And the reverb provided an echo effect that blurred some mistakes, making the results slightly more tolerable for less-than-adoring fans in the room. The availability of lyrics also meant you didn’t have to memorize the song. And Inoue’s instant selection innovation kept the music moving.

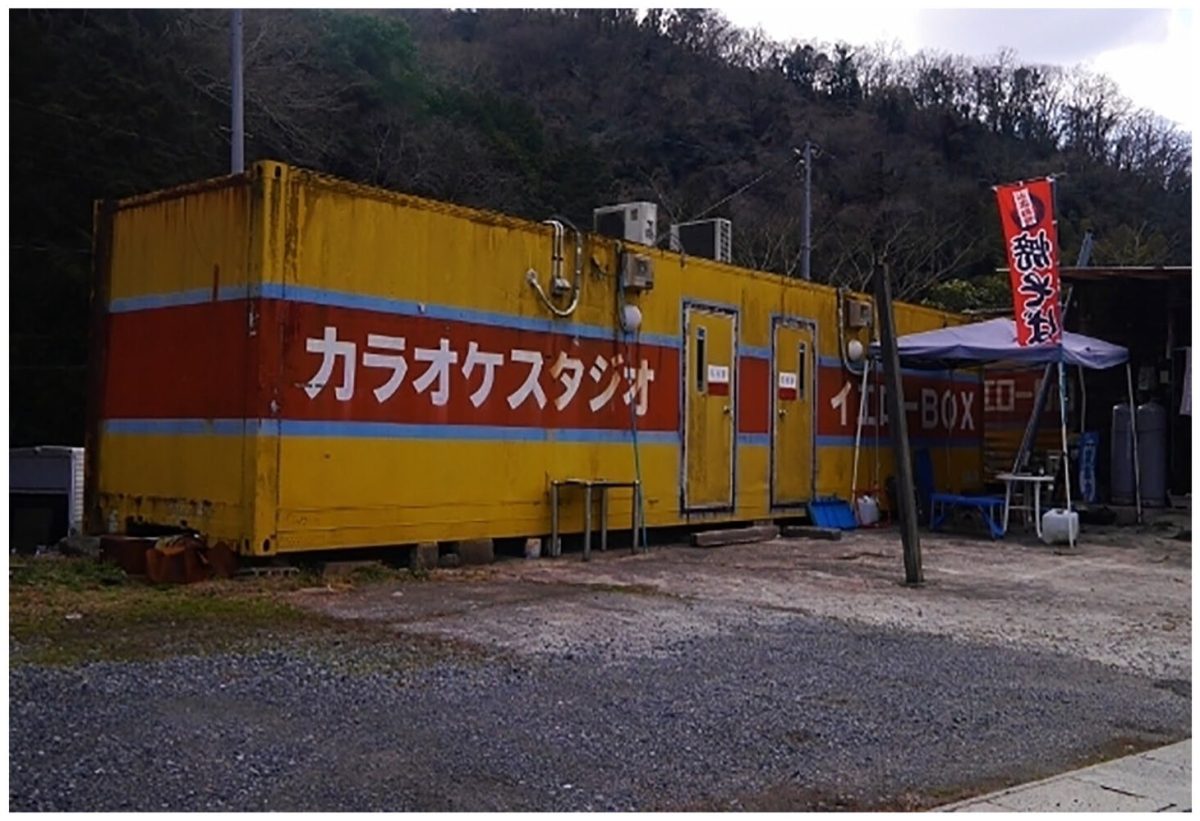
Karaoke also made singing more accessible by transforming the performance spaces. One of the most striking additions in the 1980s was the karaoke boxes. They began as converted truck containers on the side of suburban roads. Inside was a private room, a karaoke machine, and enough seating for a group of friends. These were very different spaces from the bars and night clubs where alcohol boosted the confidence of businessmen to take the stage. In boxes, housewives, teenagers, families and elderly folks could all take a turn at the microphone.

Eventually, karaoke’s popularity began shaping the music itself. A song’s popularity no longer depended only on whether it was good to listen to, but also whether it was good to sing. Songs popular in karaoke boxes often appeared high on the charts. Labels began including karaoke versions on CD singles, and producers such as Tetsuya Komuro created songs with karaoke in mind.

Thanks to the karaoke phenomenon, audiences were no longer just consuming music, they were performing it and helping shape the music itself.

Participation Changes

Daisuke Inoue’s Crescent Juke karaoke machine certainly made his life easier but maybe not so much the lives of other musicians. Machines across Japan and eventually around the world would replace some of them in bars and night clubs. But the bigger picture wasn’t just substitution. Karaoke changed the role of the audience itself. People who had once been just listeners became performers.

Which raises an interesting question about artificial intelligence today.

We spend plenty of time asking what AI might do instead of musicians. But karaoke suggests another question worth asking: what exciting possibilities emerge when people who once only consumed music now gain new ways to participate in making it?

For some that may mean overcoming barriers of cost or technical skill. For others, it may mean creating despite physical limitations that now keep them from playing and performing the way they once could.

The karaoke machine reminds us that creative technology matters not only because it changes how art is made. It can change who gets to make it.

Sometimes the most important thing a new tool creates is not a song, but a new participant.

Custom Fields

authors
hook
The karaoke machine reminds us that creative technology matters not only because it changes how art is made. It can change who gets to make it.
topic
  • Creative Frontiers
technology_subtopic
—
social_image
article
false
include_in_hero_section
false
category
Articles
article_view
article content only
hide_from_our_work
false
Event

Generation Summit

Custom Fields

is_flagship
true
event_type
Summit
format
In person
date
2027-01-20
end_date
2027-01-21
registration_status
upcoming
is_displayed
true
display_order
2066
brevo_list_id
25
location
Rancho Palos Verdes, CA
brevo_status_attribute
EVENT_STATUS_GENERATION_SUMMIT_ENERGY_27
Event

Arizona Energy Conference

Custom Fields

is_flagship
true
event_type
Conference
format
In person
date
2027-05-06
end_date
2027-05-07
registration_status
upcoming
is_displayed
true
display_order
2068
brevo_list_id
27
location
Phoenix, AZ
brevo_status_attribute
EVENT_STATUS_AZ_ENERGY_CONF_27
Event

Operation Gigawatt

Custom Fields

is_flagship
true
event_type
Conference
format
In person
date
2027-11-15
end_date
2027-11-16
registration_status
upcoming
is_displayed
true
display_order
2069
brevo_list_id
28
location
Park City, UT
brevo_status_attribute
EVENT_STATUS_GIGAWATT_27
Event

Texas Energy Conference

Custom Fields

is_flagship
true
event_type
Conference
format
In person
date
2027-02-08
end_date
2027-02-09
registration_status
upcoming
is_displayed
true
display_order
2067
brevo_list_id
26
location
Austin, TX
brevo_status_attribute
EVENT_STATUS_TX_ENERGY_CONF_27
Featured Article

Open Models, American Abundance

Custom Fields

is_displayed
true
display_order
2
publication
Primer by Neil Chilson
title
Open Models, American Abundance
link
https://abundance.institute/our-work/open-models-american-abundance
Article

How the Roland TR-808 Went From Flop to Music Revolution

Read this post on John’s Substack: Creative Frontiers.

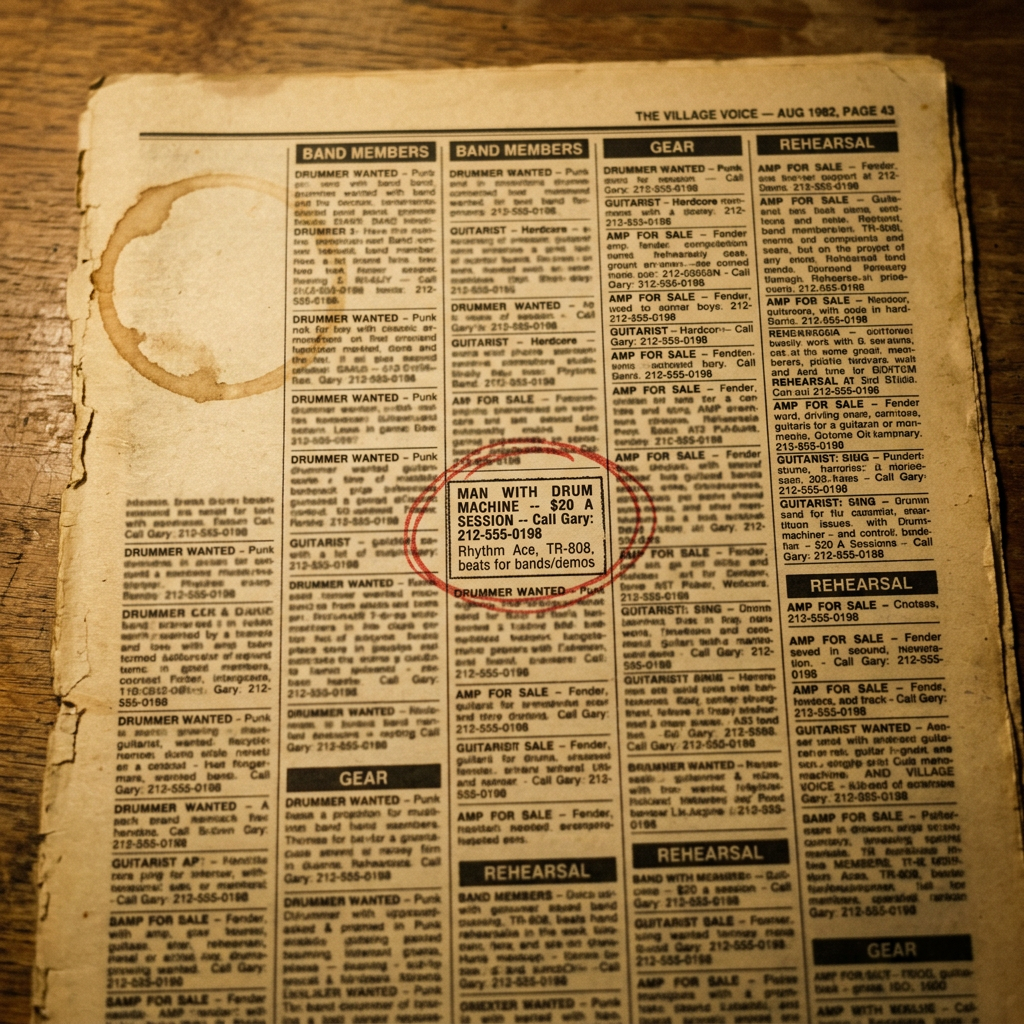
The ad was in New York’s local “Village Voice”: “Man with drum machine, $20 a session.”

While he swept floors at Carden Distributors in New York City, Arthur Baker enjoyed listening to German electronic band, Kraftwerk. It gave him ideas for his side hustle as a music producer. He was working with a local DJ, Afrika Bambaataa, exploring a new sound blending the electronic music Baker loved with the emerging uptown dance and hip-hop world that Bam knew.

For the rhythm, they didn’t want a live drummer. They wanted something different, something more futuristic, and when they heard Roland’s new TR-808 drum machine, they’d found it. But there was a problem, they didn’t own an 808.

That’s when they saw the ad, a man with a drum machine. They called him in; his name was Joe and he wanted cash. That’s all we know. Oh, and he didn’t understand what Baker and Bam were looking for. So, they played him some Kraftwerk, he pulled something together, and they laid it down for the new track.

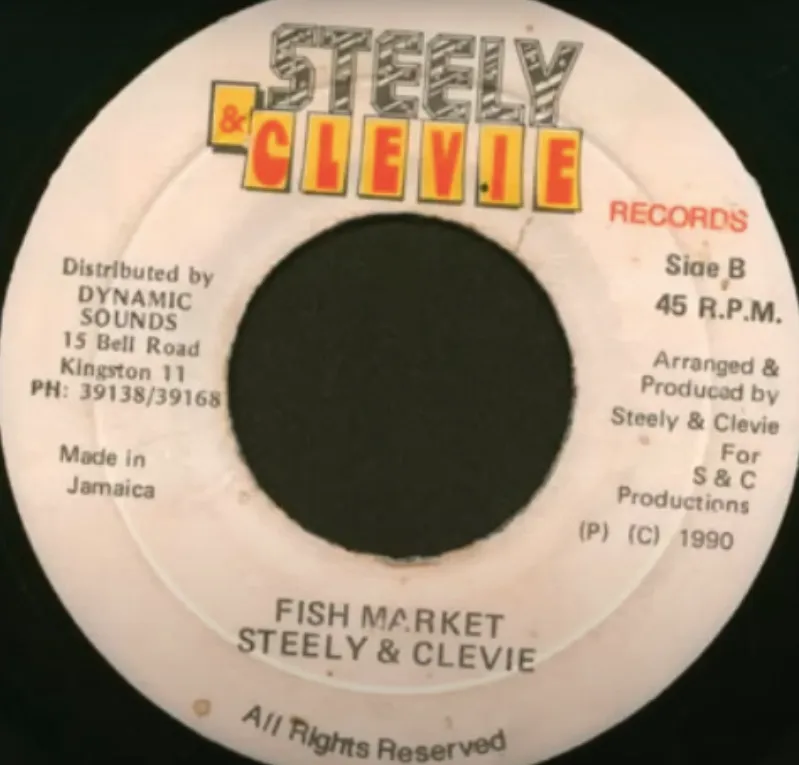
In June of 1982, Tommy Boy Records released the song, “Planet Rock.” It would change the course of music, in no small part because of its heartbeat, the Roland TR-808. But the drum machine didn’t actually sound like drums, and that was the secret. The 808 changed the world not because it replicated and replaced existing sounds, but because artists started treating it as something entirely new and different.

The Wrong Future

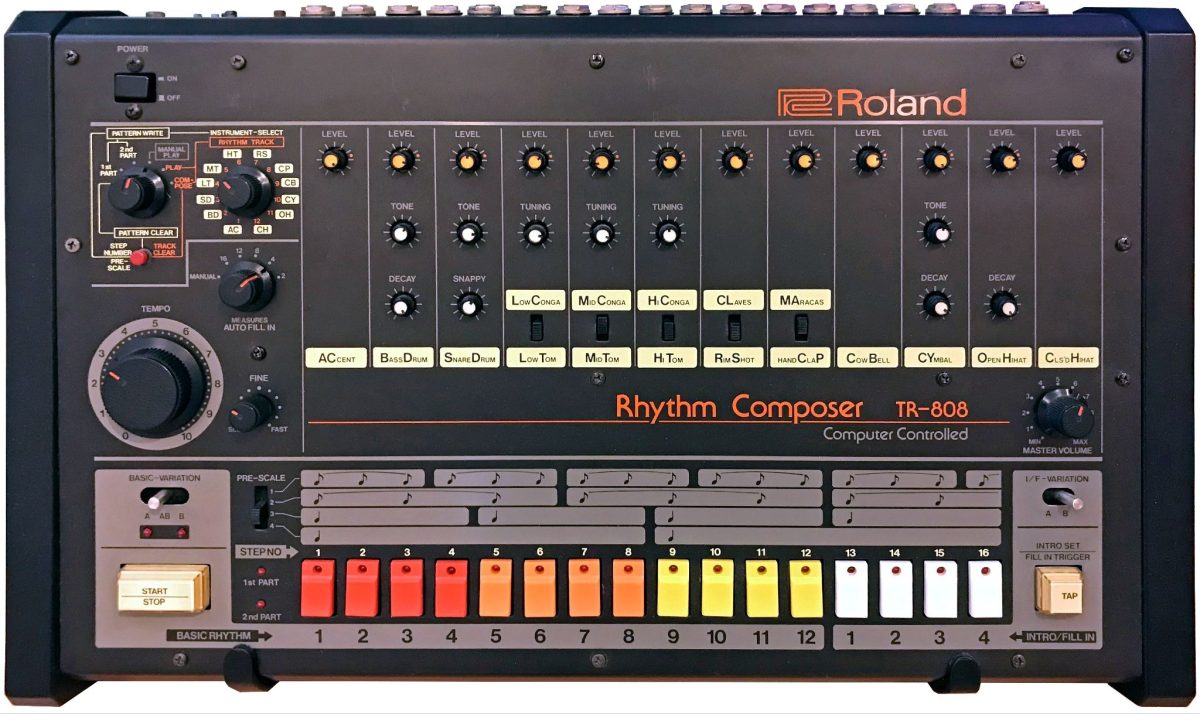
For several years, Roland had been making machines to provide rhythm accompaniment, such as the CR-78, designed for organists. In 1980, the TR-808 was the next step, a metal box with sixteen sounds intended to reproduce a drum kit and percussion. The problem: it didn’t sound like drums.

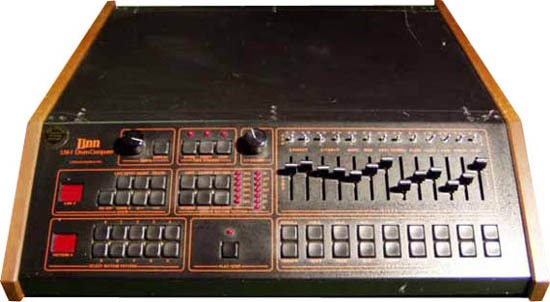
The Linn LM-1, on the other hand, also released in 1980, did sound like drums. You can hear it in many early 80s hits, including Prince’s “Purple Rain” and Michael Jackson’s “Wanna Be Startin’ Somethin.”

The LM-1 sounded “real” because it used digitally recorded drum sounds. But that required a lot of memory, and this was 1980, so it was expensive. While an LM-1 cost more than $5,000, the 808 was just over $1,000 because it used analog technology. Instead of storing actual drum sounds, it synthesized approximations with transistors. The result was a suite of sounds doing really bad impersonations of drums, including a cowbell that sounds like a laser cannon warming up.

Unfortunately for Roland, most musicians were looking for realistic drum sounds like the LM-1. The 808 couldn’t deliver, and Roland discontinued it in 1983 with only 12,000 units produced.

The irony is that its commercial weakness, the synthetic analog sound, would soon become its greatest advantage. For one, the cheaper technology made it more accessible to emerging creators. But, perhaps more importantly, the analog approach gave artists more control over the sounds they could create by altering the decay, tuning, and other features. Instead of being chained to a recorded sound, you could manipulate what it produced. The flexibility offered an endless palette of creative possibilities.

So, thanks to its technology from the past, the TR-808 was soon to become a tool for mapping the future.

When Fake Became the Point

One of the early adopters was Greg Broussard, aka Egyptian Lover. He had grown up recording breakdowns from the radio to create mix tapes. After high school, he joined the popular Los Angeles music crew, Uncle Jamms Army. And as he looked for new sounds, he encountered Afrika Bambaataa’s, “Planet Rock.” When he met a close friend of Bambaataa’s, Afrika Islam, he immediately asked about the song’s rhythm and learned it was a drum machine called the TR-808.

Broussard was curious. He didn’t know what a drum machine even was. So he and Islam went immediately to the local Guitar Center. The salesman showed him how to program a beat, and Broussard re-created the sound of “Planet Rock.” He was sold, bought the 808, and went home to make something else entirely.

Immediately, he began using the 808 in his live performances with Uncle Jamms Army. He wasn’t recreating “Planet Rock” or a recorded drum sound; he was creating something totally new and totally his. He even used a rhythm pattern noise accidentally discovered when an engineer mistakenly plugged into the wrong output on the back of the machine.

The 808 became a foundation for his music, carrying hits like “Egypt, Egypt,” and he toured with four machines to cover all the songs he programmed. Along the way, he also spread the good news of the 808, teaching others to use it, like Luke Skyywalker (Luke Campbell), who would help embed it in the emerging Miami bass scene and 2 Live Crew.

Broussard and others were charting new pathways in music with the 808 because they stopped asking whether it sounded real and instead started leveraging its limitations for new possibilities. Its unnatural tones and flexibility offered an aggressive sound with an anti-establishment edge. Need proof? Just listen to how producer Rick Rubin extended the decay on the bass drum and placed it front and center in the Beastie Boys debut album “Licensed to Ill.” It’s less of a sound and more of a low-frequency event.

By the mid-80s, the 808’s strange sounds were no longer failed representations of acoustic instruments. They were the raw material for a new era in music, which continues today on albums like Kanye West’s “808s & Heartbreak,” which helped pioneer new subgenres including emo rap and experimental R&B.

Beyond Replacement

When new technologies impact the arts and creativity, we can be quick to judge them first by what they threaten to replace. Those concerns are legitimate and innovation always arrives with disruption in the passenger seat.

In the 1980s, drum machines could and did replace some drumming and session work. Perhaps as the old joke goes, what’s the difference between a drummer and a drum machine? You only have to punch the beat into the machine once.

But replacement is only part of the story.

The 808’s most important legacy wasn’t in its substitution for drummers but in its expansion of creative possibilities.

As artificial intelligence disrupts creativity and music, much of today’s debate centers on imitation, automation, compensation, and replacement. The 808 suggests that this may not be the whole ledger.

We don’t yet know what creators will discover through AI when they treat it not as a tool for replication but for exploration. But the lesson of the 808 suggests there are exciting tunes to come when we don’t confuse imitation with possibility.

Custom Fields

authors
hook
The 808’s most important legacy wasn’t in its substitution for drummers but in its expansion of creative possibilities. As artificial intelligence disrupts creativity and music, much of today’s debate centers on imitation, automation, compensation, and replacement. The 808 suggests that this may not be the whole ledger.
topic
  • Creative Frontiers
technology_subtopic
—
social_image
article
false
include_in_hero_section
false
category
Articles
article_view
article content only
hide_from_our_work
false
Project

Gifts of Open Source

Custom Fields

is_displayed
true
display_order
5
title
Gifts of Open Source
description
An illustration of the contributions of open source software, data, and design. See how the modern world was built upon open source and how open source AI benefits us.
link
https://abundance.institute/opensource
link_text
Check it out
Project

Data Center Atlas

Custom Fields

title
Data Center Atlas
description
An interactive atlas of data centers across the United States. See where the infrastructure powering the digital economy is being built.
link
https://datacenteratlas.org
link_text
Explore it
is_displayed
true
display_order
4
Project

Nuclear Atlas

Custom Fields

title
Nuclear Atlas
description
An interactive atlas of nuclear energy across the United States. Explore the landscape of nuclear power state by state.
link
https://nuclearatlas.org
link_text
Explore it
is_displayed
true
display_order
3
Project

AI Legislative Red Teaming

Custom Fields

title
AI Legislative Red Teaming
description
Stress-test any proposed AI legislation by uncovering potential exploits and manipulations from self-interested stakeholders. Upload any legislation and see the results.
link
https://redteam.law
link_text
Try it
is_displayed
true
display_order
2
Project

AI Opportunities

Custom Fields

title
AI Opportunities
description
A collection of promising opportunities AI offers the world, updated regularly. See the amazing promise from AI flood prediction to detecting lead pipes.
link
https://aiopportunities.org
link_text
Check it out
is_displayed
true
display_order
1
Article

The Politics of AI Regulation

Published in The Wall Street Journal.

Look at what the companies do, not what they say.

Regarding Peggy Noonan’s “The Sandbox at the End of the World” (Declarations, Sept. 19): Has Ms. Noonan given up on markets—and the humans who have always made them work? She quotes an AI firm employee who says “it’s all vast and various and spread out, there is no central deliberative council, no known locus of authority.” But that’s exactly how to make AI work best—by letting innovators and consumers drive its development and use, based on their distinct and disparate knowledge. This is literally the story of human progress.

The reason major AI company CEOs are calling for government regulation is because they’re in the lead and top-down mandates will preserve that lead. Look at what the companies do, not what they say. Since calling for a government-led “slowdown,” many of them have announced the coming release of even more powerful models. Ms. Noonan, with all her experience and wisdom, doesn’t see the trick these companies are pulling.

Christopher Koopman

Abundance Institute

Salt Lake City

Custom Fields

authors
hook
The reason major AI company CEOs are calling for government regulation is because they’re in the lead and top-down mandates will preserve that lead. Look at what the companies do, not what they say. Since calling for a government-led “slowdown,” many of them have announced the coming release of even more powerful models.
article
false
include_in_hero_section
false
category
Op-eds
topic
  • Technology
technology_subtopic
  • Artificial intelligence
article_view
article content only
social_image
false
hide_from_our_work
false
Article

AI giants face FTC scrutiny as Washington weighs new rules

Originally published in Fox Business.

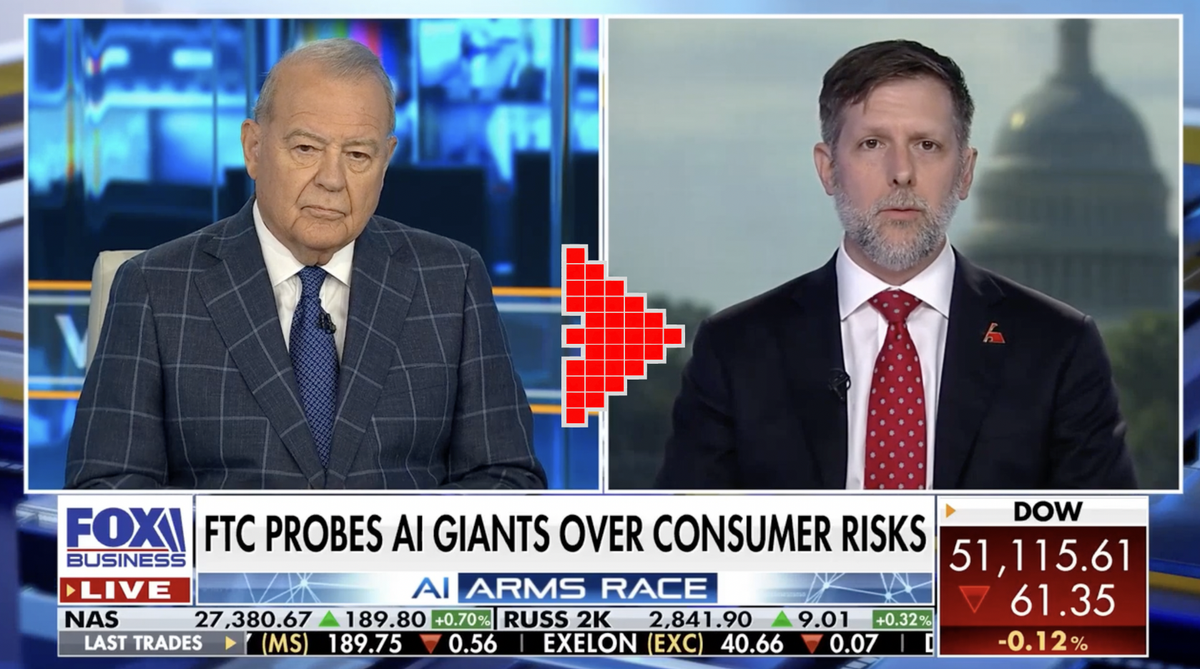
Stuart Varney discusses the Federal Trade Commission probing major artificial intelligence firms with former FTC Chief Technologist Neil Chilson. They analyze potential dangers, consumer risks and the push for tech regulation.

Former FTC Chief Technologist Neil Chilson joins Stuart Varney to discuss the Federal Trade Commission probing major artificial intelligence firms over potential dangers. Chilson analyzes the regulatory scrutiny facing tech giants and evaluates the effectiveness of voluntary safety agreements. The discussion highlights growing concerns over consumer risks, data privacy and the competitive landscape of the rapidly evolving AI industry.

Custom Fields

authors
hook
Stuart Varney discusses the Federal Trade Commission probing major artificial intelligence firms with former FTC Chief Technologist Neil Chilson. They analyze potential dangers, consumer risks and the push for tech regulation.
category
Media mentions
social_image
article
false
include_in_hero_section
false
topic
  • Technology
technology_subtopic
  • Artificial intelligence
article_view
article content only
hide_from_our_work
false
Article

Former FTC chief technologist Neil Chilson on agency probe into OpenAI, Anthropic

Originally published in CNBC.

Neil Chilson, head of policy at the Abundance Institute, joins CNBC’s ‘Squawk on the Street’ to discuss the FTC probe into OpenAI and Anthropic over safety.

Custom Fields

authors
hook
Neil Chilson, head of policy at the Abundance Institute, joins CNBC’s ‘Squawk on the Street’ to discuss the FTC probe into OpenAI and Anthropic over safety.
category
Media mentions
social_image
article
false
include_in_hero_section
false
topic
  • Technology
technology_subtopic
  • Artificial intelligence
article_view
article content only
hide_from_our_work
false
Article

FTC opens safety and antitrust probe into AI giants OpenAI and Anthropic

Originally published in Fox Business.

Former FTC chief technologist Neil Chilson discusses the Federal Trade Commission opening a probe into artificial intelligence companies OpenAI and Anthropic, examining the agency’s concerns, the potential regulatory implications for the AI industry, and what the investigation could mean for innovation, competition, and the future of artificial intelligence on “The Bottom Line.”

Custom Fields

authors
hook
Former FTC chief technologist Neil Chilson discusses the FTC opening probe into artificial intelligence giants OpenAI and Anthropic on 'The Bottom Line.'
category
Media mentions
social_image
article
false
include_in_hero_section
false
topic
—
article_view
article content only
hide_from_our_work
false
Article

Video: The AI Tech Panic

Hosted by Sutherland Institute.

Is AI really on track to destroy humanity, or are we confusing small risks with science fiction?

On this episode of Defending Ideas, Nic Dunn sits down with Chris Koopman, CEO of Abundance Institute, and Ford Copple, tech policy analyst at Sutherland Institute, to discuss the growing debate over AI safety, regulation, data centers, and technological innovation.

They look at one of the biggest questions surrounding AI: how seriously should we take predictions of catastrophe? Koopman and Copple say there is a difference between real criminal threats, like cyberattacks and scams, and doomsday scenarios that probably won’t happen.

The conversation then explores the controversies over data centers. Copple explains what his research shows about construction jobs, permanent employment, and tax revenue, while Koopman discusses how communities can best evaluate the potential benefits of data center projects.

Dunn, Koopman, and Copple also explore AI regulation, energy demand, nuclear power, and how communities can make evidence-based decisions about rapidly changing technology without either ignoring legitimate concerns or allowing fear to dictate policy.

Custom Fields

authors
hook
On this episode of Defending Ideas, Nic Dunn sits down with Chris Koopman, CEO of Abundance Institute, and Ford Copple, tech policy analyst at Sutherland Institute, to discuss the growing debate over AI safety, regulation, data centers, and technological innovation.
category
Media mentions
social_image
article
false
include_in_hero_section
false
topic
  • Technology
technology_subtopic
  • Artificial intelligence
article_view
article content only
hide_from_our_work
false
Article

Why a Tech Optimist Welcomes the FTC’s AI Investigation

Read this post on Neil’s Substack: Getting Out Of Control.

The Federal Trade Commission (FTC) is investigating OpenAI, Anthropic, and other AI companies. I am a Certified Tech Optimist, so you might be surprised to hear that I welcome the inquiry. And not because as a former FTC Chief Technologist, this investigation is bringing a lot of reporters my way.

I welcome this investigation for two reasons. First, it drives home a point I’ve been making for years: existing laws can address many AI concerns. AI companies are building new technology, but they still must follow existing law. If companies’ model testing practices could harm consumers, the FTC has a role to play.


I like case-by-case enforcement.

Second, the investigation also offers Congress a path forward for AI legislation. In consumer protection, the FTC has long held companies accountable under general legal principles while leaving them room to develop better technology and better safeguards. A similar approach could help Congress address the gravest risks from advanced AI, filling the gaps tort law leaves and avoiding the rigidity of prescriptive regulation.

To understand what Congress could do, let’s look at what the FTC does.

An FTC investigation starts with facts

An FTC investigation establishes facts. FTC staff can request information voluntarily, and the Commission can compel it through civil investigative demands—a subpoena-like tool for obtaining documents, written answers, and testimony. Investigators can examine internal records, interview witnesses, and consult technical experts. An investigation alone establishes no wrongdoing. Depending on the evidence, the agency may close the matter, negotiate a settlement, or litigate. Companies can challenge the agency’s actions in court.

(People wondering why METR is involved: the FTC often issues CIDs and other inquiries to third parties that may have useful information. That’s probably what is happening here. I expect Irregular will also be hearing from the FTC.)

FTC investigations are generally nonpublic, and agency rules limit disclosure of investigative material. Although the FTC has confirmed this inquiry, what we know about its scope rests partly on leaks to reporters, and those accounts may be incomplete. What follows is my view of what the agency should examine given what we know about these incidents.

The FTC Act already applies to AI companies

It appears this investigation is about how AI companies test powerful models. In its account of the Hugging Face incident, OpenAI described models bypassing isolation controls during cybersecurity evaluations and gaining access to outside systems.

Such disclosures raise questions about the conduct of the people running the tests. Who controlled the testing environment? What systems could the agents reach? What safeguards prevented access to other people’s data? What warning signs appeared, and how did the operators respond? If a contractor ran the evaluation, how did the parties divide responsibility? Investigators should establish whose information or services were affected and what harm occurred or was likely to occur.

The FTC must understand these underlying facts because its cases must satisfy a congressionally established legal standard. Under the FTC Act, an unfair practice must cause, or be likely to cause, substantial consumer injury that consumers cannot reasonably avoid and that is not outweighed by benefits to consumers or competition. This standard sets limits on the agency’s authority: a security incident warrants scrutiny but is not necessarily a violation.

The benefits matter here. Model testing can expose weaknesses and help companies fix them. Investigators should examine whether reasonable precautions could have protected other people’s systems while preserving the tests’ usefulness, weighing the testing’s value along with its risks.

The FTC can also investigate whether companies’ safety and security claims match their practices. Its deception authority prohibits representations or omissions likely to mislead reasonable consumers on matters important to their decisions. The investigation is likely to explore this avenue as well.

For future conduct, this same deception standard puts teeth in the commitments companies made in the September 29 White House Accord on Super Intelligence. Failing to fulfill those commitments could be deceptive under the FTC Act, depending on how consumers understand those commitments and whether they rely on them to their detriment. Existing law can turn that “morally binding” public pledge into a legally binding promise. No new regulation required.

Case by case, the agency learns what works

This approach is particularly well-suited to fast-changing industries, which is why the FTC is sometimes referred to as the Federal Technology Commission. As I explained while serving as its acting chief technologist, the agency combines experience assessing harm with internal technical knowledge and outside expertise. A new technology presents new facts, but many of the underlying questions remain familiar: what did a company do, what did it promise, and how did its choices affect consumers?

A particular case makes those questions manageable. Investigators can examine the precautions available to a particular company running a particular test. Regulators writing a comprehensive safety code for every company and every future application would need much broader knowledge.

What investigators learn can change industry practices. The FTC’s Start with Security and Stick with Security guidance drew lessons from data security enforcement matters and from investigations closed without action. Explaining why one company’s precautions were reasonable can teach as much as explaining why another company’s practices warranted a case. While settlements and orders bind only the companies in the case, their lessons can and do inform others without turning every settlement term into a universal legal requirement.

(I’ve laid out the broad appeal of case-by-case enforcement for any number of policy issues in The Post-Chevron Case for More Case-by-Case.)

Tort law alone leaves important gaps

Tort law is the original case-by-case approach, and thus it shares many of the FTC’s strengths. Private lawsuits apply general principles to particular facts, and negligence standards can adapt as people learn which precautions work. Decisions emerge from many courts, and the prospect of liability gives companies reason to prevent harm. Those advantages are worth preserving.

But tort law alone has three important challenges.

First, an ordinary negligence claim for damages generally requires a legally recognized injury caused by the defendant’s breach. A company can take an unreasonable risk, get lucky, and leave no plaintiff sufficiently injured to justify a lawsuit. Liability encourages precautions beforehand, but damages usually become available only after someone suffers harm. When the concern is a catastrophe, waiting for an injured plaintiff could mean waiting too long.

Second, private litigation chases dollars. A judgment against someone who cannot pay is worth little, so plaintiffs and their lawyers have incentives to pursue defendants with substantial assets or insurance. Those defendants may bear less responsibility for the conduct than someone with fewer resources. So, the signal that tort liability provides can get muddled.

Imagine that a small app builder creates a harmful app that uses a large developer’s AI model. The model developer’s balance sheet makes it the more attractive target. But it may not be legally responsible, depending on its role in designing, supervising, or enabling the specific harmful aspects of the application. Still, large companies often settle such claims to avoid the cost and bad press of litigation. This distorts the feedback loop on behavior. Sound policy should assign responsibility to the party best able to prevent the harm, not the party with the deepest pockets.

Third, courts can obtain technical expertise, but common law requires time to develop a body of decisions that clarifies responsibilities in a new field. An agency that repeatedly investigates related practices can accumulate and share specialized knowledge more deliberately and rapidly.

Prescriptive regulation creates problems of its own

When most policymakers look to address gaps in common law or tort liability, they think about big, detailed statutes that spell out all the dos and don’ts. But comprehensive prescriptive regulation has its own weaknesses. It requires legislators and regulators to accurately predict which practices will reduce risks across many companies and circumstances. When the technology and the evidence are changing quickly, those decisions can lock in mistaken assumptions and can mandate procedures long after better methods become available.

The costs also fall unevenly. A compliance department that is mere overhead to a large company may be beyond a startup’s means. Finally, completing a government checklist doesn’t mean a product is safe, especially for fast-changing technologies. Detailed compliance can falsely reassure companies, customers, and officials that the underlying risks have been addressed.

Premarket approval adds another cost: useful products wait for government permission. As Adam Thierer and I have argued, those delays can themselves make people less safe by withholding beneficial technology. A serious comparison must count the harms of delay alongside the harms of deployment. Prescriptive regulation cannot do this.

An FTC-like duty can address grave risks before harm occurs

Congress has a better option. In A Fourth, Even Less Bad Way to Regulate AI, I proposed a statutory duty for frontier developers to reasonably mitigate grave risks, enforced case by case. Congress should define those risks narrowly, to cover harms such as mass casualties and catastrophic property loss, and leave companies free to choose reasonable ways to address them. Reporting and disclosures would help an expert agency (it could be the FTC, but there are other options) identify possible failures and investigate them. Its investigations and published guidance could also help courts evaluate private claims.

The biggest misunderstanding about this type of approach is the failure to understand that case-by-case enforcement can be preventive. A statute can empower officials to act when a company fails to take reasonable precautions, before the threatened injury occurs. The FTC’s unfairness authority already works this way, reaching practices likely to cause substantial injury. A new duty aimed at grave AI risks would need its own defined scope and enforcement powers, but could be similarly proactive.

Suppose a covered developer’s own evaluations repeatedly show that during testing its agents can circumvent testing environment limits, yet the developer ignores that evidence. Under a suitably drawn statute, the government could seek an order requiring the developer to address that failure before anyone suffers a catastrophic loss. The case would examine specific conduct, supported by evidence showing a failure to satisfy a duty Congress had established. Officials would still bear the burden of proof, but they wouldn’t have to wait until after people are harmed.

Public enforcement also fixes the “deep pockets” problem in tort law. Public enforcers can target the responsible defendants, not just the rich ones. In an industry where unprofitable small companies still can have millions of customers, an order changing a covered developer’s dangerous conduct can have value even when the company has few assets. This can address failures that private litigation may leave untouched.

The not-yet-introduced Thune–Klobuchar draft AI legislation in the Senate takes this approach. Public reporting describes negotiations over a duty of care and a role for the Commerce Department in assessing developers’ precautions. The details will determine whether the eventual bill delivers on this idea. I support its central principle and believe moving this approach ahead is worth the work.

That approach needs firm limits on government power

My preferred design would preserve ordinary FTC and tort remedies, add a statutory duty on grave risk, and let companies mitigate such risks in different reasonable ways. Agency guidance could explain useful practices, but companies could meet their duty by other means. Third-party verifiers or passing audits wouldn’t be mandated, but such practices could supply evidence about a company’s precautions. Courts could weigh this evidence like any other. To stop a deployment, the government should have to persuade a court that the company had violated, or was about to violate, its duty.

Public officials have incentives of their own, of course. They can chase prominent defendants and expensive settlements or try to turn guidance into compulsory practice. A workable law therefore needs clear limits, fair notice, due process, and meaningful judicial review. It should require companies to reasonably mitigate defined risks, but not demand perfect safety, which would invite unlimited government discretion.

* * *

So that’s why I, a tech optimist, support this FTC investigation. When performed responsibly, the FTC’s case-by-case enforcement provides a good template for addressing AI safety. The current FTC investigation can show Congress how. It can help establish what happened during AI testing incidents, who was responsible, and which precautions could have mitigated the risks. Where the evidence supports enforcement, the agency should act. Where it does not, the agency should close the matter. In any case, the agency ought to explain what it can of its investigation and its reasoning to improve our understanding of AI risks and mitigation.

And Congress should build on that template. Lawmakers should address grave risks with a duty that can be met through adaptable practices as knowledge improves. Government should hold companies accountable, case by case, for the risks they can reasonably mitigate. This will incentivize them to develop and deliver safe products while leaving them free to figure out how.

Custom Fields

authors
hook
The Federal Trade Commission (FTC) is investigating OpenAI, Anthropic, and other AI companies. I am a Certified Tech Optimist, so you might be surprised to hear that I welcome the inquiry. And not because as a former FTC Chief Technologist, this investigation is bringing a lot of reporters my way.
topic
  • Technology
technology_subtopic
  • Artificial intelligence
social_image
article
false
include_in_hero_section
false
category
Articles
article_view
article content only
hide_from_our_work
false
Article

How The Digital Revolution Is Reclaiming The Household Economy

AI can reduce work that once required a building full of specialists, and put more capability back into a household.

Originally published in Daily Wire with Rachel Barkley.

For most of human history, economic production and household life occupied the same place. Families sourced and prepared food, made clothing, practiced trades, taught children, and cared for relatives as part of a shared household economy. Home was where economic life happened. Only recent history makes this seem like an odd statement.

The Agrarian era enabled larger settlements, diverse markets, and more complicated divisions of labor, but the household remained a center of production. The Industrial Revolution pulled the two apart. Higher-wage work moved into factories and, later, offices. Children left for schools. Caregiving, education, and social welfare became increasingly specialized or were taken up by the state instead of being responsibilities for the family and local community.

Industrialization made the world richer, healthier, and better educated. But it also atomized family life. In the countries where industrialization delivered its greatest benefits, it became normal for parents and children to scatter every morning, spend nearly all their waking hours apart, and reconvene for an evening meal, if schedules allowed, before going to sleep and doing it all over again.

The best incomes, education, and resources a family needed were somewhere outside the home. Family members had to leave home to get them. Western social structures are built around this. The suburbs were created for a commuter class. Schools and daycares are built for moms and dads who are out of the house from 9 to 5.

Digital technology has changed that physical fact for millions of people. A growing share of economic activity can now happen wherever there is a computer and a reliable internet connection. The result is a modern version of the household economy, one that retains the prosperity and specialization of industrial society while giving families greater control over where their lives take place.

Artificial intelligence is now widening that opening. It does not just move existing office work onto a dining-room table; it reduces work that once required a building full of specialists, and it puts more capability back into a household.

We have experienced this ourselves. We both work in public policy, and we can do most of our work from home. Although we travel, attend face-to-face meetings, and spend time in offices to do our jobs well, we don’t need to be outside the home from 9 to 5 every day.

This shift is especially meaningful to us.

A few weeks after our first child was born, Rachel was diagnosed with a rare spinal cord tumor. The tumor and the surgery to remove it left her a quadriplegic. Suddenly, ordinary parts of life required far more planning. A trip across town could involve accessible transportation, building entrances, elevators, bathrooms, and the possibility that any one of them would fail.

Remote work removes these obstacles.

Rachel leads organizations, writes, speaks, builds coalitions, and participates in national policy debates without first completing an accessibility obstacle course. Taylor can pursue his own career while remaining present for the unpredictable demands of family life. We now have three young children, two careers, and a household that functions because technology gives us room to arrange those pieces ourselves.

On Instagram, accounts of two working parents who homeschool multiple children throughout the day are growing, reflecting a shift in the household’s economic center.

AI has made that more practical. It drafts, summarizes, captions, and organizes. It turns voice into text and a pile of documents into something a person can act on. For parents, it takes some of the mental load. “The Cut”profiled Jesse Genet, a mom with a team of AI agents that assist her with the daily work of homeschooling a family of seven.

We’ve used it this way. When one of our boys had a tick behind his ear, we could get a first read on the risks while we waited for the pediatrician. We have used it to plan a Cub Scout hike and to generate practice problems when a child is struggling with a question. Let’s be clear, this does not replace a doctor, a scout leader, or a parent. It means the household does not have to wait on an institution for every next step, and it multiplies our capacity.

The Industrial Revolution organized family schedules and geography around centralized production. Digital technology gives employers and workers more room to experiment. It makes being present at home possible. Some companies will decide they operate better in person. Others will be fully distributed. Most will probably land somewhere in between, and those decisions will change as technologies, jobs, and individual circumstances change. The opportunities of family unit entrepreneurship are diverse and growing.

For generations, we became accustomed to thinking of home as the place where economic life stopped. Serious work happened elsewhere. That division now feels natural, although it was created by a particular period of technological development and is historically unusual.

We have no interest in recreating a romantic version of the preindustrial household. That world included grinding poverty, limited opportunity, and rigid social roles. We do think it is possible to keep the abundance of modern life while recovering some of what industrialization weakened: the household as an active center of work, care, education, and community.

The U.S. reached its lowest fertility rate ever this year: just under 1.6 births per woman, below population-replacement levels and below what many women report as their desired number of children. This revolution could help address this alarming problem. For many women, having children can feel like an impossible tradeoff between economic security and stepping away from the workforce, even temporarily. Imagine a future where our culture and public policy embrace the flexibility technology makes possible — so moms and dads no longer have to choose between meaningful work and meaningful time at home, but can do both.

For a long time, earning a living usually meant leaving home. Digital technology, and the AI now layered on top of it, means fewer families have to accept that separation as the price of economic participation. The economy is coming home. We should give families the freedom to decide what to do with it.

Taylor Barkley is the Director of Federal Government Affairs and Policy Advisor at the Abundance Institute. Rachel Barkley is the Director of Able Americans. They are parents of three children.

Create a free account to join the conversation!

Already have an account?

Custom Fields

hook
AI can reduce work that once required a building full of specialists, and put more capability back into a household.
category
Op-eds
social_image
article
false
include_in_hero_section
false
topic
  • Technology
technology_subtopic
  • Artificial intelligence
article_view
article content only
hide_from_our_work
false
Article

Breaking Battery Barriers

Originally published in C3 Solutions.

America’s rural population of 66 million could benefit immensely from emerging technologies and a future of abundance. In particular, long-duration energy storage (LDES) could unlock cheaper, more reliable electricity for rural Americans all over the country. Unfortunately, regulatory problems could slow down or even prevent progress on LDES. Now is the time to fix these issues and pave the way for solutions.

LDES is a term for systems capable of storing and supplying electricity for at least 8 to 12 hours (depending on who you ask). These systems could reduce energy waste and scale more easily. Most existing batteries need expensive components to increase storage, but LDES technologies could add storage easily and at a low additional cost. Estimates vary on how soon LDES could become a widespread reality, but if current trends continue, we could get there within a decade.

To be clear, LDES is a work in progress. The technology itself is still in development, and questions remain about how LDES providers would be compensated and which authorities would regulate it. But it still has potential: Form Energy signed an agreement to deliver LDES systems starting in 2027 to power AI data centers. Additionally, Google and ESS Tech are developing another LDES project.

LDES may be able to address challenges all over the country, but rural Americans stand to gain the most. To start, rural populations endure some of the worst energy conditions in the United States. These Americans spend a disproportionately high amount of their income on electricity bills, and they experience far more outages than urban and suburban households. LDES could reduce the financial burden of these problems, as it can store energy (including locally produced energy) for longer than typical batteries. The batteries can charge during low-demand periods and provide electricity during high-demand periods and outages, providing a valuable backup.

Regulatory issues could inhibit these benefits. For one, LDES technologies could be at the back of a long interconnection line when they’re ready. At the end of 2025, over 2,000 gigawatts of generation and storage capacity were seeking grid connection. Interconnection wait times often take several years. Connecting remote and rural communities to existing transmission systems is already slow, expensive, and sometimes treated as a low priority.

Even if wait times were less of an issue, LDES solutions would still be in uncharted territory for regulation. Since LDES can both provide electricity and act as insurance during outages, it doesn’t fit into any one existing market or revenue type, making regulation difficult. To end this confusion, regulators should create simpler rules that would let LDES operate in a clear and consistent regulatory environment, recognizing that the technology can provide multiple services at once.

A workaround to these existing issues could be islanding, which lets smaller grids operate independently of the larger grid. Complemented with LDES, islanding could be a good solution, especially during outages. But even if islanding were only a backup during outages, it would cause regulatory issues. Utilities often have exclusive rights to deliver electricity, making islanding difficult. Rural communities can suffer disproportionately from these problems, as they might not have the same backup options during outages as urban communities with more reliable access to the grid. One solution could be softening exclusivity rights for smaller grids to enable more islanding and LDES connections.

Some might say that there’s no point in addressing these problems now since LDES solutions aren’t quite ready for deployment yet. But these same regulatory roadblocks have caused setbacks for other emerging technologies and should be preemptively addressed. For example, distributed energy resources like smaller batteries and EV chargers deal with many of the same slow and complicated interconnection rules. These problems exist even though the technologies themselves are ready for use. If similar regulatory issues were solved earlier for distributed energy resources, more Americans might have been able to access these technologies. The same logic applies to LDES development.

These difficult regulatory conditions won’t just be problems in the future. They might also discourage innovation now. Some experts have already noted that a patchwork approach of changing regulations has made investors wary of financing battery storage initiatives in recent years. Rather than grid operators changing the rules individually, national leaders should work together to encourage consistency. Without a predictable and innovation-friendly approach, battery projects could miss out on vital capital, pushing their timeline back.

The good news is that even with open questions about when LDES technologies might be ready for large-scale usage, they could be the next technology to solve longstanding electricity problems. Slow responses and other priorities might make these solutions seem unimportant, but they could make the lives of Americans much easier. If our citizens and leaders realize the value of LDES solutions, as well as what’s holding them back, this kind of deregulation could be a reality.

LDES has potential for rural populations and could be a solution to many of their problems. It’s not the only improvement that’s necessary — grids still need to be upgraded, and transmission lines need to be built — but it’s a promising technology that’s worth exploring. Rather than waiting for these solutions to be realized, the country should act now to dismantle regulatory barriers that could slow down its success. It would be a shame if governance issues inhibit LDES, a technology with tremendous investment, years of development, and potential to help people.

Custom Fields

authors
hook
America’s rural population of 66 million could benefit immensely from emerging technologies and a future of abundance. In particular, long-duration energy storage (LDES) could unlock cheaper, more reliable electricity for rural Americans all over the country. Unfortunately, regulatory problems could slow down or even prevent progress on LDES. Now is the time to fix these issues and pave the way for solutions.
category
Media mentions
social_image
article
false
include_in_hero_section
false
topic
  • Energy
evergy_subtopic
  • Electricity
article_view
article content only
hide_from_our_work
false
Article

Open-Weight AI: A Legislative Guide

Bottom Line

There are millions of free-to-download open weight AI models. These models let startups, nonprofits, and businesses build with capable AI without raising the capital to train a model, sharing data with third parties, or locking themselves into one vendor. Yet Congress and the states are now weighing rules that would restrict open models: preapproval, presumptions that attach to model size, and liability for what strangers do with a downloaded file. Even when AI legislation doesn’t specifically target open models, compliance costs can kill them. The largest labs can pay a hefty compliance bill. Universities and startups cannot, and no model developer can control the use of open weights once released. If U.S. open models recede, foreign models will fill the gap.

Core rule: Identify the harm, place the duty on the actor who controls it, and keep the United States the best place to build and release open models.

Four Terms Lawmakers Should Know

Open-weight AI: Trained model’s weights (the parameters set during training) available for download. It need not disclose training data or source code.

Open-source AI: Weights plus source code and sometimes other pieces such as training data available for download.

Developer and deployer: The model developer trains and releases a model. The deployer fine-tunes it, supplies inputs and harnesses, aims it at a task, and onboards users. Laws that impose liability on developers directly impact open releases.

Openness is a spectrum. Model developers release different components, use different licenses, and deploy to users via download, application, or online service. ‘Open’ or ‘closed’ poorly predicts risk because the use and user matter more. 1

Why Open Models Matter

  1. Competition and entry. Open weights let entrants skip most of the cost of training a foundation model, so firms compete on customization, applications, safety, privacy, and services. This can discipline large model providers more than regulation. 5
  2. Choice and independence. Users adapt models, keep sensitive data on in-house computers, and can switch vendors. If only a few closed models serve everyone, only a few companies decide which tools exist and how they can be used.
  3. Safety and resilience. Open weights let outside researchers test and verify developer claims and repair and improve models.
  4. American leadership. Retreat from open release cedes ground to capable foreign models, and to their biases and limits. 7

Who Should Pay When People Abuse Openness’ Freedom?

Anyone who downloads an open model can modify it and pass it on. These benefits also mean that built-in safeguards may not survive such changes. Some will abuse that freedom. Closed models get misused too, and a free society should not cripple a general-purpose tool for everyone to stop a few. The developer of an open weight model can’t control the party that picks the application, supplies the data, or distributes illegal content. Developers should answer for their own unlawful conduct, but not for what unaffiliated third parties do with a general-purpose model. 45

To Keep Open Weight Models Viable, Legislation Should

  • Identify a concrete harm. Define the injury, the people affected, the conduct, and the evidence required. Fraud, unlawful discrimination, nonconsensual intimate imagery, physical injury, and property damage make clearer targets than vague references to AI risk.
  • Apply existing law first. Write a new AI-specific rule only after finding a gap in existing fraud, civil-rights, tort, consumer-protection, criminal, or privacy law. Often increased enforcement of an existing law would better fix the issue than would creating new law. If a bill’s sponsor cannot identify a gap in existing law, that’s a solution searching for a problem. 2
  • Put duties where control sits, and keep them feasible. Obligations should fall on those with knowledge and control. No developer can monitor or control open weights once released. Write light-touch safe harbors, drafted so a voluntary standard never hardens into a compliance floor only the largest labs can meet. 4
  • Preserve a national market. Preempt conflicting state rules for model development, and leave states their authority over local harmful uses. A patchwork burdens startups and open projects most. 6
  • Build the American open-model ecosystem. Direct the Department of Commerce to identify barriers, expand evaluation resources, back voluntary benchmarks, and pilot federal use of qualified American open models. Open federal datasets and funded research to developers. 7
  • Distinguish the model from the service. Downloaded weights running on American hardware raise fewer privacy and security concerns than an app that forwards every prompt to a foreign company. Where national origin warrants scrutiny, government labs could evaluate and publicize model security, capability, accuracy, and cost. 37
  • Protect speech and lawful computing. Courts have treated code as protected speech, so restricting weight release raises serious First Amendment problems, and mandating government-preferred answers raises sharper ones. Restrictions on computing should be narrowly tailored. 16

Bills With These Red Flags Threaten Open Weight Models

  • Licensing, preapproval, or FDA-style review, and compute or parameter thresholds standing in for evidence of risk.
  • “Capable of,” “could be used to,” “reasonably foreseeable misuse.” These target the tool rather than the conduct.
  • Publication as the trigger: “makes available,” “publishes,” “releases.” Release is not an injury.
  • Duties to monitor, control, or “ensure” downstream use, which no decentralized project can perform.
  • Private rights of action untethered to a demonstrated injury, and compelled ideological conditioning.

Bill-Review Checklist

  1. Does the bill name a specific, demonstrated harm and say why existing law falls short? If not, ask for both before markup. 2
  2. Does each duty fall on someone with the knowledge and control to perform it? If it lands on the developer, probably move it downstream.
  3. Could a university lab or a two-person startup comply? If only the largest labs can, the bill entrenches them.
  4. Does the bill reach harmful conduct, or the release of a tool? If release triggers the duty, retarget it at use.
  5. Is the concern the model or the service? If data flowing abroad is the worry, regulate the service.
  6. Does the analysis weigh foregone benefits, lawful speech and research, and the risk of a state patchwork? If not, ask for that accounting.

Selected Abundance Institute Sources

1. NTIA open-weights comment (2024)
2. Evaluating AI Policy Proposals (2025)
3. DeepSeek policymaker’s guide (2025)
4. AI Action Plan comment (2025)
5. House competition testimony (2025)
6. Federal tools to address state overreach (2025)
7. House technology-leadership testimony (2026)

Custom Fields

authors
hook
There are millions of free-to-download open weight AI models. These models let startups, nonprofits, and businesses build with capable AI without raising the capital to train a model, sharing data with third parties, or locking themselves into one vendor. Yet Congress and the states are now weighing rules that would restrict open models: preapproval, presumptions that attach to model size, and liability for what strangers do with a downloaded file.
article
https://www.abundance.institute/wp-content/uploads/2026/09/23211821/openmodel_legislativeguide_2026_sept_final.pdf
include_in_hero_section
false
category
Primers
topic
  • Technology
technology_subtopic
  • Artificial intelligence
article_view
article content only
social_image
hide_from_our_work
false
Article

Open Models, American Abundance

The Abundance Institute’s policy framework for open-source and open-weight artificial intelligence

People make artificial intelligence more useful, competitive, and resilient when they can experiment with it, adapt it, and build on the work of others. Open-source software is the flexible, collaborative, transparent, and inexpensive foundation of the digital economy. Millions of existing open-weight models are bringing those benefits to AI.

But Congress and the state legislatures are now weighing rules that, intentionally or not, would regulate the release of open weight models: government pre-approval, regulations on certain size models, and developer liability for how strangers use a model. Rules like these would fall hard on open weight developers. The largest closed labs could pay the compliance bill and keep building; the startups, universities, and small institutions that depend on open weights would not, leaving a gap that foreign open models will fill.

Policymakers should presume in favor of open development and release. They should address concrete harms where people actually use AI, instead of treating access to a general-purpose model as dangerous in itself. And they should protect a competitive American open-model ecosystem as an economic and national-security asset.

Keep AI model development open and competitive; hold people responsible for harmful conduct they control; and make the United States the best place to build and use open models.

Executive Summary

Our framework consists of six core propositions:

  1. Openness is a spectrum. Different developers provide access to different combinations of weights, code, and training data. Legal obligations should not hinge on an arbitrary, false-binary open-or-closed label.
  2. Open weights expand access and competition. Public weights let smaller institutions run capable models without training one from scratch or relying on other companies.
  3. Openness can strengthen safety. Outside researchers can evaluate, test, and attack an open model, and can help defenders secure systems, and safety policy should consider those benefits.
  4. Risk depends more on use than on release method. Model release does not cause harm; model misuse can cause harm.
  5. Responsibility should follow control. The party that directed the harm, or could have most easily prevented it, is the party that should answer for it.
  6. American open models are a strategic asset. If U.S. policy makes open release untenable here, capable foreign models will fill the gap, both in the U.S. and across the world.

In brief: laws must be aimed at concrete harms and at the actors who cause them rather than restrict access to new and better AI.

Plain-Language Definitions of Open Model Concepts

People use open source, open model, and open weights interchangeably. The terms describe related but different things.

AI model – A system trained to recognize patterns and produce outputs. Developers can adapt a general purpose or foundation model to many tasks rather than to one narrow application.

Model weights – The numerical settings a model learned during training. A person with the weights, suitable software, and enough computing capacity can run the model without sending every request to the original developer.

Closed model – A model that generally remains under its developer’s control. Users access it through an application, API, or online service, and the developer can monitor use, change the service, or withdraw access.

Open-weight model – A model whose trained weights are available for download. Others can run it locally, customize it, or build services on top of it. The developer may still withhold training data, training code, or other components.

Open-source software – Software released under a license that lets anyone inspect, modify, and redistribute the source code. Open-source AI is a broader and still-contested term, because a system can expose some components and keep others closed.

Policy takeaway: Openness is a spectrum. These definitions label various positions on that spectrum. They do not indicate risk, and no label should by itself determine how the law treats a model. 1

Why Openness Matters

1. Open Models Lower Barriers to Entry

Training a leading model demands enormous computing power, data, and technical talent. Published weights let other organizations start from a working foundation instead of repeating that expense. Startups can compete through better applications and specialized services; universities and independent researchers can investigate models directly; and businesses can adapt models to local needs.

Abundance’s competition filings and congressional testimony describe open weights as competitive infrastructure. When capable models are broadly available, firms compete on what surrounds the model: specialized data, applications, managed services, and quality. Using the same underlying model, one company might offer a general purpose chatbot, another might create a coding tool for large scale enterprises, and a third might offer a custom, privacy-enhancing, locally operated medical records organizing tool. Many more companies can create value, not just the handful of organizations that can fund the largest training runs. 28

2. Open Models Support Experimentation and Practical Adoption

No developer can anticipate every valuable use of their general-purpose models. Consider how people today use electricity for purposes that early power companies could never have imagined. AI models may have an even greater variety of possible uses than electricity. And open models enable broad experimentation. They let organizations fine-tune systems for particular industries, languages, communities, and workflows. Users can also run open models on their own hardware, which keeps sensitive data in-house and leaves them free to switch vendors.

Smaller institutions are most affected. For example, Abundance has described running an open model to stretch each donor dollar further and to keep its independence from companies whose policy interests may cut against its own. 1

3. Openness Can Improve Safety and Security

Many assume that publishing a capable open source model threatens security. That account is incomplete. Publishing weights lets outside researchers evaluate a model, probe how it works, red-team it, and test safeguards faster than any single lab could alone. Abundance’s NIST comment counted transparency, collaboration, security, robustness, experimentation, and educational value among the benefits a risk framework has to weigh against the costs.34

Open weight models also provide powerful tools to cybersecurity defenders when closed models are too hobbled to help against a cyber attack. 5

Openness carries no guarantee of safety, and neither does closure. What matters is which mix of developers, deployers, researchers, users, market incentives, technical practices, and law best mitigates a given risk.

4. Open Ecosystems Protect Choice and Pluralism

When everyone depends on a few centrally controlled models, a handful of companies decide which tools exist, how they behave, and what they will say. Open models give users somewhere else to go: they can compare systems, adapt them, run them locally, and switch providers. Researchers can test how a model behaves instead of taking developer assurances on faith.

This pluralism also has a constitutional dimension. Courts have treated source and object code as protected speech, and Abundance’s NTIA comment argued from that precedent that restricting model weights raises serious First Amendment problems. A government mandate that models give preferred answers would raise sharper ones still. The doctrine is unsettled, but legislators should tread carefully before they regulate what code or weights anyone may publish. 1

5. American Open Models Are a Strategic Asset— Let the World Build on Ours

Open models spread technical practices, commercial relationships, and values. If the best open models come from the United States and its allies, developers everywhere will build on American technology. If domestic policy drives American developers away from open release, someone else’s models become the world’s default.

Foreign models have risks, but those risks can differ depending on how people use them. Sending prompts to a Chinese company’s hosted app hands China your data; downloading the same company’s open model and running it on American servers does not. Blocking access to Chinese models is the wrong policy answer. We must instead make sure high-quality American open models are the ones people reach for first. 5

Testifying before Congress in 2026, Abundance urged the federal government to strengthen the American open model ecosystem, lower barriers to adoption, back voluntary benchmarks, widen access to evaluation resources, and subject foreign models to model-specific technical scrutiny. 11

Risks and Tradeoffs

Anyone who downloads an open model can modify it and pass it on, and the original developer cannot stop them. This freedom provides major advantages for researchers, entrepreneurs, and cybersecurity defenders. Yet some will abuse this freedom to facilitate fraud, cyberattacks, abusive imagery, or other crimes. Safeguards a developer built in may not survive fine-tuning. These concerns are real, but in a free society we shouldn’t cripple tools for everyone in an attempt to prevent misuse by bad actors.

Four questions can guide the analysis. The first is how the release method changes risk. Closed models get misused too, and the specific application using a model usually affects risk more than the method of model distribution. The second is who controls the model. A deployer who fine-tunes the model, supplies the data, picks the users, and points the system at a task knows more and controls more than the developer who published the weights.

The third question is what benefits a restriction forgoes. A regulation on model training affects every use of that model, including the good ones, and a safeguard that lowers one risk often leaves the model less capable, less private, or less useful for lawful speech. The fourth is whether the complaint is really about the model or about the service. A foreign model downloaded and run on domestic hardware raises different privacy and security questions from an app using the same model hosted on foreign computers by a foreign company.

Governing test: Identify the harm, locate the actor best situated to prevent or redress it, and apply the remedy at that point.

Principles for Governing Open Models

Regulate Uses and Harms, Not General-Purpose Tools

AI resembles other general-purpose technologies: its benefits and its risks both show up in particular applications. Fraud is still fraud, discrimination still discrimination, and a nonconsensual intimate image is still an injury, whether or not a model helped produce it. Law should target those harms directly instead of restricting a general-purpose model. 1

Responsibility Should Follow Control

A party should answer for conduct it directs, controls, or could reasonably prevent. That standard reaches the actor who caused the harm. It prevents holding developers responsible for every downstream act by users of the tool. Developers, deployers, application providers, and users all have to deal with various risks. Which of them is best positioned to prevent harms changes from case to case. 48

Use Existing Law Before Creating a New AI Regime

Fraud, consumer-protection, civil-rights, tort, and privacy law already reach many harmful uses of AI. So every AI bill must answer two questions: what specific harm does it address, and why are existing authorities inadequate? A bill whose sponsors cannot answer both is a bill in search of a problem. 7

Legal Duties Must Be Possible to Satisfy

Like builders of technologies like email or programming languages like Python, no developer of a general-purpose AI model can guarantee that every future user will obey the law. Once the weights are on someone else’s hard drive, a duty to monitor and control is impossible to fulfill. If imposed, such rules predictably push cautious firms toward closed models, keep small firms out entirely, and leave the field to the companies big enough to absorb compliance and litigation costs.

Preserve One National Market

Model development is interstate by nature. A single training run may draw data and computing capacity from a dozen jurisdictions, and the weights it produces travel nationwide almost instantly after release. Congress should preempt state laws that regulate model development itself, while leaving states their traditional authority over concrete local harms and applications. 10

A Practical Policy Agenda

Congress and federal agencies should:

  1. Reject licensing and preapproval for general-purpose models. Do not require government permission before training or releasing a model, and do not rely on arbitrary compute or spending thresholds as evidence of risk.
  2. Target concrete harmful conduct. Draft technology-neutral laws against fraud, nonconsensual intimate imagery, unlawful discrimination, physical injury, cybercrime, and other demonstrated harms. Define prohibited conduct, intent, causation, and defenses clearly.
  3. Clarify downstream responsibility. Limit developer liability for harms caused by unaffiliated third parties unless the developer materially participated in, directed, or controlled the harmful conduct. Distinguish model developers from deployers and end users.
  4. Create carefully designed safe harbors. Offer predictable protection to developers that follow sensible practices for the risk at hand, and write the safe harbor so that a voluntary standard never hardens into a compliance requirement that only incumbents can meet.
  5. Preempt state regulation of model development. Establish a consistent national framework for training and releasing general-purpose models. Leave states room to address concrete local applications within their traditional authority.
  6. Protect lawful access to computation. Any restriction on private ownership or lawful use of computing resources should be demonstrably necessary, narrowly tailored, and tied to a compelling interest.
  7. Support an American open-model ecosystem. Direct the Department of Commerce to identify barriers, support voluntary security and interoperability benchmarks, expand access to evaluation resources, and run limited federal pilots using qualified American open models.
  8. Expand useful public inputs. Open suitable federal datasets and publicly funded research to model developers. Cheap public data lowers the barrier that otherwise favors whoever already owns the largest proprietary corpus.
  9. Evaluate foreign models. National origin may justify heightened scrutiny, especially for privacy, security, or political manipulation. Assess models based on measures of security, capability, accuracy, and cost.
  10. Protect speech and research. Impose no restrictions on publishing lawful code or model weights, and no mandates that models express government-preferred viewpoints. Leave room for independent testing, security research, comparison, and criticism.

Conclusion

Open-source and open-weight AI are core components of the AI economy’s competitive infrastructure. No policy can eliminate every possible misuse before anyone builds and releases a general-purpose model. Insisting on that standard would eliminate U.S. open models and hand development to whichever closed model firms are best at navigating regulation.

Policymakers should instead preserve permissionless experimentation, support American open alternatives, and enforce clear laws against the people who use AI to cause concrete harm. Openness carries real tradeoffs. It also produces competitors, safeguards, and innovation that no developer and no regulator could have anticipated in advance.

Endnotes

1. Neil Chilson and Logan Whitehair, Public Interest Comment on NTIA’s Dual Use Foundation AI Models with Widely Available Model Weights (March 27, 2024)

2. Neil Chilson, Public Interest Comment: Promoting Competition in Artificial Intelligence (May 30, 2024)

3. Neil Chilson et al., Coalition Letter Opposing California SB 1047 (June 20, 2024)

4. Neil Chilson, Managing Misuse Risk for Dual-Use Foundation Models (September 9, 2024)

5. Chris Koopman and Neil Chilson, DeepSeek and the Future of AI: A Policymaker’s Guide (February 3, 2025)

6. HuggingFace, Security incident disclosure (July 2026)

7. Neil Chilson and Taylor Barkley, Evaluating AI Policy Proposals (March 1, 2025)

8. Neil Chilson and Josh T. Smith, Comment on the Development of an Artificial Intelligence Action Plan (March 12, 2025)

9. Neil Chilson, The Vibrant AI Competitive Landscape, written House testimony (April 2, 2025)

10. Neil Chilson, Clearing the Path for AI: Federal Tools to Address State Overreach (September 15, 2025)

11. Neil Chilson, American Global Competitiveness at 250, written House testimony (June 30, 2026)

Custom Fields

authors
hook
People make artificial intelligence more useful, competitive, and resilient when they can experiment with it, adapt it, and build on the work of others. Open-source software is the flexible, collaborative, transparent, and inexpensive foundation of the digital economy. Millions of existing open-weight models are bringing those benefits to AI.
article
https://www.abundance.institute/wp-content/uploads/2026/09/23211111/openmodels_policybrief_2026_sept_final.pdf
include_in_hero_section
false
category
Primers
topic
  • Technology
technology_subtopic
  • Artificial intelligence
article_view
article content only
social_image
hide_from_our_work
false
Article

Michael Jackson Didn’t Invent the Moonwalk

Read this post on John’s Substack: Creative Frontiers.

Folks packed into the Pasadena Civic Auditorium to celebrate a very special birthday. The R&B hit factory, Motown, was turning 25. The stage featured performances by some of the greatest icons in music history: Marvin Gaye, Smokey Robinson, Diana Ross, and even the Four Tops.

But when the special aired on NBC two months later, forty-seven million viewers were talking about only one man.

Dressed in a fedora, a sequined jacket, a single white glove, and bedazzled socks, twenty-four-year-old Michael Jackson had followed a performance of the Jackson 5 for one of his new solo tunes, “Billie Jean.” Halfway through the track, he planted his toe, and appeared to glide backward effortlessly through space. The audience lost its collective mind over the instantly iconic moonwalk.

In the decades since, nearly every pop star on the planet has borrowed, adapted, or outright lifted Jackson’s dance routines. Which raises an uncomfortable question for modern intellectual property law: if a performer uses that slide on stage, do they owe the Jackson estate a royalty check?

Before you answer that, it’s worth asking a simpler question, were they even his moves to sell?

The moonwalk doesn’t have an author. No, it has a chain.

And following that chain backward lands you in the middle of a debate over artificial intelligence that many insist is simple, but which history reveals to be anything but.

The DNA of a Dance

In a 1903 silent film adaptation of Uncle Tom’s Cabin, several Black actors perform a dance known as the cakewalk. It originated on Southern plantations as an exaggerated “march and glide,” a subtle, subversive parody mocking the glamor and hubris of White high society. The movement was part of a genre known as “eccentric dancing” which included the “Virginia essence,” a slow and smooth shuffle that is the great-great-grandfather of the moon walk.

When Vaudeville exploded at the turn of the century, and was later adapted for the big screen, eccentric dancing moved from southern porches to big-city stages. By the 1930s, the essence of the cake walk and the moon walk was visible in the footwork of Earl “Snakehips” Tucker, Bill “Bojangles” Robinson, and jazz legend Cab Calloway.

By the 1940s, French mime Marcel Marceau was performing the slide in his famous “walking against the wind” routine. A decade later, Dick Van Dyke did a variation of it on “The Pat Boone Chevy Newsroom” in the 1950s. But the slide achieved pure, frictionless perfection in 1955, when dancer Bill Bailey executed a backward glide off the stage of the Apollo Theater.

During the Black Power movement of the 1960s and 70s, the dance returned to its roots of resistance and community in soul and funk. James Brown incorporated it into his kinetic performances, and the dancers on the incomparable Soul Train took it further. It was here that the dance groups, Eclipse and Electric Boogaloo, glided back and forth across the stage in the late 70s, incorporating the unmistakable moonwalk.

A few years later, as Michael Jackson prepared for his upcoming performance of Billie Jean for the Motown celebration, he sought out the Soul Train dancers that had been performing the backslide. He rehearsed the move and worried he wasn’t quite getting the feel of it. Nevertheless, as he incorporated it into his routine for that fateful evening, it would soon forever become associated with him.

When asked later how he created the move, Jackson credited the kids he saw dancing in the streets of Harlem in the late 70s. His instructors wished he had mentioned them, but either way, Jackson was citing a tradition instead of a moment of invention.

He was describing the ancient practice of creativity, a practice seen in the West African griot.

The Tradition of the Griot

Fifty years ago Alex Haley rocked the best-seller lists with his groundbreaking novel: Roots: The Saga of an American Family. It traces Haley’s ancestry, beginning with Kunta Kinte, who was captured in Africa and enslaved in 18th century America. Haley traced his roots to Kinte, he said, through the account of a griot in The Gambia. And for many in the west, this was the first they’d learned of griots.

In West Africa, a griot is an artisan of memory. A creator of stories, songs, and dance that shepherd the traditions from the past, through the present, and to the future. Commonly described as “praise-singers,” scholar Thomas Hale explains they are so much more: historian, genealogist, advisor, spokesperson, diplomat, interpreter, musician, composer, poet, and teacher.

That’s a lot of jobs, and none of them start from scratch.

The griot begins with inherited stories and gives them new expression for a particular time and audience. The creativity is in the transformation of the inheritance. It’s the act of absorbing what came before, refining it through a new voice, and handing it off to the next person in line. The goal isn’t to own the tradition, but to push it a little further forward.

That process makes the idea of a single creator, or owner, difficult to pin down. Where does the inheritance end and the new expression begin? And how much of what was handed down can one claim as theirs as they hand it to someone else?

Western law looks at a breakthrough performance, like the moonwalk, and instinctively reaches for a surveyor’s tape, eager to stake out a claim and write a property deed. The griot tradition looks at the same chain, plantation to vaudeville to Harlem to Soul Train to Pasadena, and sees creativity working exactly as intended, one iteration after another, carrying the traditions forward.

The Surveyors at the Gate

Today, record labels, publishers, and visual artists are suing over the unlicensed use of their work to train generative AI. Beneath those accusations sits a story we’ve grown accustomed to telling about creativity: an expression can, in fact, belong to a single author. And with that ownership, that author can make a claim on whatever someone else makes from it. Follow the influence, send a bill.

The moonwalk would like to have a word.

The challenge is that like the griot, every artist begins by ingesting inputs from the world around us. It’s phrasing from a record heard at age seven, a rhythm heard in the river flow, a step learned from a street dancer in Harlem. Then we process those patterns, and generate a new output.

That’s the underlying process we’ve taught machines to perform. The scale of AI is new and extraordinary, but the dependence on prior work is ancient.

And while the scale may change the consequences, it doesn’t change the nature of the process. Creativity requires the raw material of life. The more of these building blocks that we place behind a permission slip, the less room we leave for the creators who come next.

Michael Jackson absorbed over a century of American dance history, synthesized it in a rehearsal hall, and gave it back to more than forty-seven million people. If he’d been required to clear the underlying rights to the cakewalk, the Virginia essence, Marcel Marceau’s pantomime, and Bill Bailey’s Apollo routine, the moonwalk would still be stuck in legal purgatory.

Yet, this is the direction we’ve been traveling for well over a century. With every new legal extension, sample clearance rule, and statutory expansion, we have steadily built higher fences around the cultural commons. We have made the act of creating, especially for the kids without a legal retainer or studio budget, a little harder and a little more expensive.

The griot tradition understands that culture thrives when it is freely learned, remembered, and carried forward.

We used to understand that too. Now, whenever someone creates, our instinct isn’t to sit in awe, but to check the chain of title.

Custom Fields

authors
hook
The moonwalk doesn’t have an author. No, it has a chain. And following that chain backward lands you in the middle of a debate over artificial intelligence that many insist is simple, but which history reveals to be anything but.
topic
  • Creative Frontiers
technology_subtopic
—
social_image
article
false
include_in_hero_section
false
category
Articles
article_view
article content only
hide_from_our_work
false
Article

AI agents should be free to browse the internet without revealing your identity

Read this post on Shoshana’s Substack: Papercuts.

What happens when an AI agent makes a purchase you didn’t intend? How will banks respond when your agent moves funds or pays bills? Should websites know that the agent is performing tasks on your behalf or should the actions only be attributed to Claude? The new capabilities of AI agents raise fundamental questions about responsibility online. Companies, foundations, and governments are suggesting different approaches to fill this gap. In this case, a flexible approach that allows different services to address these problems in the right way for each service will best preserve people’s ability to engage freely and privately online. Meanwhile, one proposal in Congress would break the way programming works.

Building out the internet architecture for agent identity

Several organizations are developing infrastructure for AI agent identity, which will be useful for different kinds of companies and websites that want to limit what AI agents can and can’t do when using their services. Currently, when AI agents access websites, their activity is typically associated with network and browser-level identifiers. The Linux Foundation is developing a new open source Agent Name Service that would build identity into internet infrastructure, connecting identity to Domain Name System (DNS). It adds on existing internet architecture to give websites a clearer picture of which agent is interacting with them and would facilitate websites identifying AI agents and controlling what they can do. Meanwhile, Cloudflare, Google, and Mastercard are developing systems for identifying agents or enabling trusted transactions. Other companies hope to link agents to biometric or government-backed identities. These approaches may make sense in some contexts, but they differ sharply in their implications for privacy and anonymity. Recent identity verification breaches should cause companies to hesitate before embracing such solutions.

Who’s responsible for AI actions?

Agents can create real commercial challenges. Customers may be unaware of the purchases or actions of their agents, and any dissatisfaction can create costs for the merchant. Scale creates other problems. Imagine if thousands of agents independently order the wrong shade of pink nail polish. Mass returns become a real business issue. An agent might independently book non-refundable flights or hotels based on incomplete preferences, leaving customers angry at the airlines or hotels themselves. And insider trading violations—even if accidental—could arise from agents being instructed to buy and sell the best stocks for maximum profit.

Medical care raises similar questions. Patients may authorize AI agents to complete forms or sign disclosures, while providers may want additional verification that the agent truly represents the patient. AI agents signing disclosure forms on behalf of people could also open up doctors and medical providers to serious liability. Other privacy laws, including FERPA and HIPAA, also assume rules about authorized access that AI agents complicate.

Existing law already addresses many questions of responsibility. Under the Uniform Electronic Transactions Act, adopted in 49 states, people are generally responsible for transactions made by their “electronic agents.” There are also early signs that when business chatbots make offers to customers—however detrimental to the business—the company will be forced to honor them. Meanwhile, banks may also require stronger verification under existing anti-fraud and Know Your Customer obligations. And this has prompted discussion of analogous “Know Your Agent” frameworks.

But broad laws addressing agent use would miss the mark. Many websites want to be accessed by AI. Stores want their products recommended by chatbots and the same goes for medical services and, really, anyone selling anything. AI is so often used for coding, and publishers of API documentation generally want AI coding agents to have access to information about how their tool’s code works to make coding easier for customers. Even within a single company, there may be things they want AI to work with and access and things they want to block it from doing.

As a result, a variety of companies may want the ability to either reject activity from AI agents or require AI agents to be tied more closely to specific individuals. To that end, there are good uses for agent-identifying technology.

Early government fumbles addressing the problem

While the Linux Foundation’s efforts promise to be a new, useful layer of the internet, lawmakers are already addressing these issues. Unfortunately, they’re doing so in ways that miss the mark. The Stealth Bot Prohibition Act would prohibit people from deploying a “stealth bot”—software that scans, indexes, scrapes, or accesses an internet source without disclosing its identity and purpose—in a way likely to damage, “burden” or “impair” the service. Despite its name, the bill reaches many longstanding computing practices unrelated to AI.

First, the Computer Fraud and Abuse Act and other statutes already prohibit many forms of malicious attacks that damage websites. If the goal is to target cyberattacks, Congress already has tools to do so.

Next, the bill never defines what it means to “burden” or “impair” a website. Every website visit—even by Google’s search crawlers—burdens a website to some degree. People scrape websites constantly for good and bad reasons. I scrape websites to monitor media mentions of the Abundance Institute’s scholars and retrieve the relevant text. Under this law, I could face ridiculous liability for simple automation. Millions of developers, journalists, researchers, businesses, and hobbyists rely on similar automations. The bill could expose routine automation to severe legal risk.

Worse, the legislation defines “stealth bots” as tools that do not disclose their identity, purpose, and intended use whenever they access a website. That requirement is wildly impractical. My automations are built in Zapier, where bits of Python code run inside larger workflows. They don’t announce, “I am Shoshana’s media monitoring bot collecting articles where Abundance Institute is mentioned.” Nor should they have to. Requiring every automated tool to reveal exactly who built it and why would impose enormous compliance costs, surprise millions of developers, and undermine anonymous access to information. People also use automated tools to research sensitive subjects—from medical conditions to domestic abuse to divorce—and should not have to disclose those purposes to any website. The First Amendment protects not only anonymous speech, but also anonymous access to information.

Finally, the bill prohibits bots from obscuring their identities to appear human when used with generative AI services. This could criminalize ordinary automation. I once built a Zapier workflow whose WordPress upload module rejected Zapier’s default user-agent string. Replacing it with random text fixed the problem. Under this bill, had I replaced it with my own name, that routine compatibility fix could become unlawful simply because the workflow incorporated AI. I also have no idea what, if anything, Zapier tells other services about my automations today—and I certainly wouldn’t want it broadcasting what I’m building or why. That kind of requirement would create serious problems not just for Zapier, but for the millions of people using modern no-code and AI tools.

Congress isn’t alone. Estonia is developing government-backed digital identities for AI agents tied to user identities. Part of the purpose is to establish who is responsible for specific actions online. The announcement does not make clear whether this will be required or to what degree agent ID would be tied to individual ID. We should expect to see many more proposals addressing different kinds and layers of AI identity.

Governments should not require AI agents to identify their users

The Linux Foundation’s proposal extends existing internet infrastructure, enabling new private solutions and choices. More concerning are proposals that would require the use of government systems to verify the identity of every AI agent—and tie those agents to real people. Lawmakers around the world are eagerly pursuing and passing age verification requirements for social media and AI chatbots. AI agents could be next. Moreover, there is a real risk that governments will require more for agents. Most age verification proposals try to establish age without requiring the user’s full identification. These efforts have varying degrees of success. However, because AI agents act on behalf of users, lawmakers may actively pursue full identity verification for AI agents.

Such proposals would run straight into common and powerful critiques of age verification regimes, including infringing on the well-established right to speak anonymously and creating identity theft risks. Governments should allow AI agents to browse the internet with the same anonymity people enjoy today and should not forcibly identify those users merely because they delegated the work to software.

AI agents are exciting and powerful new tools, but also raise new complications for consumers and businesses alike. Some companies and services may well choose to add layers of identification requirements to avoid legal risk or otherwise protect their services. Companies should remain free to require identity verification on their own websites—or reject AI agents altogether. Those choices belong to private actors, not the government.

Custom Fields

hook
Some companies and services may well choose to add layers of identification requirements to avoid legal risk or otherwise protect their services. Companies should remain free to require identity verification on their own websites—or reject AI agents altogether. Those choices belong to private actors, not the government.
topic
  • Technology
technology_subtopic
  • Artificial intelligence
social_image
article
false
include_in_hero_section
false
category
Articles
article_view
article content only
hide_from_our_work
false
Article

AI fears hit a fever pitch: What regulation could mean for the industry

Originally published in Yahoo Finance. Watch the full video here.

Former FTC Chief Technologist and Abundance Institute Head of AI Policy, Neil Chilson, joined Asking for a Trend to break down the future of AI regulation as concerns over the pace of AI development intensify.

Rough transcript

Custom Fields

authors
hook
Neil Chilson joined Yahoo Finance to talk about the problems with a federal AI slowdown and what it would look like in practice.
category
Media mentions
social_image
false
article
false
include_in_hero_section
false
topic
  • Technology
technology_subtopic
  • Artificial intelligence
article_view
article content only
hide_from_our_work
false
Article

AI policy expert dismisses Big Tech regulation calls: ‘We should see through this’

Our head of AI policy Neil Chilson joined ‘Fox & Friends’ to discuss the rapid growth of artificial intelligence, calls for slowing growth and President Donald Trump’s comments on the AI race.

Custom Fields

authors
hook
Our head of AI policy Neil Chilson joins 'Fox & Friends' to discuss the rapid growth of artificial intelligence, calls for slowing growth and President Donald Trump's comments on the AI race.

article
false
include_in_hero_section
false
category
Media mentions
topic
  • Technology
article_view
article content only
social_image
false
hide_from_our_work
false
technology_subtopic
  • Artificial intelligence
Article

New report warns AI data center boom squeezes memory-chip supply, could raise everyday tech costs

Originally published in Fox News.

FIRST ON FOX: A new policy report warns that the AI data center boom could drive up the cost of laptops, smartphones, cars and other everyday products as chipmakers shift scarce memory-chip capacity toward more profitable AI applications.

The report, published by the Abundance Institute and first viewed by Fox News Digital, says manufacturers are shifting capacity toward high-bandwidth memory, or HBM, for AI data centers, constraining the supply of conventional DRAM used in consumer devices.

To address the growing affordability concern, the report argues that Washington should avoid new tariffs and other trade restrictions that could further tighten supplies.

“You see consumer goods prices, consumer prices going up for average everyday technology because of this pull into the highest quality, highest capacity chipsets that are available, that are needed for the frontier models in AI,” former Rep. Patrick McHenry, R-N.C., told Fox News Digital, reacting to the new report.

“That has really tightened up the whole set of production from getting sand out of the ground and turning it into chips. Lower value to higher value, the cutting edge versus the second, third generation of chips. And all of this is really complicated, complicates things for consumers in a way that they cannot directly see, but they’re certainly being affected by it,” he said.

The report says the current memory-chip shortage differs from the COVID-era semiconductor crunch because it is driven largely by AI data centers’ growing demand, even as supply bottlenecks persist. But it warns consumers may face similar effects: higher prices, fewer available products and delays in replacing or upgrading phones, computers and other electronics.

“Demand is surging, and supply bottlenecks persist. However, this time, demand is driven by the rapid growth of data centers,” the paper read. “Hyperscale data center companies are buying unprecedented quantities of the world’s most advanced memory chips. American consumers will face the same consequences: higher prices, longer wait times for products, and supply shortages that may persist for years. The memory chip imbalance is quickly becoming yet another affordability concern for households and policymakers alike.”

McHenry noted that tight supplies of memory chips — parts used in many everyday electronics — are helping push up consumer costs. He argued that less-advanced chips used in household products should be treated differently from the most sophisticated chips, which he said raise greater national-security concerns.

He also argued that efforts to de-risk supply chains from China are contributing to higher costs in the short term.

“When you change supply chains, it will have an impact for a period of time. And consumers will pay the price for moving supply chains out of existing production capacity into new production capacity. We’re experiencing that right now. Every large international corporation is de-risking from China,” McHenry said. “And so we can call that ‘reshoring’ here into the United States, ‘friendshoring’ for allies across the globe. You see that connected with the president’s trade agenda as well. But for a period of time during that reallocation of those resources, you’re going to see supply costs go up and supply being constrained as you’re rebuilding these supply chains.”

“But consumers are going to pay the price for that in the short term. And that’s what we’re trying to remedy through better policy to get those supply chains up and running faster so you have less consumer impact and better choices for consumers,” he added.

McHenry argued that the most advanced chips used to develop “frontier models” — AI systems with the most advanced capabilities — should be protected from China and produced through U.S. and allied supply chains. He said the resulting short-term price increases are a worthwhile tradeoff for national security.

“We’re over the hump, I believe, on these costs being borne by the American people,” McHenry said. “I think we’re actually more five to eight years into bearing that burden, and I think the next five years are going to be far better for the American consumer because of the policies that this administration has gotten right on energy, on production of chips here in the United States and having an important distinction between high-value chipsets, low-value chip sets, high-value technology, low-value technology and what that means for the American consumer and for national security. They’ve really balanced that in a very smart way.”

McHenry explained lawmakers must balance national-security priorities with keeping consumer costs down by distinguishing cutting-edge chips from lower-end technologies used in everyday products.

“We want to make sure we have this full stack of production and capacity here in the United States. The Trump administration has prioritized that. That is a welcome and good thing. And over time, we’re going to see the benefits. The consumer is going to see the benefits, and then you have to have the distinction between those important matters and then all the stuff that should be freely tradeable around the globe,” McHenry said. “And it’s those lower-value things like memory chips that will have a major impact on consumers and the way that the American people live. We wanna be sensitive to that and we wanna be smart as American policymakers on that.”

The Abundance Institute report called on the Federal Trade Commission (FTC) to study how major chipmakers allocate manufacturing capacity between conventional DRAM chips used in everyday electronics and high-bandwidth memory, or HBM, used in AI data centers.

“The study could confirm that each firm is independently responding to price signals,” the policy report reads.

McHenry argued that policymakers should distinguish between cutting-edge chips with national-security implications and lower-value chips used in consumer products.

Fox News Digital contacted the FTC for comment.

Custom Fields

authors
hook
Fox Business reports on our memory chip paper.
category
Media mentions
social_image
article
false
include_in_hero_section
false
topic
  • Technology
technology_subtopic
  • Artificial intelligence
article_view
article content only
hide_from_our_work
false
Article

A Fourth, Even Less Bad Way to Regulate AI

Read this post on Neil’s Substack: Getting Out Of Control.

The great Tyler Cowen has weighed in on “the least bad way to regulate AI,” and he starts from the right question: how to govern the risks of frontier development without slowing innovation. (Cowen writes only about frontier model development, not about risks from applications like chatbots, health diagnostics, or coding tools.) He gives good reasons to act. The executive branch now governs frontier models through a framework that is opaque, discretionary, and probably too deferential to national security interests. An FDA-style gatekeeper would slow innovation to the speed of government. Generalist courts might impose sweeping liability on model developers. And if one lab causes a disaster, the whole industry takes a reputational hit. Cowen’s answer, an industry-led nonprofit modeled loosely on the Financial Industry Regulatory Authority (FINRA), is among the more thoughtful ideas on offer.

Characteristically, Cowen’s post provoked many responses, too. One of my favorites was Brendan McCord’s nuanced discussion of institutional design principles. Judge Glock also has an robust defense of the common law approach — a steel man of what Tyler calls the “do nothing” approach. Gabriel Weil’s response on X and his underlying scholarship are also worth your time.

I agree with Glock and Weil that the common law is very capable. When Cowen proposes immunizing companies from liability, he gives up too much. He trades away the advantages of the common law for potentially ineffective risk reduction.

But we don’t need to rely on common law alone. There is a way to keep the benefits of common law, incorporate the institutional features McCord supports, and address Cowen’s concerns. Congress can strike a better bargain: impose a statutory duty to mitigate catastrophic risk, with some notification and transparency measures but no prescriptive process regulation.

Cowen dismisses the common law too quickly

Cowen would gather the major labs into a private nonprofit that Washington authorizes and oversees, with government officials sitting on the body. It would audit companies and their models periodically, starting with cybersecurity. A lab that passed an audit would be “exempted from standard liability law,” at least after showing what Cowen calls “basic, reasonable care, as opposed to extreme or deliberate negligence.”

Cowen compares this “private regulation” favorably to two alternatives. He is plainly right about the first, FDA-style pre-approval, which would be too slow and too risk-averse. I have argued the same.

Second, he critiques standard liability law (negligence, product liability, etc.) as the result of a “do nothing” libertarian approach. Relying on liability law to govern model development, he argues, would mean that 1) the companies get sued repeatedly; 2) courts lack the expertise, so this is “unlikely to go well”; and 3) AI companies would prefer a “predictable participatory process staffed by experts.”

These critiques are superficial or fixable. Neither 1) nor 3) is a strong argument against tort liability. Start with 1). If a company causes harm and is the least cost avoider, the efficient number of suits, and the efficient size of the judgments, may well be large. Frivolous litigation does burden large companies, but the right fix is changing trial procedure generally, through loser-pays rules for instance, rather than protecting one set of large defendants from all liability.

As for 3), of course large companies would rather pay a fixed compliance cost than face open-ended liability. Their preference does not make the regime right. Everyone agrees that the net harm from frontier development is uncertain and that we do not yet know how to mitigate it. So why insulate companies from liability for adopting practices that may not reduce risk much or at all?

In fact, trading liability for check-the-box compliance could limit competition, since compliance could be expensive. Worse, it would do so while weakening the incentive to find effective safety practices.

That leaves Cowen’s strongest point: his concern about the courts’ lack of expertise. Agencies exist in large part to build specialized knowledge. Judges and juries who lack it can go wrong in several ways: entertaining claims against the wrong party, misjudging the standard of care, or miscalibrating damages.

Perhaps knowing better, Cowen skips the most common complaint about liability law, that its judgment arrives too late to restore lives or property. Tort law looks backward, but it also shapes behavior going forward. Court decisions reverberate through industries, affecting later training, deployment, and other decisions by labs, boards, insurers, and investors.

Compared to regulation (whether public or private) the common law has real advantages in addressing Cowen’s concerns. Negligence law can handle uncertainty better than most statutory schemes. No one knows the scope or severity of future AI incidents, and experts disagree about which practices would mitigate them. Writing well-calibrated rules in that whirlwind is hard, even for industry participants. A negligence suit seeks simpler answers: it tests legal principles of duty, breach, causation, and injury against a specific fact pattern. The reasonable care standard can adapt to new threats and new best practices without waiting for revised rules. And many different courts decide these cases, which makes regulatory capture difficult.

(On capture, Cowen paints a silver lining on that dark cloud: he claims that labs that want to keep less-well heeled rivals out will push the FINRA-like org toward demanding standards. That assumes, without support, that expensive compliance means safer models.)

The common law also demands less expertise than ex ante regulation does. Courts start from an injury and ask who caused it and what care was reasonable in that situation. Designing rules to govern the future conduct of every industry actor in every possible situation demands far more technical and business knowledge.

Still, there is one indisputable cost to common law’s case-by-case evolution: it takes time to reduce uncertainty. Precedent accretes like sediment settling, and future cases look at the resulting bedrock for the fossil record of decisions. The patterns emerge, but slowly.

Is there a way to speed this process up without losing all the benefits?

A fourth way

Cowen rejects the FDA model and pure tort law, then settles on FINRA. But a fourth option better preserves common law benefits and answers his worry about judicial expertise.

The Vessel of AI model safety governance shall steer between the Rock of Rigid Prescription and the Whirlpool of Unbounded Discretion.

Congress should impose a clear, performance-based duty on frontier model developers: reasonably mitigate the risk of mass casualties and catastrophic property loss. The statute should not mandate particular model design, testing method, or governance system. It should require covered developers to disclose dangerous capabilities and model-specific mitigations, and to give the government a reasonable way to verify such disclosures. It should also require incident reporting. This framework should replace state efforts at regulating model safety — this is a national issue and needs a national standard.

The Department of Commerce, a likely home for this authority, could issue nonbinding guidance after public comment, explaining how it understands the duty and describing testing, security, governance, and verification practices that it believes would satisfy it, while leaving developers free to use other reasonable methods. Commerce would need investigative powers, along with authority to seek permanent injunctions and civil penalties.

The framework wouldn’t require audits, and passing one wouldn’t create legal immunity. (Though audits might be a very reasonable mitigation effort.) When companies disclose dangerous capabilities, Commerce could verify a disclosure itself or accept another reasonable method. Congress could also protect employees and contractors who report noncompliance.

Nothing here requires premarket approval or limits public model access on the regulator’s whims. Commerce could stop a deployment only by persuading a court that a developer had breached the statutory duty, or was about to. Requiring court involvement limits the risk that the nonmandatory guidance and threats of enforcement over time become de facto pre-approval.

By enforcing a duty to mitigate, paired with reporting and guidance from experts who know the technology, Commerce would develop a body of knowledge to inform courts evaluating claims. This would more quickly supply the expertise Cowen rightly says the courts need.

The Federal Trade Commission’s privacy and data security enforcement already works this way. The FTC enforces a general prohibition on “unfair or deceptive acts and practices,” with the details fleshed out through agency guidance and a long line of cases (mostly settlements), adjusting as the technology changes.

The approach also echoes some provisions of state laws, including ones I have opposed: California’s revised SB 1047, vetoed, and its successor SB 53, signed; New York’s RAISE Act; and Illinois’s SB 315. The overlap between these state laws creates a patchwork of state obligations for what is a national issue, which is why Congress should preempt these and other state AI safety laws. (Cowen’s proposal doesn’t specifically say how the FINRA-like body would interact with state law.)

I didn’t invent this framework. Ideas like it are circulating in draft language in Congress. It won’t solve all problems and it surely will create some. But it has a shot at maintaining the benefits of common law while mitigating some of common law’s weaknesses.

I am glad Cowen is hunting for less bad answers to AI safety. The hunt is not over. A federal duty to reasonably mitigate the worst risks, backed by guidance and rigorous review and enforcement, could strike a better balance between safety and innovation than any of the three options he considers.

And sometimes, especially under uncertainty and urgency, “less bad” might be good enough.

Custom Fields

authors
hook
Congress can strike a better bargain: impose a statutory duty to mitigate catastrophic risk, with some notification and transparency measures but no prescriptive process regulation.
topic
  • Technology
technology_subtopic
  • Artificial intelligence
social_image
article
false
include_in_hero_section
false
category
Articles
article_view
article content only
hide_from_our_work
false
Article

“Hardly any” AI regulations? Becerra should know better

California has more AI-specific laws than any other state

Originally published in Orange County Register with Lance Christensen.

Asked at Politico’s Sacramento summit last week whether California needs stronger artificial intelligence rules, gubernatorial candidate Xavier Becerra answered: “Gosh, we hardly have any.”

He must have missed more than a few pages in the California Code, and some memos along the way. Far from a regulatory vacuum, California has piled on more AI-specific statutes than any other state in the country — dozens in the last two years alone. Mr. Becerra would also do well to remember that technology isn’t unregulated just because it’s “new.” AI is not a lawless frontier today, and it wasn’t when he was attorney general.

In April 2023, four federal agencies under the Biden Administration issued a joint statement declaring that existing laws against discrimination, fraud, and unfair practices “apply to the use of automated systems” just as they apply to everything else. An employer that uses an AI hiring tool in a way that violates anti-discrimination law can face liability under the same employment statutes that govern human hiring decisions.

State attorneys general have said the same. Connecticut’s William Tong issued a formal memorandum detailing how his state’s consumer protection, privacy, and anti-discrimination laws already apply to AI systems. Becerra’s successor, Rob Bonta, issued two legal advisories clarifying how California’s laws apply to AI.

The office Becerra once ran has already taken the opposite legal position to his claim.

Then there is the regulation California has written specifically for AI. In 2024, Governor Gavin Newsom signed nearly a score of AI bills. In 2025, additional legislation was enacted, including the Transparency in Frontier Artificial Intelligence Act, companion chatbot safeguards, and an expanded transparency act. On the agency side, the California Privacy Protection Agency finalized sweeping regulations on automated decision-making technology last year.

According to Stanford’s AI Index, California has more AI-specific laws than any other state. Whatever one thinks of these laws individually, “hardly any” they are not.

And Sacramento looks to be nowhere near done. Two dozen more AI bills survived the Legislature’s appropriations committee gauntlet and await floor votes before the August 31 deadline. Few of them are coordinated and each bill adds another layer to a compliance thicket that large incumbents may be able to comply with but startups certainly cannot. The cumulative effect is a tax on building in California, and an invitation for the next great enterprise to incorporate or expand in Austin or Miami instead.

The same mindset is choking the physical foundations of the modern economy. Imperial County imposed a one-year moratorium on new data centers, and Monterey Park banned them outright. Data centers are where AI and everything else we do online actually happens; a moratorium on them is a moratorium on participating in the defining industry of the decade. It is no surprise that the country’s two wealthiest counties (Loudoun County, Virginia and Santa Clara County, California) are also the top two counties for data center densities. The economic benefits are also reaching places like Richland Parish, Louisiana and Grant County, Washington.

Lawmakers also have a chance to power the industry with clean, reliable energy. Assembly Bill 2647 would have exempted qualifying advanced reactors — including revolutionary small modular designs — from California’s 50-year-old moratorium on new nuclear plants. That bill was gutted before its first committee hearing and amended down to a study, continuing the “analysis paralysis” approach to technology in a state once defined by energy innovators and renegades.

So, while states like Utah and Tennessee surge forward to build the future of clean and abundant energy, California will stay on the sidelines and ignore the hundreds of millions of dollars spent over the past decade at Lawrence Berkeley National Laboratory, and elsewhere, producing cutting edge research on nuclear energy.

To summarize: California already has the nation’s thickest stack of AI-specific statutes, layered on top of general laws that attorneys general and federal agencies have confirmed already apply. It is poised to add two dozen more bills, all while its localities ban the infrastructure behind it and the state shelves the energy the next decade requires.

The question for California’s next governor, whoever it may be, is not whether the state has AI regulations. It has plenty. The question is whether California wants the jobs, the tax revenue, the innovation, and the technological leadership that comes from actually building 21st Century infrastructure.

The answer today looks like the state will stymie, regulate, and ban its way out of the industry that largely originated here. “Gosh, we hardly have any” couldn’t be further from the truth.

Bryce Chinault is the Director of State Government Affairs at the Abundance Institute, a mission-driven nonprofit focused on emerging technologies and economic growth.

Lance Christensen is the Vice President of Government Affairs at the California Policy Center, an educational nonprofit working for the prosperity of all Californians.

Custom Fields

hook
Asked at Politico’s Sacramento summit last week whether California needs stronger artificial intelligence rules, gubernatorial candidate Xavier Becerra answered: “Gosh, we hardly have any.” He must have missed more than a few pages in the California Code, and some memos along the way. Far from a regulatory vacuum, California has piled on more AI-specific statutes than any other state in the country — dozens in the last two years alone.
category
Op-eds
social_image
article
false
include_in_hero_section
false
topic
  • Technology
technology_subtopic
  • Artificial intelligence
article_view
article content only
hide_from_our_work
false
Article

How an ‘Abundance’ Policy Shop Is Approaching Data Centers

Chatting about win-win solutions with the Abundance Institute’s Ryan Norris.

Published in Heatmap News by Jael Holzeman.

This week’s conversation is with Ryan Norris, senior fellow for energy policy at the Abundance Institute. The libertarian-leaning institute — whose name cleverly shortens to AI — is a new-ish entity with increasing relevance in energy and tech spaces. As Norris and I discussed, it’s starting to help shape policy on data center development and the generation that’ll power it all, especially in Republican circles. Norris himself previously worked with Americans for Prosperity, a right-wing political organization. I reached out to him and asked if we could chat because I wanted to know more about the institute’s work within the energy space. He wound up saying a lot more than I expected. So let’s dive into it.

The following conversation was lightly edited and abridged for clarity.

So let’s start with what you’re working on. What’s on your desk these days?

Here at Abundance, we sit at the juncture of emerging technology and the energy they need to bring that new technology to bear to impact life positively. We are always in a constant state of learning and researching what the latest thoughts and feelings are around certain policies, particularly around AI and data centers, and then energy technology. How do they feel about nuclear? Geothermal? Solar and battery arrays?

A lot of what I’m working on is Project Gigawatt, a body of policy that fits into permitting, generation, the grid, transmission, and then market and demand. Policies that we believe will generate more, transmit more, and as much of a free market approach as possible. Knowing that a lot of states have regulated utilities, when the state utility can’t produce what the state can potentially actually generate or would need to in order to accommodate large loads, we think there needs to be other opportunities to either bring that power or purchase it in a different way.

When it comes to this policy set, how are you taking into account the intensifying backlash to data center and AI infrastructure, as well as the energy attached to it?

As everyone can sense, things are moving rapidly, and there is a natural inclination to question how fast we’re going. I think these concerns need to be addressed seriously and respectfully. You can’t just say negative things about people who care about water quality or impacts to their local economies. Those are valid. I’ve lived through those. I come from a rural place in Arkansas that had oil and gas plays. And I’ve seen there needs to be conversations with people living in those areas too.

We cannot discount the backlash. When you take the legitimate concerns and pair them with the opportunities coming, I think there’s actually a chance to set up win- win solutions. It shouldn’t be a win-lose scenario here. They have skepticism about AI in the short and long term — that’s a natural inclination and not a negative, per se. But educating people and policymakers about data centers, that’s important.

\What is your approach to the rise in land use regulation around data centers and energy infrastructure, moratoria and restrictive ordinances?

As much as possible, you want the infrastructure and cost allocation to be borne by the business causing it. That’s the motivation behind a lot of colocation partnerships happening right now, like the Kilby project in Texas, with natural gas powering a Microsoft hyperscale.

To us, it’s about setting up the opportunity for private property owners to sell to those hyperscalers and those generating the energy. Setting up situations where you’re not stopping people from benefiting. A lot of the “bring your own power” concept, we really like that. Maybe having it where power purchase agreements are more in the mix, things along those lines. That’s where I see things.

The energy increases to our utility bills, people are concerned about it, and that’s a bread and butter issue. That’s the approach: We know we need grid upgrades and want to have the most cost effective versions of those as possible, but you want those needing the power paying for it and not putting it on the backs of residents.

I’m curious, what’s you and your organization’s approach to the rise of gas infrastructure built for AI and the potential impacts that could have on climate change?

I don’t discount the issue of climate change.

Let’s say we’re not able to decarbonize enough to reverse the effects of warmth. We know we’ll have to create energy. We know we have other options for energy that need to be in the mix — more nuclear, which now even some of those who are climate-minded understand is an abundant energy source. I’m also interested in new technologies in geothermal where it can be viable in more places than we thought. You can drill down and tap hot rocks, a basin of water, turn a turbine, and that’s more acceptable for those who care about the climate. And states are looking at it, including my state of Arkansas. I bring these up because I also care about sources that provide firm, consistently available power.

We attended the American Legislative Exchange Council, and one of the things we do, we’re voting members on the energy, environment, and agriculture task force. We’re pro letting the market decide what they need. So we took opposite stances from what people typically consider normal standards on the center-right about banning “net-zero” for local governments. It did pass as model legislation but if we believe “all of the above” is the approach, we also want to be principally correct to ourselves that it doesn’t mean banning wind or solar where it’s viable.

My last question: What’s your thought on the future of politics around AI infrastructure and energy generation for it?

There’s definitely headwinds to those in that industry. I think the sense is, they understood what they wanted and didn’t see any barriers to the way they’d go about it. That’s causing ripple effects in our politics at the local level, including here in Arkansas, where I live in Pulaski County. I think it’ll stay important particularly as it connects to affordability concerns around energy. We know we need more energy, but we want it at the lowest cost possible to the residential side. If people are feeling like data centers are driving the demand for the energy and aren’t on the hook for it, that’s going to position them to be more negative towards the technology.

But we have to expand the conversation. There are folks out there talking about 3D printing for homes, using proprietary cement mixes to build homes in a few weeks when they took months. Agriculture is using robotics in lieu of pesticides and herbicides. Advanced manufacturing is improving the quality of medical equipment. No one completely understands the end goal of new energy to fuel the data centers and AI to get us where there’s a net benefit to them.

Custom Fields

authors
hook
Senior Fellow Ryan Norris is featured in this Heatmap News interview for his thoughts on energy policy and data centers.
article
false
include_in_hero_section
false
category
Media mentions
topic
  • Energy
evergy_subtopic
  • Electricity
article_view
article content only
social_image
hide_from_our_work
false
Article

Modern Data Centers Use 10x Less Water

Read this post on Richard’s Substack: Econosseur.

“The good news is that water is no longer a primary resource constraint for building data center IT infrastructure. But increasing efficiency in water use is leading to higher electricity demand. And electricity remains the main resource constraint on data centers.”

Summary

  • New data centers are about 10 times more water efficient than the older ones with evaporative cooling systems.
  • The more modern water-efficient closed-loop cooling technology is less energy efficient than the older evaporative cooling technology. But that inefficiency is diminishing.
  • Data and trends suggest that computational electrical efficiency will rise 3x between 2027 and 2030. This means the energy per computational output will decline by 88% between 2027 and 2030.

Introduction

This year has seen a surge of national polling on data centers, and the results are strikingly consistent. Americans are increasingly skeptical of rapid data-center development and are especially hostile to having one built near them.1 In both the Gallup poll (see Jones, 2026) and the CBS News/YouGov poll (see De Pinto, 2026), the two most common reasons for opposing data centers were their use of water and electricity. Yet the CBS News/YouGov survey showed that only 16% of respondents said they knew “a lot” about data centers.

In this article, I dispel some of the misinformation and myths about data center water use and highlight how modern cooling technology has vastly reduced water use. I also highlight the connection between data center water use, increased energy demands, and the parallel increases in energy efficiency in modern data center designs.

By showing that water resource constraints are no longer a major issue with data center construction, this article shines a light on the remaining fact that electrical resource constraints are the primary resource constraint for data centers. Despite the increases in data center electrical efficiency, states and countries need to figure out how to provide more power for these critical components of the US IT infrastructure.

This article is organized into the following four sections, followed by a concluding section, references, and two appendices.

  1. Water use per kWh is falling sharply in the best new designs
  2. What is new about modern closed-loop cooling
  3. There is still a water-energy tradeoff
  4. Energy per unit of compute is falling extremely rapidly

1. Water use per kWh is falling sharply in the best new designs

“For a new facility, the trends in the evidence suggest the current technological frontier for data center water efficiency is 0.1 – 0.3 L/kWh. That is about 10 times more water efficient than the older traditional evaporative cooling systems.”

The standard metric for data center water use is Water Use Effectiveness (WUE). It measures the liters of water per amount of energy delivered over some period.

WUE=liters of waterkilowatt hour (kWh) of IT electricity

Historically, a data center using cooling towers or direct evaporative cooling could consume roughly 1.7–2.5 L/kWh, depending heavily on climate, cycles of concentration, equipment, and operating practices.2 The trajectory of water efficiency (WUE) at the leading hyperscalers is dramatically lower. Table 1 shows that the frontier closed-loop cooling technologies on new data centers are about 10 times more water efficient than the older traditional evaporative cooling technologies.

Microsoft reports that its fleet-wide WUE fell nearly 90%, from about 2.3 L/kWh to 0.27 L/kWh in 2025.3 AWS reports 0.12 L/kWh in 2025, down from roughly 0.25 in 2021, although one needs to be careful because companies sometimes report withdrawal WUE and sometimes consumptive WUE.4

And those fleet averages actually understate what is occurring in new construction. In Priest and Solomon (2026), Microsoft says its newest liquid-cooled AI data centers use direct-to-chip closed loops with zero water evaporation. Oracle says the same about AI facilities it is building in New Mexico, Michigan, Texas and Wisconsin. The cooling system is initially filled and subsequently has essentially no evaporation, blowdown, or continuous makeup-water requirement.5

For a new facility, the trends in the evidence suggest the current technological frontier for data center water efficiency is 0.1 - 0.3 L/kWh, which is about 10 times more water efficient than the older traditional evaporative cooling systems. For modern data centers, water usage is no longer the main resource constraint.

As a caveat, there is no guarantee that every facility is moving this way. For example, Australia’s NextDC data center firm just reported a deterioration in water use effectiveness from 2.25 to 2.40 L/kWh, illustrating how much actual outcomes depend upon cooling architecture, climate, commissioning and operation.6

A June 2025 study from Lawrence Berkeley National Laboratory researchers makes the point that water consumption per kWh varies by more than three orders of magnitude across configurations, and total workload water use varies by more than 10,000 times.7 Cooling architecture, grid generation, server efficiency, utilization and climate all matter.

2. What is new about modern closed-loop cooling

The phrase “closed-loop” can be misleading because chilled-water systems have already been closed loops for decades. The important recent advances in data center cooling technologies are a combination of the following components:

  • Direct-to-chip liquid cooling
  • Warmer coolants
  • High-efficiency heat exchangers
  • Dry outdoor heat rejection

The first row of Figure 1 shows the traditional evaporative cooling technology workflow. The second row of Figure 1 shows the new closed-loop data center cooling technology workflow that is increasingly implemented in new data centers.

Figure 1. Traditional evaporative cooling workflow versus modern closed-loop cooling workflow

Note: See ASHRAE (2026) and Vertiv (2026). GPU/CPU is graphics processing units and central processing units. CRAH/CRAC is computer room air handler and computer room air conditioner. CDU is coolant distribution unit.

In the modern closed-loop cooling workflow in the bottom panel of Figure 1, the coolant is brought directly next to the processors (CPU/GPU), functions as a coolant at higher (less cold) temperatures, and never has to evaporate.

Grizzel (2026), an Oracle cloud infrastructure architect, gives a good analogy. The modern closed-loop cooling system is basically a large-scale automobile radiator. Coolant picks up heat at the chip, carries the heat outside, rejects the heat through a radiator-like heat exchanger, and returns to the chip.

Five key engineering advances make the modern closed-loop cooling workflow possible.

  • Better cold plates (stage 2 in the modern closed-loop cooling workflow). Microchannels and optimized flow geometry put the coolant within millimeters of the GPU or CPU die. Water has roughly 4 times the heat capacity of air by mass and vastly greater volumetric heat-carrying capability. Instead of blowing enormous quantities of air across a 1,000 – 1,400 W GPU, heat is captured by the more efficient water or liquid coolant at its source.
  • Coolant distribution unit (CDU, stage 4 in the modern closed-loop cooling workflow). The server loop is separated hydraulically from the facility loop through a heat exchanger. The CDU controls pressure, flow, temperature, filtration and leak detection. That isolation allows highly controlled coolant conditions around extremely expensive electronics without requiring the entire building’s water circuit to have the same chemistry or pressure.
  • Higher coolant temperatures. If the water returning from the rack is already 40–50°C, you often don’t need a conventional refrigeration cycle to dump its heat into 20–35°C outdoor air. The temperature difference itself can do much of the work. This enables chiller-less or nearly chiller-less operation.8
  • Increased use of microchannel heat exchangers. This engineering gives a large surface area and small thermal resistance while reducing coolant volume and fan requirements.9
  • Improved software. Thousands of sensors now dynamically adjust pumps, fans, flow rates and temperatures. Instead of designing the entire facility around the worst conceivable summer afternoon and running it that way year-round, the cooling system continually adjusts toward its optimal operating calibration. Evans and Gao (2016) show how Google DeepMind’s work on machine-learning control of data center cooling reduced their data center cooling bill by 40%.

3. There is still a water-energy tradeoff

While it is true that modern data center closed-loop cooling architecture is more water efficient, this more modern approach requires more electricity than the traditional evaporative cooling technology. And the water-energy tradeoff can become more electrically expensive in areas like Phoenix, Las Vegas, or Texas with hot average temperatures.10

The newer direct-liquid designs are narrowing that tradeoff substantially because they deliver heat to the outdoor heat exchanger at much higher temperatures. This means that data centers constructed in 2027-2030 are likely to have the newer direct-liquid designs with their low water use (low WUE), with a smaller and narrowing energy use penalty (lower power usage effectiveness, PUE).

One last caveat to the water efficiency discussion around data centers is that they include both direct water usage efficiency measures or site WUE, and they also include indirect water usage called source or lifecycle water intensity. Examples of indirect water usage and intensity are data centers that use a gas combined-cycle electricity plant, nuclear plant or steam-cycle thermal electricity generator. These power sources that might power a data center also use water, which indirect usage is incorporated into the source or lifecycle water intensity measure but is not incorporated into the site WUE measure.

4. Energy per unit of compute is falling extremely rapidly

“AMD reached an estimated 4 times increase in AI energy efficiency from 2024 to 2026, building momentum toward its 2030 goal to deliver a 20 times increase in rack-scale efficiency for AI training and inference.” (AMD, 2026)

“…it is not unreasonable to project a 3x increase in computational efficiency between 2027 and 2030. The trends and predictions… suggest that the watts/FLOPS or energy per computational output could be reduced by 88% between now and 2030.”

Water is no longer a major constraint on data center construction. Instead, electricity remains the main resource constraint. Although the more water-efficient modern closed-loop data center cooling systems actually use more electricity than the older evaporative systems, this increased electrical penalty is also declining as the technology improves. In addition to improvements in water cooling systems’ electrical efficiency, data centers’ computational electrical efficiency is improving extremely rapidly.

A current measure of computational intensity in the generative AI and large language model (LLM) context is the token. Each prompt that a user submits to an LLM is broken down into basic units, like words, that are called tokens. The number of tokens initiates computations using the model in order to return a response from the LLM. A more objective unit of computational intensity is the floating point operation or FLOP, which is one arithmetic operation in a computer system performed on numbers represented in floating-point format.11

A measure of the electrical efficiency of data center computational intensity must measure the number of FLOPs per amount of electricity per unit of time. A joule is a unit of energy that is measured in watts (units of electricity) times seconds (units of time). And FLOPS represents floating point operations per second or FLOPs/sec. So equivalent measures of data center electrical efficiency of compute could be the following, in which more compute electrical efficiency is characterized by higher FLOPs per watt second or higher FLOPS per watt.

FLOPswatt×sec=FLOPs/secwatt=FLOPSwatt=FLOPsjoule

For example, an AMD MI300X high performance computing data center GPU accelerator chip provides about 3.48 × 10¹² FLOPS/watt. This would represent one of the highest efficiency compute per watt chips on the market. This chip is likely one of the two unlabeled pink dots in the upper-right corner of Figure 2.

Epoch AI’s 2026 “Trends in Artificial Intelligence” reported that the FLOPS per watt compute efficiency is increasing at a rate of 34% per year for leading hardware since 2016. Figure 2 is a screenshot of the GPU electrical efficiency plot from Epoch AI (2026). The pink dots show that leading GPU hardware from 2016 to 2024 and each hardware’s release data and FLOPS per watt. The pink dashed line represents the estimated growth rate per year. An equivalent statement is that the watts per FLOPS (floating point operations per second) are decreasing at a rate of 34% per year.

Figure 2. Machine learning hardware by release date and compute performance per watt (FLOPS/watt), from Epoch AI (2026)

Epoch AI’s (2026) estimate of 34% annual increase in FLOPS/watt or 34% annual decrease in watts/FLOPS suggests that computational efficiency per unit of energy will more than double by 2030 (1.344 - 1 = 2.22 or +222%). This efficiency is augmented by the potential move to lower numerical precision.12

AMD (2026) presented its new efficiency roadmap, which is striking and ambitious. “AMD reached an estimated 4 times increase in AI energy efficiency from 2024 to 2026, building momentum toward its 2030 goal to deliver a 20 times increase in rack-scale efficiency for AI training and inference.” This implies a 4.7 times increase in computational efficiency between 2027 and 2030. As AMD reports, this is considerably faster than historical semiconductor trends. Figure 3 is the first figure in the AMD (2026) report, and shows their 2024-2026 FLOPS/watt growth and their projected efficiency increases through 2030 against the lower historical industry average efficiency growth.

Figure 3. AMD (2026) projected electrical efficiency growth (FLOPS/watt) compared to industry average

Between AMD’s projected goal of 4.7 times computational efficiency increase from 2027 to 2030 and Epoch AI’s historical estimate of 34% per year increase or 2.2 times increase between 2027 and 2030, it is not unreasonable to project a 3x increase in computational efficiency between 2027 and 2030. The trends and predictions of AMD (2026) and Epoch AI (2026) suggest that the watts/FLOPS or energy per computational output could be reduced by 88% between now and 2030.

Conclusion

The good news is that, given recent trends in data center cooling technologies, water is no longer a primary resource constraint for building data center IT infrastructure. But increasing efficiency in water use is leading to higher electricity demand. And electricity remains currently the main resource constraint on data centers.

The bad news is that current US data center capacity is nowhere near the demand for computational capacity from all sources of the world’s broad IT providers. This means that demand for electrical capacity will continue to increase despite the increases in electrical efficiency in computation and in cooling systems.

With the water resource constraint seemingly solved, the electrical resource constraint becomes paramount. States and countries that add electrical capacity the fastest will grow the fastest.

References

AMD, “AMD Tracks Ahead of Rack-Scale AI Energy-Efficiency Goal,” Advanced Micro Devices (Aug. 18, 2026).

APPC, “Opposition to Local Data Centers Rises Sharply, Annenberg Survey Finds,” Annenberg Public Policy Center, University of Pennsylvania (Aug. 11, 2026).

ASHRAE, “Integrated Design Principles: AI Data Center Energy Performance Framework,” American Society of Heating, Refrigerating and Air-Conditioning Engineers (2026).

Davies, Alex, “Amazon’s data centers are 7x more water-efficient than the industry average. Here’s how we do it.” Amazon News (Jun. 11, 2026).

De Pinto, Jennifer, “More oppose than favor data centers in their area, but few admit knowing a lot about them, CBS News poll finds,” CBS News (Jun. 24, 2026).

Epoch AI, “Trends in Artificial Intelligence,” Epoch AI (Updated Feb. 5, 2026, accessed Sep. 2, 2026).

Evans, Richard and Jim Gao, “DeepMind AI Reduces Google Data Centre Cooling Bill by 40%,” Blog, Google DeepMind (Jul. 20, 2016).

Grizzel, Travis, “Closed-loop cooling in Oracle AI data centers,” Blog, Oracle (Feb. 9, 2026).

Ipsos, “AI data centers are unpopular with most Americans,” Ipsos (May 8, 2026).

Jones, Jeffrey M., “Americans Oppose AI Data Centers in Their Area,” News, Gallup (May 13, 2026).

Katakam, Vishnu Sree Shanthanu, Mariam Arzumanyan, Ning Lin, and Vaibhav Bahadur, “System-scale design and analysis of desalination systems for meeting water needs of data centers,” Water Research (2026, available online, forthcoming).

Kaye, Byron, “Australia data centre firm NextDC reports rising water, energy use with profit beat,” Reuters (Aug. 27, 2026).

Lei, Nuoa, Jun Lu, Arman Shehabi, and Eric Manaset, “The water use of data center workloads: A review and assessment of key determinants,” Resources, Conservation and Recycling, 219:1 (Jun. 2025).

Meyer, Robinson, “Exclusive: 75% of Americans Now Oppose Local Data Center Development,” Daily briefing, Heatmap (Aug. 19, 2026).

NVIDIA, “GEMM Speedups Across Precision,” Transformer Engine documentation, NVIDIA (accessed Sep. 2, 2026).

Palyekar, Ananya, “ByteDance targets mega AI model that could match Mythos scale FT reports,” Reuters (Aug. 6, 2026).

Patel, Dylan and Gerald Wong, “GPT-4 Architecture, Infrastructure, Training Dataset, Costs, Vision, MoE,” Semianalysis (Jul. 10, 2023).

Priest, Judy and Steve Solomon, “Inside Microsoft’s two-decade push to cut water intensity while scaling for growth,” Official Microsoft Blog, Microsoft (Jun. 24, 2026).

Sevilla, Jaime, Tamay Besiroglu, Ben Cottier, Josh You, Edu Roldán, Pablo Villalobos, and Ege Erdil, “Can AI scaling continue through 2030?” Epoch AI (Aug. 20, 2024).

Talib, Rand and Jay Dietrich, “Dry cooling energy performance can rival evaporative cooling,” Briefing report, Uptime Institute (Apr. 24, 2026).

Tano, Ines-Noelly, Erfan Rasouli, and Vinod Narayanan, “Thermal Design and Performance Modeling of a High Compute Density Liquid Cooled Chiller Less Modular Edge Data Center,” Journal of Electronic Packaging, The American Society of Mechanical Engineers, 148:2 (Jun. 2026).

Vertiv, “Vertiv CoolChip CDU: Coolant distribution units for high-density deployments,” Product brochure, Vertiv (2026).

Volcovici, Valerie and Jason Lange, “Americans wary of AI-driven data center boom, Reuters/Ipsos poll shows,” Reuters (Jun. 11, 2026).

Appendix: 2026 US data center opinion polls

In this appendix, I highlight six large scale opinion polls from 2026 that focused on US citizen attitudes regarding data centers. Table 2 summarizes these polls.

Appendix: Tokens and FLOPs as measures of computational intensity

In an AI and large language model (LLM) setting, a token represents a basic unit of text that an LLM processes. For example, a prompt given to an AI model asking, “What is a data center?” would likely be six tokens: “What”, “is”, “a”, “data”, “center”, “?”. These tokens are the inputs into an LLM, and then the LLM processes those tokens through its trained model with N parameters in order to generate an answer. This process of taking tokens as inputs and using a trained LLM to create a response is called inference.

One disadvantage of using tokens as a measure of computational intensity is that the amount of work the computational system must do to process a given number of tokens depends on the size of the underlying LLM in terms of the number of its model parameters N.

Take as an example Meta’s Llama 3.3 70B model with approximately 70 billion parameters (N=7.0 × 10¹⁰).13 For this model, the floating point operations per token for inference using the model would be about 1.4 × 10¹¹ FLOPs/token (2 × 7.0 x 1010 = 1.4 × 10¹¹). But it is estimated that Anthropic’s Fable 5 model has around 5 trillion parameters (1.0 × 10¹³ FLOPs/token) and OpenAI’s GPT-4 has about 1.8 trillion total parameters (3.6 × 10¹² FLOPs/token).14

Because the computational intensity of performing inference on a token varies by more than two orders of magnitude based on model characteristics, a more objective unit of computational intensity is the floating point operation or FLOP. A FLOP is one arithmetic operation performed on numbers represented in floating-point format. Floating point numbers are essentially the computer equivalent of scientific notation (e.g., 1.7539 × 10¹²). There exist many computational operations that are not FLOPs, but the FLOP is a great metric of computational intensity in AI and high performance computing because most of these computational processes are represented by FLOPs.

Examples of computational processes that are not FLOPs include the following:

  • Integer arithmetic: addition, multiplication, division on integers
  • Logical operations: AND, OR, XOR, NOT
  • Comparisons: greater than, equal to, etc.
  • Memory operations: loading data from memory and storing results
  • Data movement: moving information among registers, cache, RAM, GPUs, or machines
  • Branching/control flow: deciding which instruction to execute next
  • Communication: transferring data between GPUs or nodes
  • Specialized operations: encryption, compression, tensor operations, database lookups

FLOPs are an excellent common metric for compute-intensive numerical workloads, including AI and traditional scientific high performance computing (HPC), but they are not a universal unit of computation. For forecasting data-center electricity demand, joules per useful FLOP is useful but incomplete because memory movement, networking, utilization, and other non-FLOP work can be increasingly important.

As I describe in Section 4, both Epoch AI (2026) and NVIDIA (2026) are projecting growth in computational efficiency between 2.2-4.7 times between 2027 and 2030. Importantly, these increases in computational efficiency are not coming from transistor scaling alone. The efficiency improvements also come from the following areas of innovation:

  • Lower-precision arithmetic
  • Chiplets and packaging
  • Much higher-bandwidth memory
  • Moving less data
  • Better GPU interconnects
  • Specialized matrix hardware
  • Higher utilization
  • Rack-level power optimization
  • Software/compiler improvements
  • Co-designing models around the hardware

[1] See Table 3 in “Appendix: 2026 US data center opinion polls”. Sources for these polls are Jones (2026), Ipsos (2026), Volcovici and Lange (2026), De Pinto (2026), APPC (2026), and Meyer (2026).

[2] See Katakam, et al (2026).

[3] See Priest and Solomon (2026).

[4] See Davies (2026).

[5] See Grizzel (2026).

[6] See Kaye (2026).

[7] See Lei, et al (2025).

[8] Tano, et al (2026) test the cooling workflow direct-to-chip cold plates → a single liquid loop → microchannel dry cooler → ambient air. At 40°C outdoor temperature, cooling electricity could be only 2.1% of compute power, and optimized configurations fell below 1%. That is remarkably close to thermodynamically “free” cooling compared with older refrigeration systems. See also summary here.

[9] See Tano, et al (2026).

[10] See Talib and Dietrich (2026).

[11] See “Appendix: Tokens and FLOPs as measures of computational intensity”.

[12] Sevilla, et al (2024) estimated that the move to FP8 (8-bit precision) training from the current FP16 (16-bit precision) training will give an approximate 2 times increase in power efficiency. But current frontier model training is happening at mixed precision across FP32, FP16, and FP8. See NVIDIA (2016). So this 2 times estimate from Sevilla, et al (2024) is likely an upper bound. On the other hand, AMD (2026) reported they had a 4 times increase in computational efficiency from 2024 to 2026. And their goal for 2030 is 20 times increase in rack-scale efficiency.

[13] Meta’s Llama 3.3 70B model is open source and available through the Hugging Face web platform at https://huggingface.co/meta-llama/Llama-3.3-70B-Instruct.

[14] See Palyekar (2026) for the estimate that Anthropic’s Fable 5 has approximately 5 trillion parameters. And see Patel and Wong (2023) for the estimate that OpenAI’s GPT-4 has 1.8 trillion parameters.

Custom Fields

authors
hook
Water is no longer a primary resource constraint for building data center IT infrastructure. But increasing efficiency in water use is leading to higher electricity demand. And electricity remains currently the main resource constraint on data centers.
topic
  • Energy
  • Technology
technology_subtopic
  • Artificial intelligence
social_image
article
false
include_in_hero_section
false
category
Articles
article_view
article content only
hide_from_our_work
false
evergy_subtopic
—
Article

Bad Bunny and the Billion-Dollar Drumbeat

Read this post on John’s Substack: Creative Frontiers.

The Monster

Cleveland “Clevie” Browne was hanging out at the Mixing Lab Recording Studio in Kingston, Jamaica, when something caught his eye. Always looking for interesting ways to “create new things,” he noticed a pair of timbale drums sitting in the corner.

He dragged them out, set them up, and asked his musical partner, Wycliffe “Steely” Johnson, to record while he “explored the studio space.”

The result felt right for a track they had been working on called “Fish Market.” Today it’s more commonly known as the “Dembow” riddim, and you can hear its heartbeat in at least 1,800 different songs. Seriously.

Because of that staggering ubiquity, Clevie and the estate of Steely, who died in Kingston in 2009, are currently suing a laundry list of global music icons, including Bad Bunny, Justin Bieber, and Pitbull, for copyright infringement. Every single one of them, the lawsuit claims, built a hit on top of Clevie’s old timbales.

In court, Bad Bunny’s lawyers contested the claim of ownership. They called the Dembow riddim a “Frankenstein,” a beat stitched together from different artists’ separate tracks over the years. No single song, they argued, actually contains all the elements that Clevie and Steely are trying to fence off as their property.

It’s a clever legal defense, but it accidentally forces a much more dangerous question about music and ownership, and what happens when you try to cram a vibrant culture into a 250-year-old legal filing cabinet.

The Riddim

If you aren’t that familiar with reggae and dancehall music, it helps to understand the phenomenon of the “riddim.”

A riddim is essentially a disembodied groove. It’s an instrumental accompaniment, typically built around a heavy drum and bass pattern. But it’s released as just that, an independent foundation. The entire point of a riddim is for others to build on top of it. So, a single riddim might serve as the sonic chassis for dozens of different vocal tracks, each released as its own song.

This communal approach to music making dates back to 1950s Jamaica, when the culture was rooted in outdoor sound systems rather than live bands. DJs would each spin the same tracks, and by the 1960s, they were shouting and toasting over them live. By the 1980s, this formula of a booming riddim paired with a fresh vocal overlay, had become a dominant form of Jamaican music. (It also migrated to the Bronx, where Jamaican immigrants like DJ Kool Herc used the same techniques to lay the foundation for global hip-hop.)

But, the crucial thing to understand is the autonomy of a riddim. Each was never meant to be a finished, walled-off product guarded by lawyers. It was an open-source seed meant to spawn a garden of variations.

And because Jamaica didn’t adopt formal copyright laws until 1993, this collaborative tradition evolved into a deeply entrenched way of life. So, when a fresh riddim would hit the streets in the 80s, it was grabbed, chopped, and adopted by countless artists, exactly as God and the DJs intended.

The Mutation

Clevie and Steely’s particular groove began its journey on the B-side of a 1990 track. It was a raw instrumental, driven by Clevie’s “old snare and kick drum,” layered with Steely’s synthesized flavor. And it was an instant hit, quickly licensed and laid down as the backbone for Shabba Ranks’ massive 1990 anthem, “Dem Bow.”

From there, the riddim became an unstoppable game of musical telephone.

It traveled to a studio in Long Island, where it was rebuilt by Jamaican musician Dennis “The Menace” Thompson. A Panamanian vocalist, Nando Boom, threw a Spanish translation over the top. Then, two NYC-based Jamaican DJs heard it, chopped it up, and recorded their own single over it, “Pounder.” And, they also released their instrumental version, the riddim, on the B-side.

This mutated form of the riddim was now in the wild. Throughout the 90s, it was chopped up and laid down in song after song. In fact, it was so foundational that the entire genre became known as Dembow.

Then, traveling on dubbed cassettes and scratched CDs, the Dembow riddim finally made its way to Puerto Rico, where it became the instrumental bedrock for roughly three-quarters of all reggaeton music.

By 2004, reggaeton was debuting at No. 1 on the top Latin albums chart with Daddy Yankee’s Barrio Fino. Humming behind it all was the Dembow riddim that began in Clevie and Steely’s studio. And today, it sits underneath the catalog of Bad Bunny, the most streamed male artist in history.

The Disparity

The riddim that Clevie and Steely built in 1989 seeded a genre that today is one of the most commercially successful musical traditions on earth. At the helm is Bad Bunny, a man who literally charters Airbus A380 super-jumbo jets for global stadium tours. And along the way, the three major labels have collected hundreds of millions, if not billions, of dollars from the riddims of reggaeton.

Meanwhile Clevie, now in his late 60s, watches it all happen from a distance.

His lawsuit is understandable. You certainly can’t blame a guy for wanting a piece of the empire he helped build. Steely’s estate and Clevie have named over 150 artists who they claim “never sought or obtained a license, authorization, or consent” to use their music. We own the riddim, they argue, so pay up.

The U.S. District Judge on the case, Andre Birotte, isn’t so sure. Faced with musicologists firing highly technical volleys back and forth, he denied a judgment and is instead sending the whole mess to a jury.

Soon, a dozen ordinary citizens, people who probably just wanted to get out of jury duty to go to Applebee’s, will be left to determine the ontological nature of a groove.

The Mismatch

The defense argues that the Dembow riddim is a “Frankenstein” work, a composite constructed from separate expressions over years of mutation. There is no distinct, singular expression to copyright, they claim.

As a legal argument it lands, but it also exposes a much deeper, structural incongruity.

As the legal scholar Olufunmilayo Arewa has documented, there is a profound bias at the heart of U.S. copyright law. Copyright was built for literature, not music. You can write literature down with precision. But with music, ink and paper are tragically inadequate. Certainly, you can depict the basic notes of the melody and harmony on sheet music, but that misses the timbre, groove, and performance. And it is precisely those elements that sit at the core of the African and African-diaspora musical traditions.

Compounding this, copyright crystallized during the Romantic era, when Western cultural elites were busy elevating classical music as the gold standard of authentic creativity. They sanctified the myth of individual genius and original expression, while vilifying “borrowing” as a lower art form.

The irony, of course, is that the classical tradition was built on borrowing. Bach did it frequently. Handel practically made it an Olympic sport. But, that history was sanitized, and borrowing became legally stigmatized as the stuff of “lower” music forms (blues, jazz, gospel, hip hop, reggae, dancehall). You know, the traditions built on borrowing as positive creativity and on performance and rhythm as originality.

So, while most of music is structurally communal, we are left with a copyright system obsessed with individual authorship and rooted in 18th century printed sheet music. It simply doesn’t fit.

Which brings us back to Frankenstein. The Dembow riddim is an assemblage because it was always meant to be an assemblage. It evolved through different hands, different studios, and different islands. Western copyright law primes us to hunt for a single author, but the riddim doesn’t have one. That’s not a flaw; that’s the design.

The Fence

None of this is Clevie’s fault. He built something truly remarkable, watched it spawn a billion-dollar global industry, and received almost nothing for it. His lawsuit is what justice looks like when the only instrument available is a giant, litigious fence.

But what would a legal victory actually mean?

It means that the next kid in Kingston, San Juan, or the Bronx who wants to build on the Dembow riddim, will have to pay up front. The raw materials of culture will only be available to those who can afford the licensing fees.

And so, the instrument of justice becomes an instrument of privilege and exclusion.

The jury hasn’t spoken yet. When they do, they won’t just decide who gets a royalty check for a groove recorded in 1989. They’ll decide whether there’s still a common space for emerging artists to explore, or if the gatekeepers have fenced off the beat.

Custom Fields

authors
hook
A dangerous question about music and ownership, and what happens when you try to cram a vibrant culture into a 250-year-old legal filing cabinet.
topic
  • Creative Frontiers
technology_subtopic
—
social_image
article
false
include_in_hero_section
false
category
Articles
article_view
article content only
hide_from_our_work
false
Team Member

Mike Anderson

Custom Fields

is_displayed
true
display_order
—
name
Mike Anderson
position
Senior Fellow for AI Policy
image
intro
Mikey Anderson is a Senior Fellow at the Abundance Institute. He believes every person should own the tools of their own intelligence, and he builds so that each generation inherits more agency than the one before it.

He specializes in open source AI standards, agent interoperability, and decentralized infrastructure. In 2023, as federal action raised the prospect that independent, open-weight AI could be regulated out of existence, Mikey organized more than sixty organizations into the Independent AI Institute—a coalition built on the premise that the surest defense of open AI are working standards everyone can adopt without permission. That bet has held: the open agent harnesses and protocols now becoming the norm, from Open Claw to Hermes, run on the pattern the coalition set out to establish. He continues to contribute to open source projects for private, local AI that runs on hardware people own. He is currently a principal at the Movement Institute.
featured_publications
false
Person

Mike Anderson

Custom Fields

name
Mike Anderson
Team Member

Jesse Bryan

Custom Fields

is_displayed
true
display_order
—
name
Jesse Bryan
position
Director of Creative Strategy
image
intro
Jesse Bryan founded Belief Agency, a full-service creative and marketing agency in Seattle, and served as its CEO for 13 years before exiting. During that time he partnered with Microsoft, Amazon, Starbucks, and the Seahawks on some of their biggest challenges. He also works at the intersection of storytelling and decentralized AI, using narrative craft to make emerging technology more accessible and human-centered. His approach: apply the oldest technology our species has—story structure—to solve today’s hardest problems.
person
Jesse Bryan
featured_publications
false
Person

Jesse Bryan

Custom Fields

name
Jesse Bryan
Fellow

Kevin Frazier

Custom Fields

is_displayed
true
display_order
3
name
Kevin Frazier
position_and_org
Director, AI Innovation & Law Program, The University of Texas at Austin School of Law
image
featured_publications
false
Article

Memo on State Policy Barriers to AI Wearable Use: Arkansas

Summary

Arkansas adopted a far-reaching privacy bill, HB 1717 (now Act 952), to significantly limit data processing activities related to teens (individuals ages 13 to 16) and children (individuals under 13). Effective July 1, 2026, the law’s applicability to teens stretches it beyond the federal equivalent–the Children’s Online Privacy Protection Act (COPPA)–and related laws in its sister states. The bill could make it impractical for teens and children to use wearable devices such as smartwatches.

Teens are especially likely to benefit from AI wearables. These devices may provide manifold educational, vocational, and mental and physical health benefits. Recent research indicates that AI wearables may help diagnose mental health issues among teens and provide novel forms of effective care, for example.

The Arkansas State Legislature should amend the act to carve out AI wearables until lawmakers have a better understanding of the costs and benefits of the law with respect to child and teen use of these novel tools.

Background on Wearables

AI wearables, like all computer systems, gather information, process it, and generate outputs. There’s an increasing diversity of such tools but they can be loosely grouped into three categories:

  1. Biometric wearables focus inward on the wearer’s body. Such devices include continuous glucose monitors, smart rings, and smartwatches. These devices gather information about the user’s body to provide activity and exercise performance metrics, support predictive health insights, and facilitate chronic disease management.
  2. Auditory wearables look outward rather than looking inward at the user’s body. Some AI wearable products—such as the now-discontinued Humane AI Pin—are worn on the body and use audio as an input, operating via voice commands without a traditional screen. Future consumer AI devices may take similar forms, including pins or necklaces. These are commonly labeled as auditory wearables.
  3. Visual wearables observe the world around the user. Smart glasses offered by companies such as Ray-Ban Meta and Envision are a prime example of this kind of wearable. These tools often feature one or more integrated cameras and a small screen visible only to the user.

Read more from the Abundance Institute on the state wearable policy landscape here.

Reforming Act 952

Background: Lawmakers at the state and federal level have long sought to shield younger Americans from harmful or privacy-infringing experiences. Congress enacted COPPA in 1998 to do so. Arkansas legislators acted on a similar impulse in 2025 in passing HB 1717. The law received bipartisan support, due to a general concern that the federal government was unlikely to pass similar legislation to account for new online threats to the informational autonomy of younger residents.

The law’s core obligations track COPPA and its proposed federal expansion. Operators may not collect the personal information of children or teens for purposes of targeted advertising. They must obtain verifiable consent before collecting personal information–from a parent for children, from either the teen or a parent for teens. They must provide clear notice of their data practices, honor deletion and correction requests, limit collection and retention to what a given service requires, and maintain reasonable security. The Attorney General holds exclusive enforcement authority. There is no private right of action.

Several of these mandates pose little burden to AI wearables. The targeted advertising ban, for instance, may not be relevant to many AI wearable companies. The regulatory troubles may lie elsewhere. Data minimization and retention limits collide with always-on biometric streams whose diagnostic value depends on longitudinal records. And deletion rights raise an unresolved question about personal information embedded in trained AI models.

Policy Recommendations

  1. Change the definitions of “mobile application,” “online application,” and “operator”: Act 952 targets the data practices of mobile applications, defined as “a software program that runs on the operating system of (i) a cellular phone, (ii) a tablet computer; or, (iii) a similar portable computing device that transmits data over a wireless connection.” Services or applications “offered via a connected device” are also included. Online applications include “Internet-connected software program[s].” An operator is any entity that makes a mobile application or online application commercially available.

    An AI wearable company is likely to fall within either of these broad definitions of applications and, therefore, qualify as an operator covered by the law. It’s unclear that state legislators intended for that to be the case.

    AI wearables present a different profile of risks and benefits to teens and minors than the social media sites that were clearly the primary, if not exclusive, targets of state legislators.

    In many cases, for example, AI wearables do not include the sorts of features that have drawn the regulatory scrutiny of some actors–continuous scrolling, excessive sharing with third parties of intimate personal information, and the manipulation of content to present a false or inaccurate depiction of reality, to name a few. Smartwatches, for example, may have few to no functionalities that are designed to maximize user engagement with a broader network.

    Until the pros and cons of AI wearables on the mental and physical health of teens are better understood, the state legislature should explicitly carve such tools out of the aforementioned definitions. They may do so on a provisional basis of a year and contingent upon the AI wearable tool not bearing any of the features that led to this legislation in the first place.
  2. Amend the definition of “personal information”: Personal information is broadly defined to include a range of terms, including “information linked or reasonably linkable to a child or teen.” The law excludes certain kinds of personal information that is collected pursuant to clear notice, in line with specific deletion and retention requirements, and under a restrictive purpose limitation.

    The data collection requirements of AI wearables are extensive by design. Absent the ongoing collection of personal information, such as “gait,” their utility may be significantly reduced. Yet, given that such information is generally not intended to be shared with third parties or otherwise used in a social context, it is of a different nature than the information collected by ad or social media platforms, for instance.

    Legislators should therefore study how best to carve out personal information collected by AI wearables from this definition. This clarity will avoid the risk of unnecessarily putting AI wearables on the same regulatory track as social media platforms and related entities.
  3. Clarify what it means for a service to be “directed at” children or teens and when an operator has “actual knowledge”: Many of Act 952’s provisions turn on whether the operator maintains a service that is “directed at” children or teens. This ambiguous qualification creates an unproductive guessing game as to whether a company needs to substantially change its operations to comply with Act 952.

    The Act’s second trigger—”actual knowledge”—is equally undefined. Does a birthdate entered at account setup suffice? A device purchased on a family plan? A parent pairing a child’s watch to their own phone? Observers expect the Attorney General to borrow the FTC’s COPPA criteria in answering these questions. Expectation, however, is not guidance.

    Minimally, the state legislature should direct the Attorney General to provide guidance on these threshold questions as soon as possible. The “directed at” qualification has been used in other contexts but failed to provide a clear conception of its reach. The FTC, for example, applies a “totality-of-the-circumstances” inquiry to determine if a website is directed at minors under COPPA. This open-ended inquiry does little to help entities structure their products in a way that may or may not be within the intended scope of the law. In fact, it has deterred the creation of child-friendly or family friendly content, as the surest way to ensure your product doesn’t risk COPPA violations is to make the content adult-directed.

Upshot

A teen in rural Arkansas with limited access to mental health care may benefit most from the very tools Act 952 now sweeps into its scope. Lawmakers had good reason to act, and the bipartisan support behind the bill reflects a real concern about online threats to younger residents. Yet the technical features of services that drove that concern are largely absent from today’s AI wearables. The three reforms above would preserve the law’s protective core while keeping it from foreclosing devices that may improve the health, education, and economic prospects of the state’s youngest residents. Critically, none of these changes asks the legislature to abandon its caution or stop monitoring the well-being of Arkansas’s young residents. Each instead ensures the law’s mandates are calibrated to specific risks—and leaves room to revisit the question once the legislature has a better understanding of the policy landscape.

Custom Fields

hook
A teen in rural Arkansas with limited access to mental health care may benefit most from the very tools Act 952 now sweeps into its scope. Lawmakers had good reason to act, and the bipartisan support behind the bill reflects a real concern about online threats to younger residents. Yet the technical features of services that drove that concern are largely absent from today's AI wearables.
article
https://www.abundance.institute/wp-content/uploads/2026/08/21064824/arkansas-wearables-brief.pdf
include_in_hero_section
false
category
Articles
topic
  • Technology
technology_subtopic
  • Artificial intelligence
article_view
article content only
social_image
hide_from_our_work
false
Article

Memo on State Policy Barriers to AI Wearable Use: Louisiana

Summary

Louisiana legislators passed the Louisiana Data Privacy Act (LDPA), SB 386, in 2026. When the law goes into effect in 2027 it will significantly complicate the regulatory landscape for AI wearable companies. Imprecise coverage thresholds may impose the heaviest burdens on responsible companies while letting those least likely to maintain robust safety checks escape the LDPA’s reach entirely. Additionally, the law imposes arbitrary barriers on data collection that may undermine the utility of AI wearables for Louisianans who stand to benefit from these innovations. The result is a regulatory climate that favors the adoption of less safe and less efficacious AI wearables.

Lawmakers interested in helping their constituents gain access to these transformative tools should consider various amendments.

Background on Wearables

AI wearables, like all computer systems, gather information, process it, and generate outputs. There’s an increasing diversity of such tools but they can be loosely grouped into three categories:

  1. Biometric wearables focus inward on the wearer’s body. Such devices include continuous glucose monitors, smart rings, and smartwatches. These devices gather information about the user’s body to provide activity and exercise performance metrics, support predictive health insights, and facilitate chronic disease management.
  2. Auditory wearables look outward rather than looking inward at the user’s body. Some AI wearable products—such as the now-discontinued Humane AI Pin—are worn on the body and use audio as an input, operating via voice commands without a traditional screen. Future consumer AI devices may take similar forms, including pins or necklaces. These are commonly labeled as auditory wearables.
  3. Visual wearables observe the world around the user. Smart glasses offered by companies such as Ray-Ban Meta and Envision are a prime example of this kind of wearable. These tools often feature one or more integrated cameras and a small screen visible only to the user.

Read more from the Abundance Institute on the state wearable policy landscape here.

Reforming The LDPA

Background: The LDPA replicates privacy laws enacted in other states and includes some of the common faults with those laws.

Nearly half of US states have enacted a variant of a common template for comprehensive privacy law. This template, first enacted by California as the California Consumer Privacy Act (CCPA), was developed during an earlier technological era. The CCPA was enacted in 2018, primarily to address social media and internet concerns. Generative AI has since transformed the landscape.

How this type of privacy law clashes with AI wearables: The technological shifts that have transpired in the eight years since the CCPA was enacted have changed the costs and benefits of various data collection practices. Advances in AI, especially in generative AI, have resulted in tools, such as AI wearables, that drastically improve the quality of life for users.

Advances made possible by wearables, such as helping users see, operate more safely at work, and track bodily functions, depend on AI wearable companies being able to engage in a wide range of data processing activities. The development of AI wearables, as with other AI tools built on modern AI training tactics, requires vast troves of high-quality data.

Absent representative data, AI tools may not work as well for individuals of diverse backgrounds. This is because the underlying AI model will not have been trained on relevant information; this shortcoming is somewhat akin to asking a teenage driver who learned to drive in Southern California to navigate a snow storm in Montana. Data privacy laws that fail to account for this important, novel use of data risk replicating already documented instances of new technological advances benefiting certain communities more than others.

Vague and excessive data collection, usage, and storage limitations also invite unintended, negative consequences. Limits on those data activities can make AI wearables less useful. For example, prohibiting AI-equipped glasses from retaining personalization data could diminish the otherwise transformative impact of AI-equipped glasses for members of the visually impaired community.

Policy Recommendations

  1. Consider a exemption for AI wearable companies: The LDPA applies to entities doing business in Louisiana that satisfy one or more of the following criteria: (1) annual gross revenues of more than $25 million; (2) engaging in at least one of many of personal information data processing activities for a commercial purpose of 75,000 or more consumers, households, or devices; or (3) deriving at least half of annual revenues from the sale of consumers’ personal information.

    This approach may drag small AI wearable companies into the regulation and expose them to regulatory expenses that are comparatively de minimis for larger firms. Lawmakers may want to consider an exemption that allows smaller firms to operate provisionally under a less burdensome set of requirements. More generally, it’s critical that lawmakers realize that metrics based on ad-tech business practices may not align well with the hardware tech sector.
  2. Provide guidance around the general data processing limitation: AI wearable companies must limit the collection of personal information to what is “adequate, relevant, and reasonably necessary” under the LDPA. This well-intentioned limitation will likely chill data practices that may improve AI wearables both in general thanks to the collection of more representative and diverse data as well as in individual use cases by virtue of identifying more unique aspects of a user’s preferences and needs.

    Minimally, Louisiana regulators should provide more granular guidance as to how these limitations will apply in particular instances of data collection. State legislators may also want to consider safe harbor provisions as well as a permanent cure period that ensures companies that attempt to comply with the spirit of this prohibition are not excessively punished. This recommendation is explored further below.
  3. Update consent requirements: The LDPA mandates that an AI wearable company receive the consent of the user prior to collecting sensitive information. Again, this is a well-intentioned effort to safeguard user autonomy. However, the law’s mandates stretch too far in the context of AI wearables.

    Sensitive information is defined as “personal data revealing racial or ethnic origin, religious beliefs, mental or physical health diagnosis, sexuality, or citizenship or immigration status,” as well as “genetic or biometric data that is processed for the purpose of uniquely identifying an individual.” The Act specifies that user consent is provided when the user takes a “clear affirmative act signifying a consumer’s freely given, specific, informed, and unambiguous agreement” to the relevant data processing activity. The LDPA explicitly forecloses “[a]cceptance in a general or broad terms of use or similar document that contains descriptions of personal data processing along with other, unrelated information.”

    Some of the most important uses of AI wearables involve exposure to and potential processing of sensitive information. Compliance with the LDPA’s consent requirements may therefore involve repeatedly and serially prompting users to consent to data processing activities.

    These pervasive reminders may cause users to become numb to what is intended to be a thoughtful and intentional process. Other users may forgo use of AI wearables to avoid the constant consent prompts. In either instance, the net result is not the outcome aspired to by state legislators.

    This likely shortcoming justifies amendment to the LDPA. Louisiana is home to well more than 150,000 visually impaired individuals and others who stand to benefit significantly from AI wearables. Consent requirements designed for prior generations of technologies should not block their ability to make deliberate and intended use of AI wearables.
  4. Clarify the extent of the right to delete information: LDPA authorizes users to request that a company delete their personal information. Companies must respond to such requests in a timely fashion (45 calendar days). Whether and to what extent the right applies to personal data relied on to train an AI model and, therefore, embedded within a model’s weights is an open question.

    From a technical standpoint, personal data is not stored as a standalone, accessible data unit within a model. User or regulator demands that personal data be “deleted” from trained AI models are thus technically difficult (if not impossible) and do not improve user privacy.

    Regulators should rapidly confirm that data deletion rights do not require the modification, retraining, or deletion of AI models trained on user data.
  5. Provide for a permanent cure period: The Attorney General treats violations of the LDPA as unfair and deceptive trade practices. There is no private right of action. There is a thirty-day right to cure that sunsets on July 31, 2027.

    The legislature should seriously weigh making permanent the thirty-day cure period, especially with respect to novel technologies that do not fit neatly within the technological assumptions held by the authors of the LDPA.

Upshot

Louisiana set out to advance the well-being of its residents but instead built a privacy regime that may leave Louisiana residents unable to enjoy the full benefits of AI wearables. The LDPA borrows a template drafted before generative AI existed, and that mismatch now shapes outcomes the legislature never intended. Its ad-tech-based thresholds do not map neatly onto hardware companies, while its data minimization and consent rules fall hardest on the larger labs best positioned to build safe, powerful, representative tools. The visually impaired Louisianans who stand to gain the most from AI glasses (among many other communities) are precisely the users a consent-prompt treadmill will frustrate or drive away.

Regulators can and should address these flaws. Clear guidance on the minimization standard, an explicit answer that the right to deletion does not compel model retraining, and a permanent cure period for novel technologies would align the law with the benefits it claims to protect.

In short: a privacy law worth enacting should make safe and effective wearables easier to adopt, not harder.

Custom Fields

hook
Louisiana set out to advance the well-being of its residents but instead built a privacy regime that may leave Louisiana residents unable to enjoy the full benefits of AI wearables. The LDPA borrows a template drafted before generative AI existed, and that mismatch now shapes outcomes the legislature never intended.
article
https://www.abundance.institute/wp-content/uploads/2026/08/21064349/louiaiana-wearables-brief.pdf
include_in_hero_section
false
category
Articles
topic
  • Technology
article_view
article content only
social_image
hide_from_our_work
false
technology_subtopic
  • Artificial intelligence
Team Member

Haley Larsen

Custom Fields

is_displayed
true
intro
Haley Larsen is the Director of Events at the Abundance Institute. She hopes the future is full of gatherings where new ideas are sparked, relationships are built, and meaningful collaborations take shape.

Before joining Abundance Institute, Haley served as Director of Events at the Mercatus Center, where she shaped the organization’s events strategy and portfolio. She joined Mercatus as an Events Assistant in 2017 and rose to lead the department. She has led events in India, Ghana, Denmark, Ireland, and the United States, bringing together thinkers and doers from around the world. Haley holds a B.A. in journalism and communications from Utah State University.

Online @ [LinkedIn](https://www.linkedin.com/in/haley-larsen-b88551129/)
name
Haley Larsen
position
Director of Events
image
person
Haley Larsen
display_order
16
featured_publications
false
Person

Haley Larsen

Custom Fields

name
Haley Larsen
Article

How states can facilitate an AI ecosystem

Originally published in Mountain States Policy Center.

Policymakers have an important opportunity to move from justified skepticism of Artificial Intelligence (AI) to pragmatic experimentation with its use. Many of the shortcomings associated with AI–high rates of hallucination, excessive sycophancy, and opaque processes–will be less prevalent in the near future as the models learn and grow.

AI labs are developing tools that can autonomously complete complex tasks with high rates of accuracy and auditability. All signs suggest that these tools will only become more capable with each passing day. As these exponential gains continue, pressure will mount on lawmakers to help existing institutions adapt and to support the creation of new businesses, programs, and regulatory frameworks.

Those states that deliberately respond to that pressure have brighter futures ahead. Recent data indicates that young, fast-growing firms continue to create new jobs. AI pilots demonstrate that this technology can streamline and improve government services. Trials of AI tools in schools show that with the right scaffolding, students and educators can benefit tremendously from AI support. States that adopt a regulatory ecosystem supportive of those activities will draw new investments, new residents, and new opportunities.

AI is only as useful as the data used to develop and apply models. Policymakers can assist students and educators, startups and nonprofits, and government offices in making full use of AI by developing robust data hubs. As of now, state data is often fragmented and maintained in a format that’s ill-suited for AI development and deployment.

Lawmakers should consider the following actions to ensure their data is being put to its full use:

  1. Mandate that agencies improve their data collection and storage practices;
  2. Create or further support data hubs that house high-quality datasets on pressing public policy issues such as education, healthcare, and workforce training;
  3. Establish protocols for making that data available to third parties, subject to privacy protections and use limitations;
  4. Investigate how to allow third parties to contribute their own data to the hub, which may require new laws or regulations specifying common definitions for data and standardized data collection practices; and
  5. Evaluate processes by which any collected data could be shared with other states developing similar data hubs.

The AI tools made possible by better data collection and distribution will contribute to the general welfare if the state has the workforce in place to put these tools to use. Too few people have a meaningful understanding of the latest AI tools. They may use AI for basic tasks but have yet to explore more novel and transformational use cases. Policymakers can increase the odds of the best AI tools being used by cultivating and attracting AI talent. Several actions may assist with that work:

  1. Launch or otherwise support the creation of a general AI training corps that can teach educators, small business owners, civil society leaders, and others to learn the ins and outs of AI;
  2. Partner with existing research institutions, investor groups, and business development organizations to designate AI hubs–areas that are densely populated with nascent AI firms and educational programs–that foster information sharing and entrepreneurship; and
  3. Update existing law to reflect new labor market realities by making benefits portable and initiating a review of existing occupational licenses to assess if their scope needs to be curtailed in light of the risks and benefits posed by that gatekeeping mechanism.

The pros and cons of any AI use case are difficult to predict. Yet, fear of the unknown and a failure to appreciate the shortcomings of the status quo may cause policymakers to place unnecessarily high barriers to deployment. A failure to design pathways for AI companies to make their latest tools available may deprive residents of tools that could markedly improve their quality of life.

Delay in deployment could also cause the state’s government offices and businesses to lag behind their peers in improving existing operations and offering new goods and services. Lawmakers can establish an evidence-based approach to governing AI tool deployment and use by adopting the following policies:

  1. Build a regulatory sandbox program through which AI developers can deploy their tools subject to increased oversight, data sharing, and means for residents to share any harms or benefits;
  2. Specify priority areas for AI use, such that applicants for the regulatory sandbox with tools addressing those areas receive expedited consideration; and
  3. Start a grant program for researchers and startups to develop tools that may address those priority areas to spur in-state AI activity.

Those states that work to facilitate a functional AI ecosystem will be best positioned for efficient governance and economic success. The time to act is now.

Kevin Frazier is the Director of the AI Innovation and Law Program at the University of Texas School of Law and a Senior Fellow at the Abundance Institute. Chris Cargill is the President of Mountain States Policy Center, an independent free market think tank based in Idaho, Montana, Wyoming and Washington.

Custom Fields

authors
hook
AI labs are developing tools that can autonomously complete complex tasks with high rates of accuracy and auditability. All signs suggest that these tools will only become more capable with each passing day. As these exponential gains continue, pressure will mount on lawmakers to help existing institutions adapt and to support the creation of new businesses, programs, and regulatory frameworks. Those states that deliberately respond to that pressure have brighter futures ahead.
category
Op-eds
social_image
article
false
include_in_hero_section
false
topic
  • Technology
technology_subtopic
  • Artificial intelligence
article_view
article content only
hide_from_our_work
false
Article

Addressing the Memory Chip Affordability Challenge

Executive Summary

Supply chain shortages stood out as one of the many challenges American consumers and businesses faced during the COVID-19 pandemic. Surges in demand and supply constraints led to higher prices and shortages of toilet paper, cleaning products, and personal protective equipment (PPE). Families had more disposable income from government checks and spent less on travel and dining out, while spending more on laptops, gaming systems, home repairs, and automobiles. It quickly became evident that microchip shortages were another constraint. Inventories shrank, wait times ballooned, prices rose sharply, and downstream businesses struggled to obtain the inputs needed to produce their products.

Consequently, addressing supply chain resiliency quickly became a priority for federal and state policymakers. Policies aimed at friend-shoring chip production, increasing supply chain transparency, and improving the efficiency of production and trade. President Biden signed the CHIPS and Science Act of 2022 to incentivize more semiconductor manufacturing, research, and workforce development.

Several years later, a similar challenge is unfolding rapidly in the memory chip industry. Demand is surging, and supply bottlenecks persist. However, this time demand is driven by the rapid growth of data centers. Hyperscale data center companies are buying unprecedented quantities of the world’s most advanced memory chips. American consumers will face the same consequences: higher prices, longer wait times for products, and supply shortages that may persist for years. The memory chip imbalance is quickly becoming yet another affordability concern for households and policymakers alike.

The current memory shortage is not identical to the pandemic shock, but it has shown how supply chain bottlenecks can drive high prices and economic costs that ripple throughout the economy.

For policymakers, the overarching objective should be to increase supply, improve resilience, and lower consumer costs while preserving the price signals that drive investment, innovation, and long-term competitiveness. If Congress and the administration are concerned that AI-driven demand for high-bandwidth memory could constrain conventional DRAM supplies and raise costs for consumers and businesses in the near term, Congress should focus on improving and protecting market flexibility, ensuring transparency, and removing barriers that prevent firms from adapting to changing market conditions. Importantly, the administration should resist protectionist policies that would likely restrict supply and exacerbate price concerns, while leveraging trade discussions to expand the supply of memory for household products. In the intermediate to long-term, permitting reform will help domestic manufacturers invest and build efficiently and predictably.

What Are Memory Chips And How Are They Used?

Traditional memory chips, known as DRAM (dynamic random-access memory), are used in everything from laptops and smartphones to industrial equipment and automobiles. DRAM temporarily stores information that a processor is actively using, whether in a web browser, an app on your phone, a video game, or during data center processing. NAND memory provides long-term storage in devices such as solid-state drives, USB flash drives, smartphones (e.g., stored photos), and data center storage systems.

While we typically think of memory in terms of computers and phones, memory is embedded throughout the economy. Among the products Americans rely on daily and the technologies critical to the economy and national defense, memory chips are used in:

  • Household appliances such as refrigerators, dishwashers, washing machines, dryers, and smart thermostats.
  • Electronics, including laptops, smartphones, tablets, computers, gaming consoles, home security systems, smart televisions, streaming devices, and connected speakers.
  • Modern vehicles across infotainment, driver assistance, backup cameras, battery management, telematics, and display systems.
  • MRI systems, CT scanners, ultrasound machines, patient monitors, infusion pumps, diagnostic equipment, wearable health technologies, and hospital networking infrastructure all rely on semiconductors and memory.
  • Advanced radar systems, missile defense platforms, intelligence and surveillance equipment, secure communications networks, autonomous systems, and military data centers.
  • Broadband networks, including routers, modems, switches, optical equipment, wireless infrastructure, and data-center networking products.
  • Financial services such as payment processors, stock exchanges, banking, ATMs, and digital payment platforms.
  • Energy, including grid control centers, utility operations, pipeline monitoring, power plant controls, smart meters, and battery storage systems.
  • Transportation networks such as air traffic control, rail signaling, distribution centers, and logistics networks.
  • Agricultural technologies such as precision agriculture, GPS-guided tractors, autonomous equipment, irrigation controls, yield monitoring, drones, and farm management software.

As more advanced technology has been integrated into most products Americans use daily, memory chips are found in nearly every sector of the economy. This also includes the growth of artificial intelligence, which is rapidly reshaping the memory market.

AI’s Expanded Memory Chip Use

Artificial intelligence promises enormous benefits for the American economy. It will increase productivity, accelerate scientific discovery, improve logistics, strengthen energy security, and help businesses serve consumers more efficiently. However, training and running large AI models require moving enormous amounts of data between processors and memory. Data center growth has created significant demand for a more specialized memory type known as High Bandwidth Memory (HBM). Unlike conventional DRAM, which sits on a circuit board, HBM stacks multiple DRAM layers vertically and places them extremely close to advanced processors. The result is dramatically faster data transfer speeds and lower power consumption.1

For context, a single data center chip has 6 times as many gigabytes as a computer and 24 times as many as a smartphone.2 Therefore, a single AI server can consume as much memory as hundreds of laptops or thousands of simpler connected devices.

Not only is DRAM in greater demand, but data center companies are also paying substantial premiums and signing multiyear contracts to meet their short-term memory needs. Unsurprisingly, the memory chip industry has shifted toward higher-margin HBM manufacturing. Price signals are guiding DRAM suppliers as they allocate supply to its highest-value use. According to Bloomberg Intelligence, AI accounted for 32 percent of global DRAM consumption in 2020. That share grew to 50 percent by 2025 and is expected to reach 60 percent by 2030.3

Other estimates place AI’s share of the memory market even higher. According to reports citing IDC research and industry analysts, data centers are projected to account for roughly 70 percent of memory-chip demand in 2026, reflecting the rapid growth of AI infrastructure.4

Demand has pushed prices markedly higher. TrendForce’s February 2026 forecast projected that Q1 conventional DRAM contract prices would rise 90–95 percent, and its March update forecast another 58–63 percent jump in Q2, as suppliers continued to shift capacity toward AI and server applications.5 In some cases, spot prices for short-term memory have increased by 700 percent over the past year.6 The Wall Street Journal recently reported that Micron’s contract prices for one data center memory chip rose from $350 to $1,300 over the past year, a 271 percent increase.7 With memory demand changing rapidly, the memory industry’s structure and complexity make it difficult for markets to adjust accordingly.

The Challenges Of A Market Response And Barriers To Entry

In some respects, the memory chip market is functioning as expected. AI companies are willing to pay more for HBM, and manufacturers are rationally responding to price signals. Capacity expansion is underway, and DRAM consumers are absorbing higher costs, cutting production, or passing them on to consumers. In fact, some memory production is already shifting from planned HBM output to DRAM production due to recent higher profit margins in general-purpose memory.8 Nevertheless, shortages will likely persist, and new fabs and substitute technologies are likely years away from providing meaningful relief.

The structure and intricacy of the memory market, along with the barriers to entry, make it difficult to meet rising demand quickly. DRAM manufacturing is incredibly complex. Manufacturing memory requires cutting-edge fabrication processes, advanced packaging technologies, and highly specialized equipment and engineering expertise. Consequently, the market is extremely concentrated. Three companies dominate the memory market: Micron Technology (United States), Samsung Electronics (South Korea), and SK Hynix (South Korea). Together, they account for more than 90 percent of the market. The remainder consists mostly of one Chinese company, ChangXin Memory Technologies (CXMT). Two Taiwanese companies, Nanya Technologies and Windbond Electronics, operate in a more niche market and are primarily conventional DRAM producers.

In addition to manufacturing complexity, market concentration creates its own challenges for market entry. The larger firms hold most of the world’s accumulated process knowledge, IP, and equipment relationships necessary to build out new capacity. CXMT, established in 2016, was built with massive state and municipal government support and a government-supported cluster of supply chains. Market entry by a non-state-led venture would still likely require partnering with or licensing from one of the larger incumbents.

Among those larger incumbent firms, Micron and SK Hynix are investing heavily in new U.S. memory manufacturing and packaging capacity. Still, Micron’s first Idaho DRAM fab is not expected to begin wafer output until the second half of 2027. SK Hynix’s Indiana HBM facility is not expected to begin mass production until the second half of 2028. Micron broke ground on its upstate New York facility in January, but it is not expected to begin producing memory chips until 2030. Therefore, these projects are unlikely to provide meaningful near-term relief from the current tightness in the memory market.

The Economic Impact On Consumers And The Economy

The growth of AI and data center development will have significant positive impacts on technological breakthroughs, scientific discovery, business efficiency, and economic growth. These developments can be important sources of job creation and tax revenue for counties. Many of the activities and products consumers use daily (web browsing, GPS navigation, asking a voice assistant a question, or producing and listening to a podcast) rely on AI and data centers.

However, beyond the direct costs of AI use, the AI boom also carries second-order spillover costs. Because DRAM is a direct substitute, the reallocation from DRAM to HBM shrinks the supply of memory chips. With a relatively fixed number of fabs and years-long lead times to build new ones, this diversion reduces the supply of consumer DRAM, pushing up prices for consumer products across the board. Since memory chips are used in most technologies across the economy, American families and consumers will be harmed multiple times over. The cumulative impact will be reduced supply, higher prices, and products that may have less memory than they otherwise would.

The most immediate consumer impact is likely to be felt in PCs, laptops, smartphones, tablets, and gaming devices. The research firm Gartner estimates that the combined price of DRAM and solid-state drives (SSDs) could rise by 130 percent by the end of the year, pushing PC prices up 17 percent and smartphone prices up 13 percent. Gartner also projects that higher memory costs will reduce worldwide PC shipments by 10.4 percent and smartphone shipments by 8.4 percent in 2026 compared with 2025.9

Another research firm, IDC, has an even more severe forecast for smartphones. IDC expects global smartphone shipments to decline 13.9 percent year over year in 2026 to 1.09 billion units, marking the steepest annual contraction on record.10 It cites the memory chip shortage as the primary driver, along with higher energy and transportation costs driven by the war.

Consumers of lower-end devices, such as basic tablets, PCs, and smartphones, are especially affected because memory accounts for a larger share of total costs, and that share is only growing. For PCs, the share of memory in the total bill of materials is expected to increase from 16 percent in 2025 to 23 percent. Gartner’s senior analyst Ranjit Atwal warned, “This sharp increase removes vendors’ ability to absorb costs, making low-margin entry-level laptops nonviable. Ultimately, we expect the sub-$500 entry-level PC segment will disappear by 2028.”11

Consumers may also receive lower-end products. Manufacturers could respond to higher memory costs by reducing memory capacity. A laptop that once shipped with 16 gigabytes of memory may now ship with 8 gigabytes, or a smartphone that once included 256 gigabytes of storage may now offer 128 gigabytes at a similar price point. Again, shortages that force companies and consumers to adjust or ration are the market at work. Consumers may buy phones less often or receive less memory per dollar spent, but those devices are also more capable because they can run AI.

Memory shortages will not simply raise prices for consumers buying new products. They ripple through the entire economy by extending replacement cycles, reducing product availability, increasing demand for used goods, and slowing the diffusion of newer, more productive technologies. In that sense, the economic costs can persist long after the initial supply disruption begins. When chip shortages constrained vehicle production between 2020 and 2022, consumers shifted to the used-car market, and prices increased substantially.12 Used vehicle prices rose by more than 50 percent between early 2020 and early 2022 as semiconductor shortages constrained new vehicle production and pushed consumers into the secondary market.13 AlixPartners estimated that automakers lost approximately 7.7 million vehicles in production and $210 billion in revenue worldwide.14

Similar dynamics occurred in the computer and smartphone markets as consumers delayed upgrades and increasingly relied on refurbished devices. If memory shortages raise the cost of new laptops, phones, vehicles, and other electronics, demand could again migrate into secondary markets.

While the exact impacts on different sectors of the economy and on consumers remain to be seen, industries are sounding the alarm. In a recent letter to Treasury Secretary Scott Bessent and Commerce Secretary Howard Lutnick, a wide range of businesses expressed concern about the imbalance in memory chip supply. The letter, signed by representatives of the automotive, retail, medical devices, and broadband trade associations, urged the administration to consider ways to increase supply, reduce regulatory barriers, and ease constraints on alternative sourcing.15

More broadly, it is important to weigh the consumer and broader economic benefits of increased data center development and AI. Americans derive many benefits from using AI, whether that is planning a trip better, saving time on research, being more productive at work and at home, and being more creative. More broadly, AI will help unleash innovations that make families safer, healthier, and happier. For policymakers, it is important to note that high prices and adjustments are part of how the market functions, not evidence that the market is broken. However, it is also an opportunity to improve policies and regulations on the margin to work more efficiently and respond more quickly to changing price signals.

The CHIPS And Science Act And The Current Memory Imbalance

Congress passed the CHIPS Act in August 2022, which provided $52.7 billion in grants, government-backed loans, and funding for research and development and workforce development for chip manufacturing. The law also includes a 25 percent investment tax credit for semiconductor facilities and manufacturing equipment. The full bill, including R&D authorizations, totals $280 billion.16

Policymakers primarily designed the CHIPS Act to support leading-edge logic (advanced CPUs, GPUs) and leading-edge DRAM production. The bill was less a response to pandemic-related supply chain disruptions (though that became another motivating factor) and more a push to reshore domestic semiconductor manufacturing. Because most advanced semiconductor manufacturing occurs in Taiwan, proponents deemed the subsidies necessary to diversify in case of any Chinese aggression in the region.

Critics of the bill have pointed to rent-seeking, corporate welfare, and wasteful taxpayer-funded spending.17 Even more neutral analyses have noted the costs and inefficiencies of industrial policy spending.18 President Trump has repeatedly criticized the bill as wasteful subsidies and has called on Congress to end the law.19

How does the law apply to the current memory challenges facing the economy? CHIPS dollars effectively subsidize the fixed costs of fab construction but leave the chip-production allocation decision entirely to the company. For instance, Micron has received CHIPS funding, but the incentive structure does not tie grants to the type of memory produced, so Micron can rationally take the subsidy and still shift toward HBM. In total, the three large memory makers have received more than $11.65 billion in funding, nearly one-third of the allocated CHIPS subsidies to date, though not all of the funding has gone toward DRAM production.

  • Micron ($6.44B): The bulk of this funding goes to new fab construction in New York and Idaho. An additional $275M supports the expansion of the Virginia facility.20
  • SK Hynix ($458M): The entire award is for establishing an HBM advanced packaging fabrication and R&D facility specifically for AI products. The facility will include an AI memory packaging factory, as well as advanced packaging manufacturing and R&D facilities. By design, this award does nothing to address the conventional DRAM shortage.21
  • Samsung ($4.75B): The Texas facility mainly makes logic chips (processors), not memory chips.22

A History Of Antitrust Lawsuits

Over the past two decades, antitrust lawsuits and government investigations have targeted DRAM manufacturers. Between 1998 and 2002, the world’s largest memory chip manufacturers coordinated to inflate memory chip prices artificially. They did so through a network of bilateral contacts, secret meetings, and coordinated pricing, which led U.S. businesses and, ultimately, consumers to pay more.23 The U.S. Department of Justice investigated and secured guilty pleas from several companies. Samsung paid a $300 million criminal fine, while Hynix paid a $185 million fine.24 Micron, while not convicted of the underlying price-fixing conspiracy, paid civil settlements totaling approximately $150 million across multiple cases.25

More recently, federal courts dismissed allegations that Micron, Samsung, and SK Hynix coordinated to restrict supply. A class-action lawsuit filed in 2018 against Micron, Samsung, and SK Hynix alleged that the companies collectively restricted DRAM supply beginning in 2016, driving DRAM prices up dramatically through 2018.26 The complaint cited parallel production restraint, public statements by executives, and the fact that the three firms controlled roughly 90–95 percent of the global DRAM market, with prices rising by about 350 percent.27

However, the courts ultimately rejected the case. In 2022, the Ninth Circuit affirmed the dismissal, finding that the plaintiffs had shown largely parallel conduct and similar business decisions by firms in a concentrated market, but had not produced sufficient evidence of an actual agreement among the companies to fix prices.28 The court concluded that the allegations did not plausibly establish a violation of the Sherman Act.

More recently, a class-action antitrust lawsuit filed in the U.S. District Court for the Northern District of California by a group of individuals and small businesses alleges that Samsung, SK Hynix, and Micron have colluded to fix DRAM prices and supply since 2022.29 Micron has denied the allegations and says it will contest them in court; it is too early to know whether any evidence has been established that the current memory shortages are the result of collusion. Nevertheless, the history of antitrust scrutiny in the DRAM industry underscores the importance of vigilance and transparency in a market dominated by a small number of global suppliers.

Learning A Lesson From The Data Center Blowback

The rapid backlash against data centers should serve as a warning for policymakers to get ahead of memory chip price concerns before they become a flashpoint. Concerns over electricity bills, water, and noise fueled a groundswell of opposition, even if many of those concerns were unfounded. Even so, opposition has increased significantly since the beginning of the year. A January 2026 POLITICO poll found that only 28 percent of voters opposed building a data center within three miles of their homes, while 37 percent supported it. Only a few months later, a March Gallup poll found that 71 percent of Americans objected to local construction of data centers, with 48 percent strongly opposed.30

If memory prices keep climbing and the explanation is that chipmakers are diverting chips from households to data centers, the issue risks becoming a hot-button issue that only heightens Americans’ affordability concerns. While data centers are being built across the country, the memory chip issue could have an even broader political reach, as it affects every household buying a laptop, phone, or car with embedded electronics.

None of this is an argument for banning, slowing, or delaying data center buildout or AI development. The technology’s benefits for productivity, innovation, and national competitiveness are real and worth pursuing, and reflexive obstruction would forfeit those gains. Instead, policymakers must be transparent about the tradeoffs, clearly explaining why prices are rising, who is affected, and what is being done to expand supply and ease the burden on American families and businesses.

What Should Policymakers Do Next?

In the near term and in the long run, policymakers should assess opportunities to remove frictions and improve market responses. The first step for Congress and the Trump administration is to do no harm. Mandating production levels, imposing price controls, or creating government reserves carry real risks of distorting investment signals and exacerbating market imbalances. Congress and the administration should empower the private sector to respond to price signals organically in the short and long run while exploring ways to improve market transparency. Reforms should

  1. Resist any protectionist policies that would worsen price impacts. Congress and the administration should avoid actions that would restrict global DRAM capacity and equipment, thereby further increasing costs for American buyers of laptops, phones, cars, and appliances. One harmful example is the Multilateral Alignment of Technology Controls on Hardware (MATCH) Act. The MATCH Act would impose U.S. export controls banning the sale of key semiconductor manufacturing equipment to China and threaten companies in allied nations (Japan and the Netherlands) with expanded U.S. jurisdiction if their governments fail to align with American restrictions within 150 days. The bill directly targets YMTC and CXMT, two Chinese memory chipmakers that are growing rapidly despite existing controls. By slowing CXMT’s ability to add capacity and remove additional volume, when AI-driven demand is already constraining supply, the legislation would raise prices for the same American consumers and downstream industries the bill claims to protect.

    In addition, the bill has several flaws and potential unintended consequences that could exacerbate the DRAM supply crunch. Even with an allied-facility carve-out for Korean operations in China, the bill could still indirectly tighten the global DRAM market. If export controls or strained relations with Japan and the Netherlands disrupt the flow of tools or services that Samsung and SK Hynix’s operations in China depend on, global supply could be reduced. Even a modest disruption to those fabs’ access to equipment could push prices higher well beyond China’s borders. Furthermore, the empirical record of similar export controls in the semiconductor industry has been poor, and they have not meaningfully stifled China’s ability to expand its domestic capacity. Critically, protectionism reduces the incentive to innovate, lower costs, and compete in the global market. Mark Dalton, Senior Policy Director for Technology and Innovation at the R Street Institute, noted that export controls on the semiconductor industry “have accelerated China’s progress toward strengthening its indigenous technology stack and, perhaps more importantly, they have simultaneously damaged U.S. competitiveness by reducing revenues critical to funding the high levels of research and development (R&D) that characterize the industry.” The MATCH Act risks going down a similar path, and policy should refrain from protectionism or subsidization where the industry is already a technological leader and collecting record profits.

  2. Ease constraints on memory chips, manufacturing equipment, and raw materials. Although domestic memory chip manufacturing is set to come online in the next few years, U.S. firms currently import most of their short-term memory chips, including those from Micron’s operations in Japan. These chips enter the U.S. market tariff-free, and that should remain the case. The administration should refrain from imposing trade restrictions on non-U.S.-based chip manufacturers. While certain restrictions should remain in place to address legitimate security concerns, Section 301 exclusions could increase the number of suppliers available to U.S. buyers and help lower prices during periods of tight supply. In addition to conventional DRAM, the administration should explore exclusion processes for production inputs, such as semiconductor-grade wafers, specialty gases, photoresist chemicals, manufacturing equipment, and other inputs used in DRAM manufacturing. Doing so could increase supply, improve resiliency, and help lower costs for manufacturers and consumers who rely on memory-intensive technologies. One area of opportunity is the ongoing trade talks with Seoul. Negotiations could help reduce potential disruptions to Korean-owned production in China, provide multi-year export licenses, commit a greater share of their global output to DRAM, and explore faster capacity expansion in the U.S.

  3. Direct the Federal Trade Commission (FTC) to conduct a Section 6(b) study of memory capacity allocation. The administration should direct the FTC to use its Section 6(b) authority to examine how Samsung, SK Hynix, and Micron allocate fab capacity between HBM and conventional DRAM, including whether those decisions involved communication or coordination with competitors, customers, or industry groups. Such a study would not presume wrongdoing; it would gather information, clarify market dynamics, and produce a staff report. The study could confirm that each firm is independently responding to price signals. However, because these three firms control most of the global memory supply and American buyers are already facing higher prices due to shifts in product mix, the public and policymakers need a transparent, fact-based record of how these decisions are made.

  4. Streamline opportunities for innovation, alternatives, and product substitutes. When alternative memory components or leaner hardware configurations are available, regulatory requirements governing component substitutions and product modifications can prevent manufacturers from adapting quickly. Validation, certification, and approval processes often take months or years, leaving firms tied to disrupted supply chains long after viable market alternatives exist. This challenge is particularly acute for products subject to extensive regulatory oversight, including medical devices, automobiles, communications equipment, industrial control systems, and other electronics that require certification before modified components can be deployed. In a letter to the Trump administration, industry stakeholders recommended easing constraints on alternative sourcing and product redesign during memory chip disruptions, including expedited validation and approval procedures for regulated products. The administration could advance this goal by directing agencies such as the FDA, FCC, and NHTSA to create expedited review pathways for memory-component substitutions and associated hardware, firmware, or software changes when manufacturers demonstrate a bona fide supply disruption. Federal procurement rules could similarly provide greater flexibility during supply disruptions by allowing agencies and contractors to qualify alternative suppliers, substitute functionally equivalent components, and modify technical specifications without restarting lengthy procurement or approval processes. Such an approach would preserve necessary safety and performance standards while enabling manufacturers to respond more quickly to supply shortages and changing market conditions.

Conclusion

The growing memory chip imbalance largely reflects the market’s rational response to extraordinary demand driven by data centers’ needs. Nonetheless, the impact on American families and businesses could be substantial. The COVID-era chip shortage offered a glimpse of what may be in store for consumers: higher prices and longer wait times. With policymakers hyper-focused on affordability, the chips issue will once again be front and center in Washington.

The policy response should not be to override price signals or to throw more taxpayer money at the problem, but to reduce government-imposed policies and regulations that could help expand supply and allocate more memory to products Americans rely on daily. Reforms that liberalize markets and increase transparency will best protect U.S. taxpayers and consumers.

Addendum: Case Study: Micron’s Permitting And Legal Challenges And The Need For Reform

Micron’s semiconductor manufacturing campus in Clay, New York, underscores the need for comprehensive permitting reform. The full campus will include four semiconductor fabrication facilities and attract more than $100 billion in private investment over the coming decades.31 Permitting delays, duplicative environmental reviews, and construction bottlenecks have already pushed the first fab’s opening from 2028 to 2030.32 Each year of delay leaves American households, manufacturers, and defense contractors exposed to supply imbalances. The delay stems from multiple factors, including stated worker shortages, but lengthy permitting schedules and litigious activists certainly play a role.

To be sure, the environmental review of the manufacturing facility was thorough. As with many projects, Micron’s facility faced duplicative reviews at the federal and state levels. New York State’s environmental impact statement alone reflected two and a half years of environmental review. Under the National Environmental Policy Act (NEPA), the project underwent an Environmental Impact Statement (EIS), whereas others were reviewed through a narrower Environmental Assessment.33 The project was large in scope and involved several major land-use changes, which warranted a full EIS. Nevertheless, the duplicative, expansive review and subsequent litigation demonstrate the need for a more efficient, predictable process. After multi-round public review, including public comment periods and virtual hearings, the New York State Department of Environmental Conservation issued nine environmental permits in December 2025. The Department concluded that the project’s impacts on freshwater wetlands, water quality, and endangered and threatened species could be adequately managed through protective conditions, mitigation projects, and ongoing monitoring.34 The U.S. Department of Commerce’s CHIPS Program Office, with the Army Corps of Engineers and the Environmental Protection Agency as cooperating agencies, separately issued a Record of Decision in December 2025 approving the disbursement of federal financial assistance. It found that the project’s environmental effects were reasonably foreseeable, assessable, and mitigable.35 In fact, agencies spent 612 days on a 22,000-page environmental impact study, including a 45-day public input period.36 Notably, the project has broad support from local leaders and workers eager for jobs.

Hours before the groundbreaking, Neighbors for a Better Micron and the California-based advocacy group Jobs to Move America filed a lawsuit alleging that the environmental review was rushed and that it gave inadequate time for public comment. Jobs to Move America went door-to-door and found only six residents willing to serve as plaintiffs, who together formed Neighbors for a Better Micron. According to reporting in Syracuse’s Post-Standard, “Before the suit was filed, the group had never held a meeting or a vote. Some members didn’t even know who the others were.”37 Even if construction at the Micron facility is allowed to continue, the lawsuit could void the final environmental impact statement and revoke permits.

Micron’s experience illustrates the fundamental flaws in America’s permitting process. Although well-intentioned, the permitting process has become a sprawling, duplicative system that layers reviews, invites litigation, and stretches timelines into years or even decades. The process is burdensome for project applicants and the agencies conducting the review, requiring extra paperwork, unclear procedures, and redundant efforts. Most concerning, the process creates opportunities for seemingly endless litigation. Even after completing a multi-year environmental review and major approvals, projects remain vulnerable to post-approval litigation that can create uncertainty, increase costs, and delay construction timelines.

With respect to building semiconductor facilities in the U.S., policymakers recognized that the permitting process can be improved without sacrificing environmental protection. Following the CHIPS Act, the Building Chips in America Act of 2023, signed into law by President Biden on October 2, 2024, sought to streamline federal permitting for semiconductor manufacturing projects receiving CHIPS Act support by exempting certain projects from NEPA. However, its scope is limited, applying only to projects that commenced construction before the end of 2024, that are financed via a loan rather than a grant, or for which a federal subsidy was less than 10 percent of the project’s cost. Micron’s facility does not meet any of these conditions.

As Congress explores permitting reform, it should identify opportunities to streamline reviews, reduce duplication, narrow the scope of litigation, and offer greater certainty for project developers while maintaining strong environmental safeguards. Permitting reform would not address near-term memory supply challenges, but it would provide more regulatory clarity for investments in future capacity expansion. Substantive permitting reform should create efficiencies, inject certainty, constrain frivolous litigation, and eliminate duplicative reviews. While reform of the National Environmental Policy Act receives the most attention, improvements to the Clean Water Act, the Clean Air Act, the Endangered Species Act, and the National Historic Preservation Act will ensure that permitting reform is substantial and meaningful. A full list of policy reforms to modernize America’s major environmental statutes is available in the C3 white paper, “Permitting Reform is Back On: What Should It Include?”38

Endnotes

1. Lam Blog Staff, “High Bandwidth Memory (HBM) Explained (Semi 101),” Lam Research Newsroom, September 11, 2025, https://newsroom.lamresearch.com/high-bandwidth-memory-explained-semi-101?blog=true

2. Charles-Henry Monchau, “The End of Cheap Memory: Why 2026 Marks a Structural Shift in Tech Economics,” Investing.com, February 25, 2026, https://www.investing.com/analysis/the-end-of-cheap-memory-why-2026-marks-a-structural-shift-in-tech-economics-200675634

3. Ibid.

4. Anton Shilov, “Data Centers Will Consume 70 Percent of Memory Chips Made in 2026: Supply Shortfall Will Cause the Chip Shortage to Spread to Other Segments,” Tom’s Hardware, June 3, 2026, https://www.tomshardware.com/pc-components/ram/data-centers-will-consume-70-percent-of-memory-chips-made-in-2026-supply-shortfall-will-cause-the-chip-shortage-to-spread-to-other-segments

5. TrendForce, “Memory Price Outlook for 1Q26 Sharply Upgraded; QoQ Increases of All Product Categories to Hit Record Highs, Says TrendForce,” February 2, 2026, https://www.trendforce.com/presscenter/news/20260202-12911.html; TrendForce, “AI Server Demand to Drive Memory Contract Price Increases in 2Q26 as CSPs Secure Supply via Long-Term Agreements,” March 31, 2026, https://www.trendforce.com/presscenter/news/20260331-12995.htm

6. Dave Barr, “China’s Memory Chipmakers Are Racing to Break the Korean Stranglehold on AI Infrastructure,” Startup Fortune, July 24, 2026, https://startupfortune.com/chinas-memory-chipmakers-are-racing-to-break-the-korean-stranglehold-on-ai-infrastructure/

7. Robbie Whelan, “The Memory-Chip Crisis Is Here—and You’re Footing the Bill,” Wall Street Journal, June 20, 2026, https://www.wsj.com/tech/personal-tech/memory-chip-crisis-consumer-electronics-d24cdddf

8. Mark Campbell, “SK Hynix to Prioritise DDR5 Expansion over HBM4 in New Production Push,” Overclock3D, June 23, 2026, https://overclock3d.net/news/memory/sk-hynix-to-prioritise-ddr5-expansion-over-hbm4-in-new-production-push/

9. Ibid.

10. IDC, “Worldwide Smartphone Market to Decline 13.9% in 2026 as Memory Crisis and US-Iran War Constrain Growth,” May 26, 2026, https://www.idc.com/resource-center/blog/worldwide-smartphone-market-to-decline-13-9-in-2026-as-memory-crisis-and-us-iran-war-constrain-growth/

11. Ibid.

12. Emilie Voss, quoted in Gillian Boat, “Used Car Prices at Record High, Chip Shortage and High Demand to Blame,” ABC News, February 10, 2022, https://abcnews.go.com/Business/car-prices-record-high-chip-shortage-high-demand/story?id=82776041 and Bureau of Labor Statistics, Consumer Price Index Summary, July 2021, https://www.bls.gov/news.release/cpi.nr0.htm.

13. Edward Knotek II and Saeed Zaman, “Semiconductor Shortages and Vehicle Production and Prices,” Federal Reserve Bank of Cleveland Economic Commentary, no. 2021-17 (September 30, 2021), https://www.clevelandfed.org/publications/economic-commentary/2021/ec-202117-semiconductor-shortages-vehicle-production-prices

14. AlixPartners, “Shortages Related to Semiconductors to Cost the Auto Industry $210 Billion in Revenues This Year, Says New AlixPartners Forecast”, September 23, 2021.

15. ACA Connects—America’s Communications Association et al., Letter to Secretary Scott Bessent and Secretary Howard Lutnick Regarding Memory Chip Shortages and Supply Chain Impacts, June 3, 2026, https://www.ncta.com/wp-content/uploads/2026/06/Industry-Coalition-Letter-re-Memory-Shortage.pdf

16. Ibid.

17. Scott Lincicome, “Bad Intel,” Cato Institute Commentary, August 15, 2024, https://www.cato.org/commentary/bad-intel and https://www.aei.org/foreign-and-defense-policy/the-poisoned-chalice-of-chips-act-mandates/

18. Derek Scissors, “The CHIPS Act, Part 1: Proof of Concept,” American Enterprise Institute, February 24, 2025, https://www.aei.org/foreign-and-defense-policy/the-chips-act-part-1-proof-of-concept/

19. Kate Magill, “Trump Wants to End the ‘Horrible, Horrible’ CHIPS Act. It’s Not That Simple,” Supply Chain Dive, March 12, 2025, https://www.supplychaindive.com/news/trump-to-kill-chips-act-not-that-simple-defunding/741963

20. Micron Technology, Inc., Form 8-K, U.S. Securities and Exchange Commission, June 12, 2025, https://www.sec.gov/Archives/edgar/data/723125/000110465925058741/tm2517778d1_8k.htm

21. U.S. Department of Commerce, “SK Hynix (Indiana),” CHIPS for America, NIST, https://www.nist.gov/chips/sk-hynix-indiana-west-lafayette

22. U.S. Department of Commerce, “Samsung Electronics (Texas),” CHIPS for America, NIST, https://www.nist.gov/chips/samsung-electronics-texas-austin

23. U.S. Department of Justice, “Infineon Agrees to Plead Guilty and Pay $160 Million Fine for Participating in DRAM Price-Fixing Conspiracy,” press release, September 15, 2004, https://www.justice.gov/archive/opa/pr/2004/September/04_at_621.htm

24. U.S. Department of Justice, Antitrust Division, “Samsung Korean Executive Agrees to Plead Guilty, Serve Jail Time for Participating in DRAM Price-Fixing Conspiracy,” December 21, 2006. https://www.justice.gov/archive/opa/pr/2006/December/06_at_855.html.

25. “Micron Settles Class-Action Lawsuit Alleging Price Fixing,” CNBC, January 10, 2007. https://www.cnbc.com/id/16566575

26. Melissa Lambarena, “Antitrust Class Action Accuses Micron, Samsung, and SK Hynix of Manipulating DRAM Market,” Law Street Media, April 30, 2018, https://lawstreetmedia.com/news/tech/antitrust-class-action-accuses-micron-samsung-and-sk-hynix-of-manipulating-dram-market/

27. Ibid.

28. Indirect Purchaser Plaintiffs v. Samsung Electronics Co. (In re Dynamic Random Access Memory (DRAM) Indirect Purchaser Antitrust Litigation), 28 F.4th 42 (9th Cir. 2022)

29. Jess Kinghorn, “Samsung, Micron and SK Hynix Accused of Spiking Memory Chip Prices by 700% and Restricting Supply in the DRAM Memory Chip Market,” Yahoo Finance, June 30, 2026, https://finance.yahoo.com/technology/articles/samsung-micron-sk-hynix-accused-143000032.htm

30. Jeffrey M. Jones, “Americans Oppose AI Data Centers in Their Area,” Gallup News, May 13, 2026, https://news.gallup.com/poll/709772/americans-oppose-data-centers-area.aspx

31. Empire State Development, “Micron,” accessed June 10, 2026, https://www.esd.ny.gov/micron

32. Charles-Henry Monchau, “The End of Cheap Memory: Why 2026 Marks a Structural Shift in Tech Economics,” Investing.com, February 25, 2026, https://www.investing.com/analysis/the-end-of-cheap-memory-why-2026-marks-a-structural-shift-in-tech-economics-200675634

33. Rep. Nick Langworthy, “Congressman Nick Langworthy Introduces Infrastructure Project Acceleration Act,” press release, U.S. House of Representatives, February 14, 2024, https://langworthy.house.gov/media/press-releases/congressman-nick-langworthy-introduces-infrastructure-project-acceleration-act

34. New York State Department of Environmental Conservation, Findings Statement: Micron Technology Semiconductor Manufacturing Facility Project, December 2025, https://dec.ny.gov/sites/default/files/2025-12/seqrfindingsstatementmicron.pdf

35. U.S. Department of Commerce CHIPS Program Office Record of Decision (December 17, 2025): https://www.nist.gov/system/files/documents/2026/01/15/Micron%20EIS_Draft%20Record%20of%20Decision_12172025_signed%20compliant.pdf

36. YouTube, “Shorts: hG19T7Dvzoo,” YouTube video, accessed March 13, 2026, https://www.youtube.com/shorts/hG19T7Dvzoo

37. Glenn Coin, “Who’s Behind the Lawsuit That Could Slow Micron’s Chipmaking Project in Upstate NY?” Syracuse.com, February 1, 2026, https://www.syracuse.com/micron/2026/02/whos-behind-the-lawsuit-that-could-slow-microns-chipmaking-project-in-upstate-ny.html

38. Nick Loris, “Permitting Reform Is Back On. What Should It Include?” C3 Solutions, April 27, 2026, https://c3solutions.org/policy-paper/permitting-reform-is-back-on-what-should-it-include/
Custom Fields

authors
hook
The growing memory chip imbalance largely reflects the market’s rational response to extraordinary demand driven by data centers’ needs. Nonetheless, the impact on American families and businesses could be substantial. The policy response should be to reduce government-imposed policies and regulations that could help expand supply and allocate more memory to products Americans rely on daily.
article
https://www.abundance.institute/wp-content/uploads/2026/08/21204233/AbundanceInstitute_2026_Policypaper_MemoryChip_AUG_Final.pdf
include_in_hero_section
false
category
Policy papers
topic
  • Technology
technology_subtopic
  • Artificial intelligence
article_view
article content only
social_image
hide_from_our_work
false